Understanding Siamese Networks for Real-World Similarity Tasks
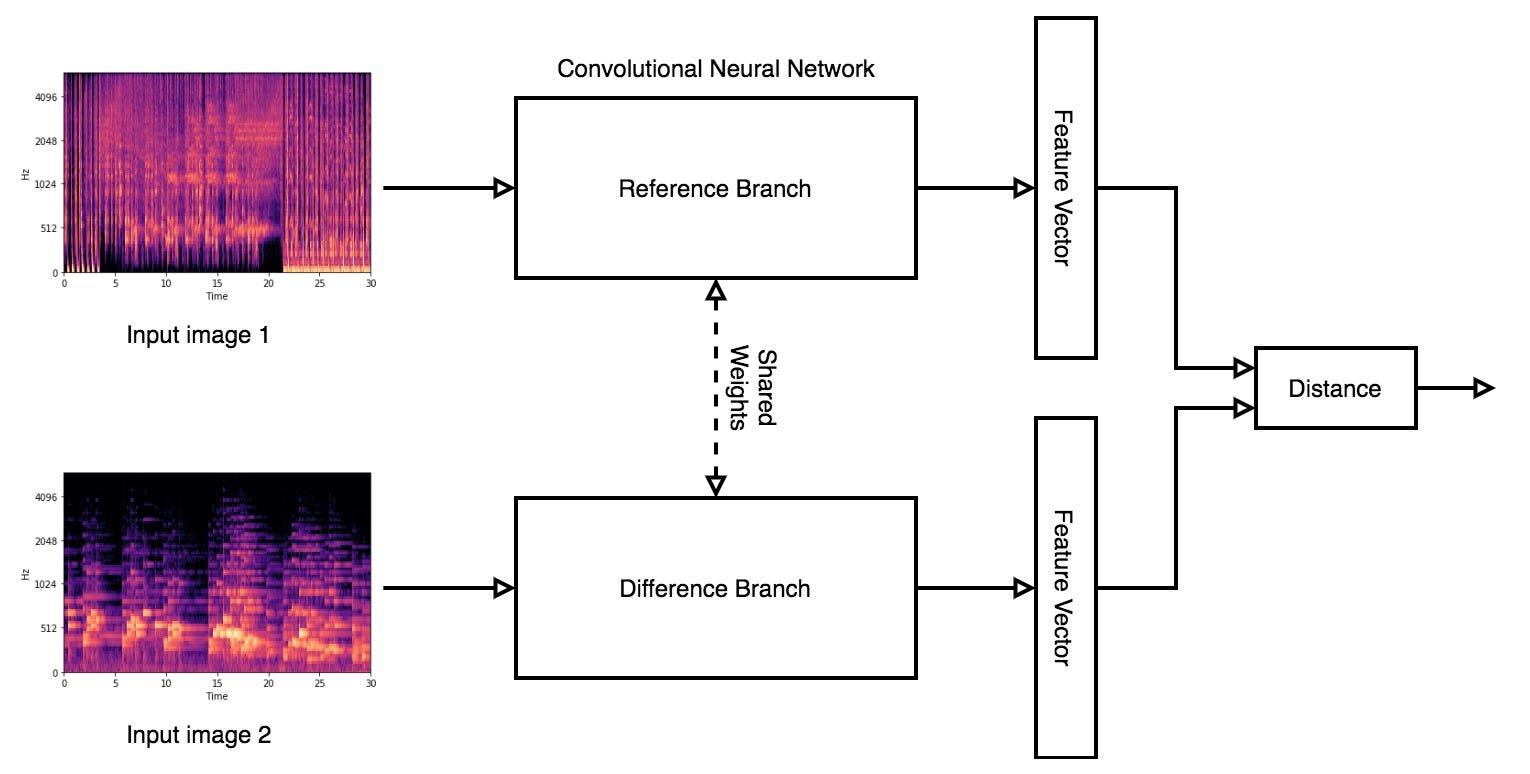
Most people approaching similarity detection start by trying to compare raw embeddings with cosine distance. That works until it doesn't, and then you spend weeks debugging why two images of the same product in completely different lighting register as dissimilar. I ran into this exact problem when building a product matching system for an e-commerce client. We had thousands of duplicate listings across vendors, and traditional hash-based deduplication was catching maybe 60 percent of actual duplicates while generating too many false positives on legitimate unique items. A Siamese network is fundamentally an architecture where two identical neural networks share weights and process two separate inputs, then combine their outputs into a single similarity score. The key insight is that you're not training the model to classify items into categories. You're training it to judge whether two inputs belong to the same class or not. This makes it particularly useful for one-shot or few-shot learning scenarios where you simply don't have enough labeled examples of every possible category.
Revolutionizing Similarity Detection How Siamese Neural Networks Are Redefining Pattern Recognition In The Digital Age
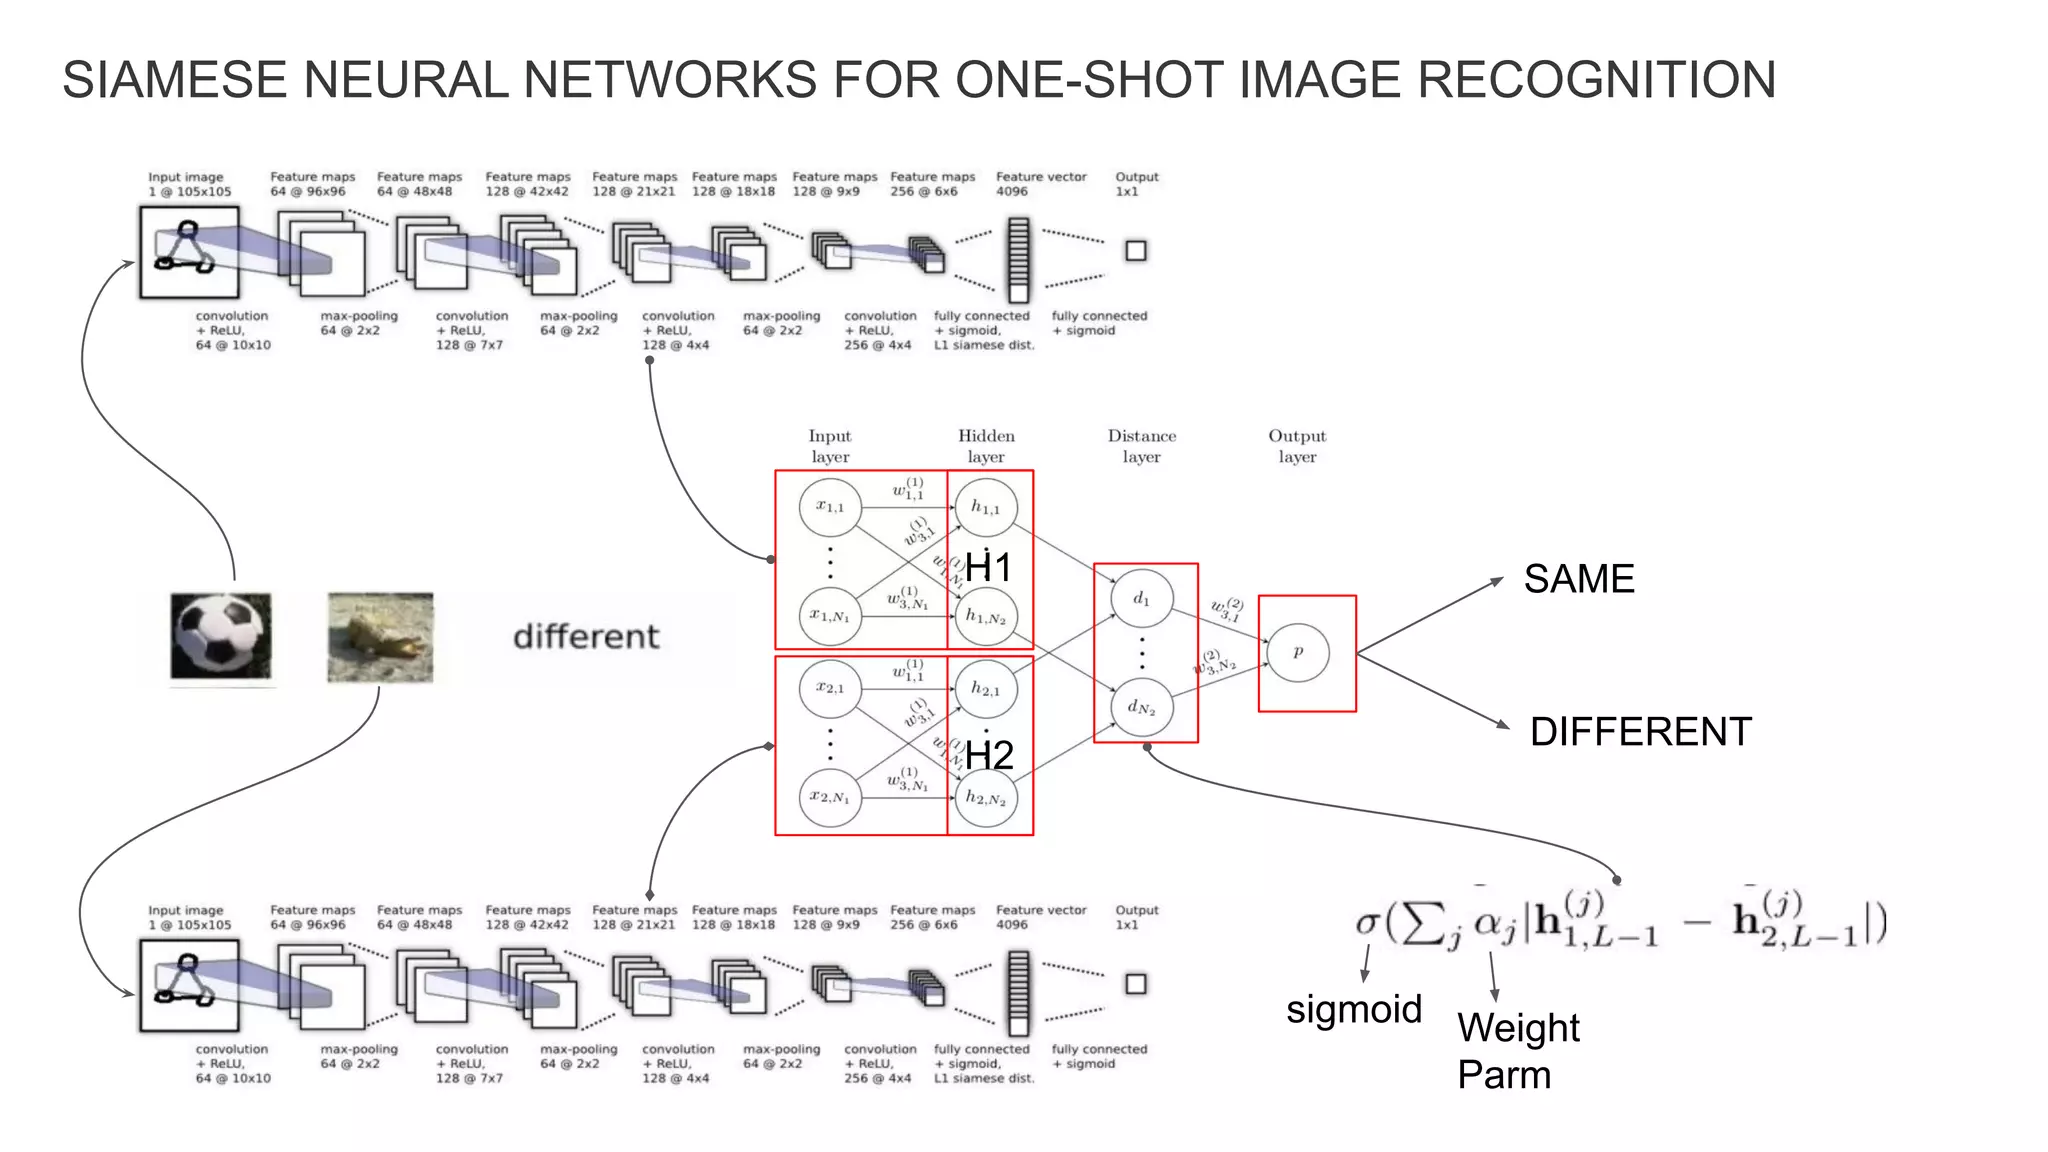
Here is how you actually build one. Start with two identical encoder branches. These can be convolutional layers for images, transformers for text, or multilayer perceptrons for tabular data. The important part is that both branches share exactly the same weights throughout training. Pass your first input through the left branch to get embedding vector A. Pass the second input through the right branch to get embedding vector B. Then compute a distance metric between those two vectors. Common choices are Euclidean distance, Manhattan distance, or cosine distance. Feed that distance through a final sigmoid layer to produce a probability between zero and one. For the loss function, contrastive loss is the standard choice. It has two components. When two inputs are similar, the loss pushes the embeddings closer together. When they are different, the loss pushes them apart but only up to a margin. That margin is critical. Without it, the network learns to collapse all embeddings into a single point because the loss keeps decreasing. I typically set the margin around 1.0 for normalized embeddings, but you should tune this on a held-out validation set. Pair generation during training is where things get interesting and where most implementations fail. You need positive pairs from the same class and negative pairs from different classes. A naive approach of randomly sampling negatives creates mostly easy negatives that teach the model very little. Hard negative mining helps. Pick negatives that the model currently scores as similar to the anchor but should be classified as different. I found that iterating hard negative mining every few epochs rather than doing it continuously gave better results and saved significant compute time.
When I was working on that product matching system, we hit a wall where the model started confidently predicting similarity between products that shared color and shape but were fundamentally different categories. A red plastic toy and a red ceramic vase looked nearly identical in embedding space. The workaround was adding a secondary loss branch that enforced class-level separation even when the primary contrastive loss wanted them close. This multi-task approach took the F1 score from about 0.72 up to 0.89 on our validation set. Training took roughly three times longer than the baseline, but the inference pipeline ran at about forty milliseconds per pair on a single GPU, which was acceptable for our batch processing needs. There are several pitfalls that catch people off guard. Training instability is the biggest one. Siamese networks are sensitive to learning rate choices because the twin architecture creates a feedback loop where both branches are optimizing simultaneously. I usually start with a learning rate around 1e-4 and use cosine annealing with warmup over the first ten percent of training steps. If you notice the loss oscillating wildly, drop the learning rate by half and check your pair distribution. Another common issue is overfitting to the pair composition in your training data. If your positive and negative ratios are severely imbalanced, the model learns a biased decision boundary. Aim for roughly equal numbers of positive and negative pairs per batch, or use online triplet mining to naturally balance them. The model architecture for the encoder matters more than most people expect. Deeper does not always mean better. A well-tuned ResNet-18 or a compact transformer with two encoder layers often matches the performance of much larger backbones on similarity tasks because the task itself regularizes the learned representations. I tested EfficientNet-B0 against ResNet-50 on an image similarity benchmark and the smaller model actually outperformed the larger one by about two percentage points in retrieval accuracy. The larger model was overfitting to texture features while the smaller one learned more structural similarities.
Get the Full Details

Data augmentation deserves careful attention. For image-based Siamese networks, random crops, flips, and color jittering help the model learn invariant representations. But be careful not to augment pairs inconsistently. If you apply a random crop to one image in a positive pair but not the other, you might accidentally make them look less similar and degrade training signal. Apply augmentations independently to each branch input, not to the pair as a whole. Evaluation metrics matter more than raw accuracy. Precision-recall curves and mean average precision give you a much clearer picture of how the model will behave in production. Accuracy alone is misleading because similarity datasets are typically imbalanced. A model that predicts everything as dissimilar might achieve high accuracy on a dataset where ninety percent of pairs are negatives, but it would be useless in practice. The main limitations of Siamese networks are worth being honest about. They require substantial training data to generalize well beyond the distribution they were trained on. A model trained on product images will struggle with document images even if both involve visual similarity. Transfer learning helps but is not a complete solution. You also need a good amount of labeled data to create proper positive and negative pairs. Semi-supervised approaches and self-supervised pretraining can reduce the annotation burden, but they add complexity that may not be worth the effort for smaller projects.
Inference speed is generally fast once the model is trained, but the twin architecture means you are running two forward passes for every pair. If you need to compare one query against thousands of candidates, compute the query embedding once and store candidate embeddings in an approximate nearest neighbor index like FAISS. This reduces the computational cost dramatically and is standard practice in any production system handling large-scale similarity search. If your use case involves fixed categories with thousands of labeled examples, a standard classification model with cosine similarity on top might be simpler and sufficient. Siamese networks shine when categories are numerous, labels are scarce, or the similarity relationship is inherently pairwise rather than absolute. Knowing when not to use them is as important as knowing how to build them.