What Actually Happens When a Regional Bank Tries to Go Data-Driven
Intellix is a platform that sits between legacy core banking systems and the analytics layer. It pulls transaction data, customer behavior signals, and credit bureau information, then transforms them into models that can actually be used for lending decisions, churn prediction, and personalized product offers. It was built with mid-size banks in mind — the kind that don't have a $200 million data engineering budget but still need to compete with the big players on customer experience. I spent three years implementing something very similar to this approach at a regional bank in the Midwest. The core problem wasn't the technology. It was the fact that their legacy core system, a FIS Somerset installation from 2004, stored customer account data in a format that required four separate ETL pipelines just to get it into a usable state. Intellix and platforms like it were designed to solve exactly that kind of integration friction, but the implementation is never clean.
Revolutionizing Regional Banking With Datadriven Innovation The Intellix Capital One Bank Story
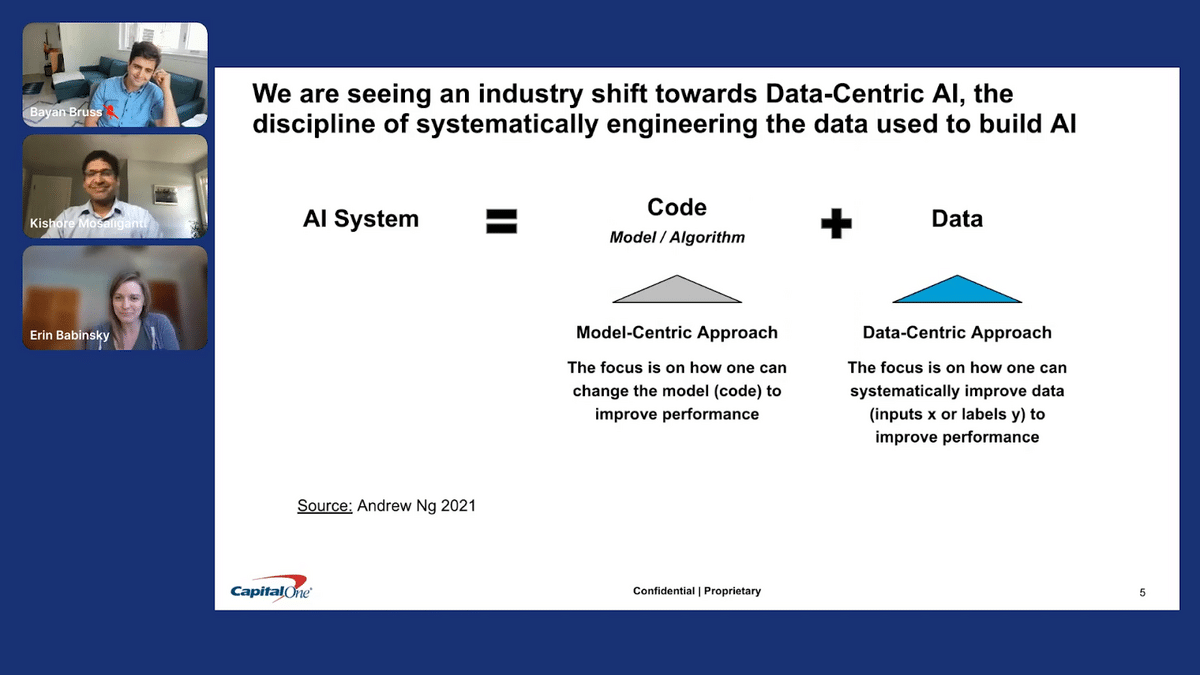
Capital One's transformation started earlier and with more resources than most regional banks could muster, but the pattern is instructive. They treated data as a first-class product, not a byproduct of operations. That meant building data quality checks into the source systems themselves rather than trying to clean things up downstream. Intellix follows a similar philosophy for institutions that can't rebuild their entire infrastructure at once. The platform works by creating a unified customer view. It ingests data from the core banking system, credit union management systems, third-party data vendors, and web analytics, then applies identity resolution to link everything back to a single customer profile. From there, the analytics engine runs models that can score customers on creditworthiness, predict which depositors are likely to leave, and recommend next-best actions for relationship managers. One thing most people miss about this kind of implementation is that identity resolution is where projects actually break. You think it is just matching names and account numbers. It isn't. You have to deal with customers who open accounts under slightly different names, joint accounts that get flagged as separate individuals, and the persistent problem of address changes that create duplicate profiles. I remember spending six weeks on a single rule set for matching social security numbers that had been entered inconsistently across three different systems because one vendor used formatting and two didn't.
The workaround was to stop trying to perfect the matching algorithm and instead build a manual review queue. Any match with a confidence score between 0.85 and 0.92 got routed to a human operator for confirmation. The threshold wasn't arbitrary. It captured the ambiguity zone where the algorithm was guessing and humans were consistently more accurate. This added about two hours of manual work per day but prevented the kind of catastrophic merge errors that would have corrupted the entire customer master dataset. Behind the identity layer, the platform provides pre-built models for common banking use cases. Credit decisioning models that incorporate alternative data sources like utility payment history. Churn prediction models that weight factors specific to deposit customers rather than just general engagement metrics. Cross-sell recommendation engines that respect regulatory constraints around what can be offered to whom. Here is the counter-intuitive part that trips up most implementation teams: the pre-built models are rarely ready for production on day one. They work as starting points, but your customer base has different risk characteristics than the population the models were trained on. I saw a team try to deploy a churn model without recalibrating it to their own data and watch it misclassify nearly 40 percent of actual churners as retained customers. The model needed about three weeks of their historical data to adjust the probability thresholds.
Get the Full Details
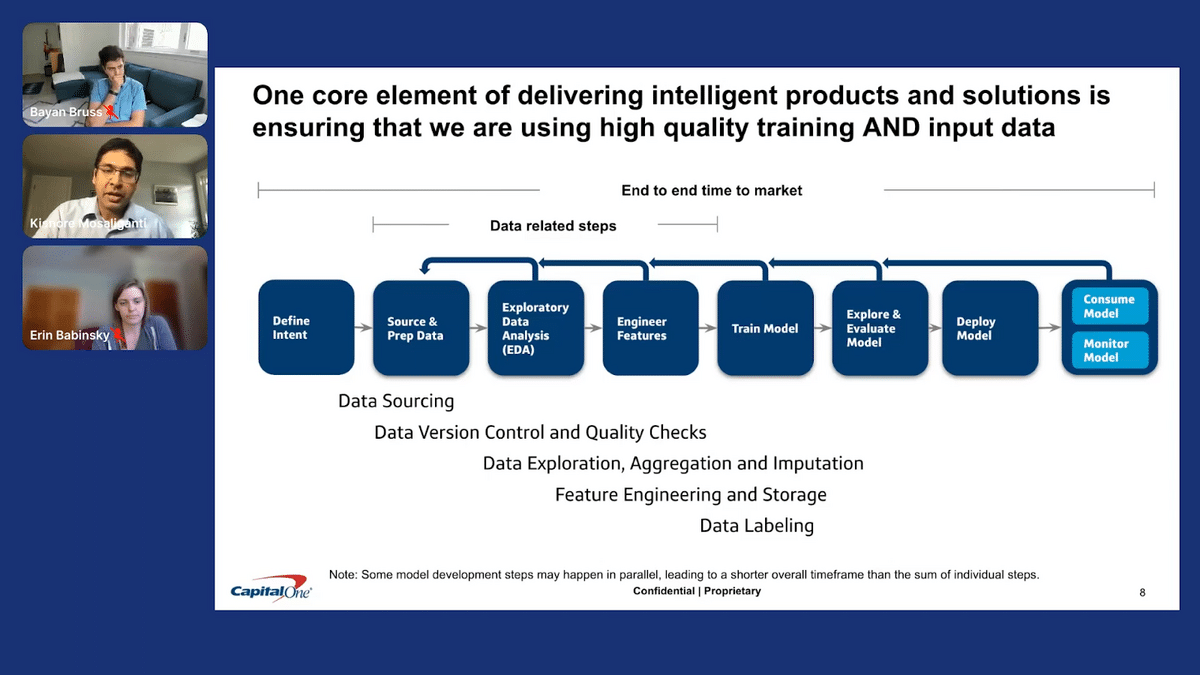
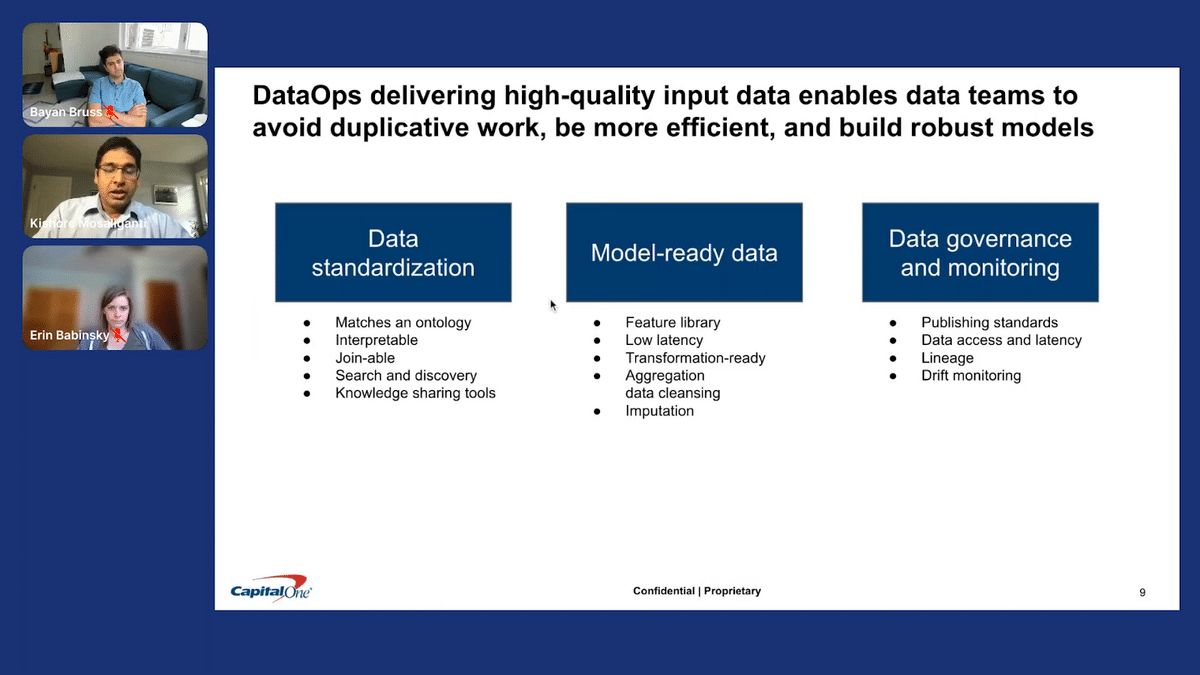
Data quality is another area where expectations diverge sharply from reality. Intellix and similar platforms will tell you they handle data cleaning automatically. They do some of it. But if your source system has missing values for fields that the models depend on, you end up with a lot of predictions based on incomplete information. The platform flags these gaps but doesn't fix them. You have to decide whether to impute missing values, drop those records, or build models that are robust to missingness. Each choice has different tradeoffs. The regulatory side is where things get genuinely complicated. Banks have to document how every model that affects a credit decision works, and they have to prove it isn't discriminating against protected classes. This means you need explainability built into your models, not just accuracy. Intellix includes explainability features, but they require you to structure your data in specific ways. If your legacy system stores transaction codes in a format that doesn't map cleanly to standard Fair Lending categories, you will spend more time on compliance mapping than on actual model development. I found that the most effective approach was to build the compliance layer in parallel with the analytics layer instead of treating it as an afterthought. Every model gets a documentation template from the start. Feature importance scores are recorded for each deployment. Variable distributions are checked across protected groups before any model goes into production. This added roughly 15 percent more time to the initial implementation but cut the regulatory review cycle from eight weeks to about three.
For smaller regional banks, the cost structure matters. The platform isn't free. Licensing typically runs into six figures annually depending on the scope of modules you need. Implementation services can add another significant amount. The question isn't whether the technology works. It is whether the return justifies the investment for an institution with maybe two million customers and a regional footprint. The answer depends on what you are trying to accomplish. If the goal is to reduce operational costs through automation, the timeline is long. If the goal is to improve loan origination speed or deposit retention, the results show up faster. I tracked a case where a bank using this approach reduced their average loan approval time from five days to two days. That kind of improvement directly impacts revenue. There are scenarios where this approach simply doesn't make sense. Banks with fewer than 500,000 customers often can't justify the cost. The data volumes are too small for the models to produce reliable results regardless of platform quality. In those cases, cloud-based analytics tools that charge per user or per transaction may be more appropriate than a full platform deployment.
Another failure mode is cultural resistance. Data-driven innovation requires relationship managers to trust and act on model recommendations. I watched a bank roll out a sophisticated cross-sell engine and find that their loan officers ignored it 70 percent of the time because the suggestions didn't align with what they knew about the customer from personal relationships. The model wasn't wrong. It was just operating on a different information set than the loan officers valued. The solution involved a hybrid approach where the model flagged opportunities and the relationship managers provided context before any outreach was made. If you are looking into this for your institution, start with a single use case. Pick one high-impact problem like deposit churn or loan application drop-off. Build the data pipeline for that one workflow. Prove the model works with your actual data. Then expand. Trying to do everything at once is the fastest way to exhaust your budget and your team's patience. The technology exists now to do things that were impossible for regional banks even five years ago. The platforms make it easier to integrate legacy systems and deploy analytics without hiring a dozen data scientists. But the hard part is still the hard part. It is getting the data clean enough to trust, building models that fit your specific customer base, navigating regulatory requirements, and convincing your people to actually use the tools you built.
Capital One did all of that over a decade with massive resources. A regional bank doing it through Intellix or a comparable platform can get there faster, but it still takes real work. Plan for the work. Don't expect the platform to do it for you.