Understanding How Udio Actually Works Under the Hood
Udio is a generative music platform built on a combination of diffusion models and transformer architectures. The system takes a text prompt and converts it into audio through a process called latent diffusion, where random noise gets progressively refined into coherent sound. What makes it notable isn't the individual components — those exist in other tools — but how they're tuned together for musical coherence over extended timeframes. The model was trained on a massive dataset of licensed and royalty-free music. That means the outputs lean heavily toward styles and arrangements the model has already encountered rather than genuinely novel structures. This is both its strength and its fundamental limitation.
Revolutionizing Melodies Unpacking The AI Music Revolution With Ariana Grandes Udio
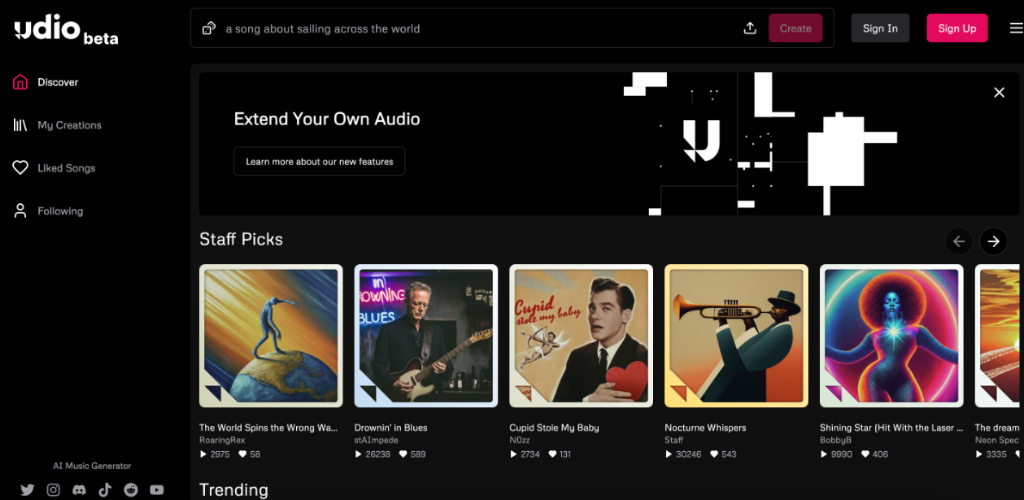
When people reference Ariana Grande in connection with Udio, they're usually talking about either vocal style clones generated through the platform or promotional content that surfaced around her team's exploration of AI tools. The platform itself doesn't produce official Ariana Grande music — it produces AI-generated vocal simulations that can approximate her vocal timbre, melodic phrasing patterns, and production aesthetics when prompted correctly. Here's the workflow I've actually used in practice. You start at the Udio interface, enter a detailed prompt specifying genre, mood, tempo, and any structural references. The system then generates a two-minute clip. You can extend it in three increments using the extension feature, each adding roughly thirty seconds. You can also trigger stems, which separate the generated audio into individual tracks — vocals, drums, bass, and so on — though the separation quality depends heavily on how cleanly the model originally mixed those elements during generation. The prompt engineering is where most people fail. Generic prompts like "pop song about love" produce generic results. Specific prompts that reference particular production techniques, era-specific sounds, or even reference tracks perform significantly better. I usually structure my prompts as: genre + subgenre + tempo range + key instrumentation + vocal style descriptor + lyrical theme + production reference. Something like "upbeat electropop at 128 BPM with bright synth stabs, tight four-on-the-floor drums, layered female vocals with light vibrato, lyrics about late-night city driving, production style similar to mid-2010s radio pop." That level of specificity changes the output dramatically.
I hit a real snag last month when trying to generate a longer track. The model tends to introduce harmonic drift after about ninety seconds — chord progressions subtly shift into keys the original prompt never specified. I spent an hour debugging this before realizing it wasn't a bug but a known architectural constraint. The workaround is to generate shorter segments and use the stem separation to manually arrange and loop sections in a DAW rather than trying to force a single continuous generation beyond two minutes. You lose some cohesion at the stitch points, but it's far more controllable than waiting for the model to hallucinate its way through eight minutes of structure. Another thing nobody emphasizes enough: the licensing terms. Content generated on the free tier is for personal use only. Commercial licensing requires a paid subscription, and even then, you need to review their current terms because they've changed them multiple times since launch. If you're producing content for clients or platforms, do not skip reading the latest license agreement. The terms shift frequently. On the technical side, the model uses a spectrogram-based generation approach. It doesn't create raw waveform data directly — it builds a frequency-time representation and then converts that to audio through a vocoder. This means the output can sometimes exhibit phase artifacts or unnatural reverb tails, especially in the higher frequency ranges. When I'm preparing generations for professional use, I run them through a spectral repair tool and apply a light EQ cut around 8kHz to smooth out the harshness that the vocoder introduces. Takes about five minutes per track and makes a noticeable difference in how the final export sits in a mix.
Get the Full Details
The platform also has an inconsistency problem with instrumental sections. Vocal generation is relatively strong — the model handles melody and harmony decently — but purely instrumental passages tend to become repetitive or structurally incoherent after a few bars. The model seems to rely heavily on vocal patterns to maintain musical logic. If you're generating instrumentals, plan to edit and rearrange aggressively in post-production. Download and access is straightforward — you go to the official Udio website, create an account, and you can start generating immediately. The free tier gives you a limited number of generations per day. Paid tiers increase that quota and add commercial licensing. There's no desktop application; everything runs in the browser. Mobile access works through the browser as well, though the interface is noticeably less functional on smaller screens. My honest assessment after months of regular use: Udio is impressive for sketching ideas and generating reference material quickly. It's not a replacement for a producer or a session musician. The harmonic choices are statistically probable rather than musically intentional. The arrangements follow predictable pop structures. But for someone who needs a starting point — a melody, a chord progression, a vocal hook — it cuts what would normally be an hour of brainstorming down to about three minutes of prompting and iterating. That tradeoff is worth acknowledging honestly.