Getting Market Data to Actually Make Sense
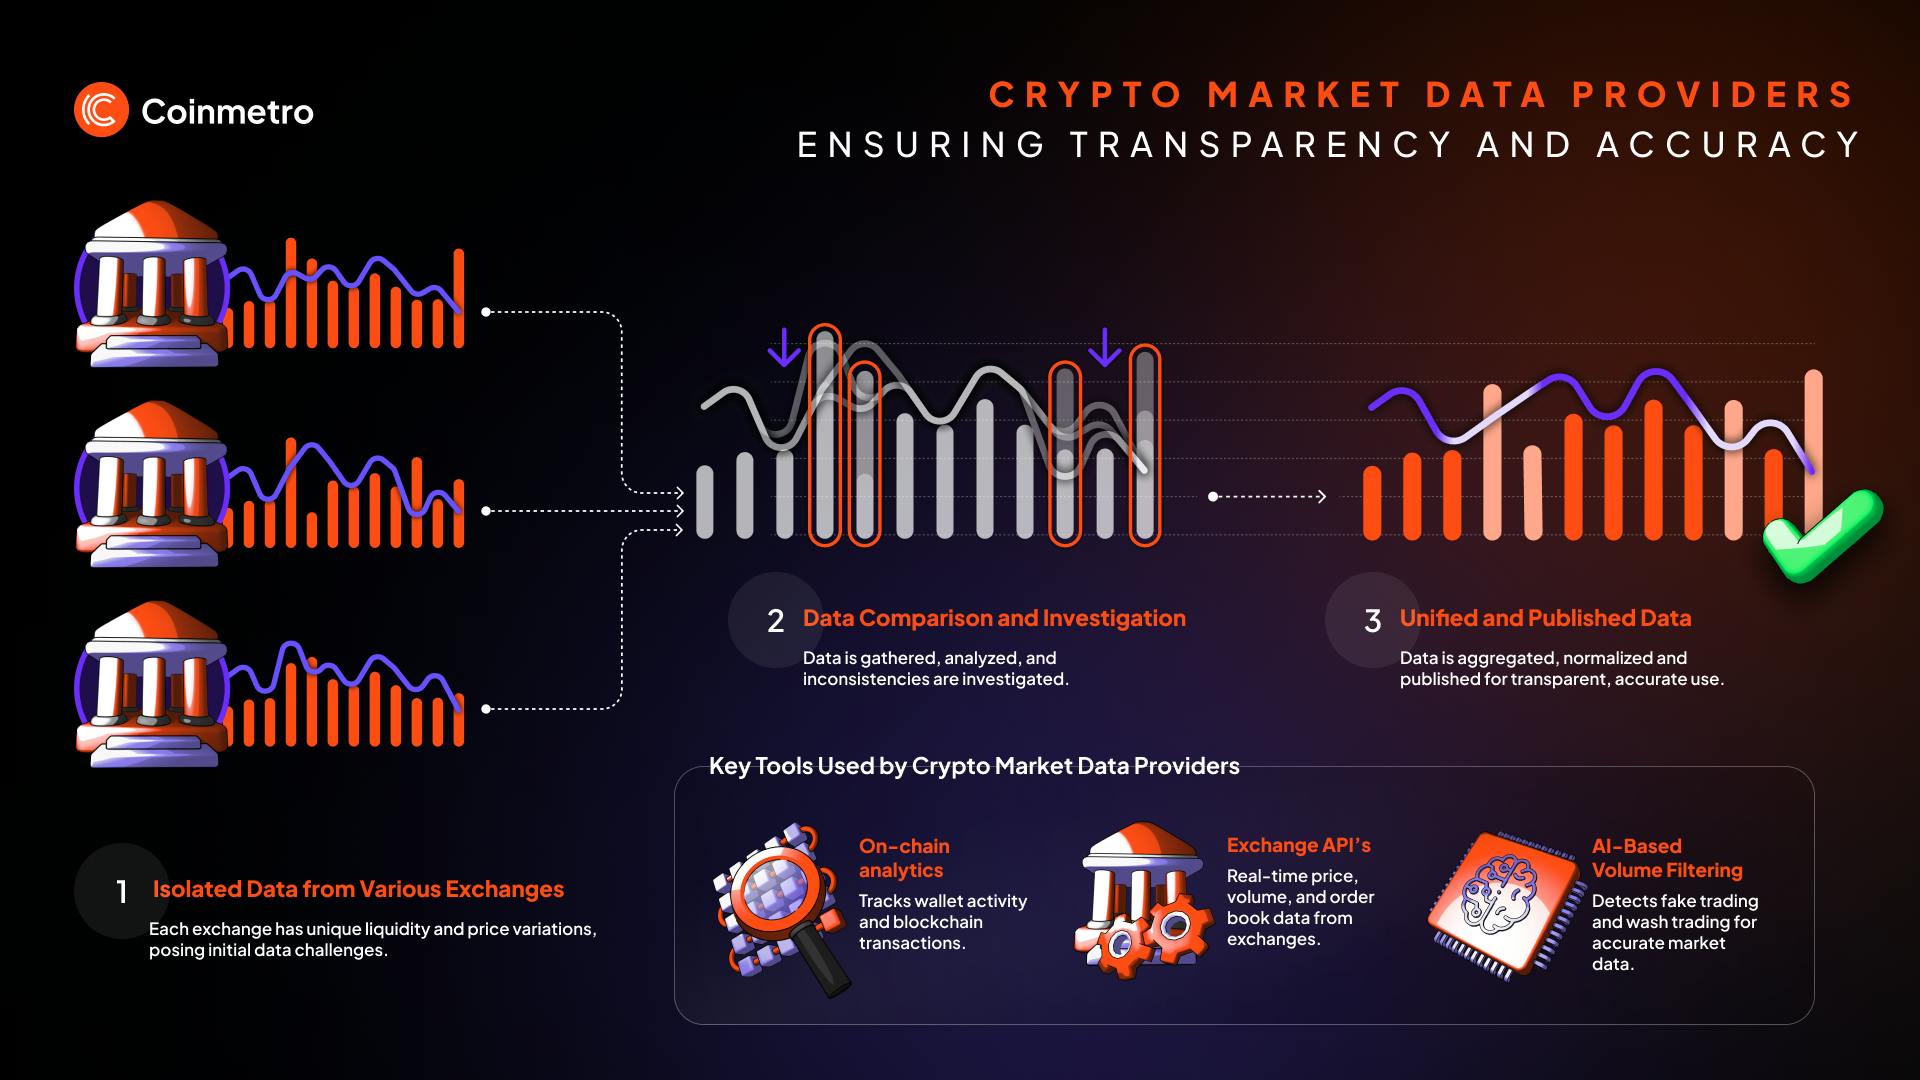
Most people look at crypto market data and see noise. What they're really looking at is a fragmented mess of price feeds from a dozen different exchanges, each with slightly different timestamps, different liquidity pools, and different ways of handling outages. The data isn't wrong. It's just inconsistent enough that any analysis built on top of it is probably off by somewhere between two and eight percent depending on which exchange you trust most on any given day. I ran a volatility arbitrage model last year that was quietly losing money despite looking profitable in backtests. The problem wasn't the model. It was that I was pulling order book depth from Binance and Coinbase simultaneously without realizing their snapshot intervals didn't align. Binance does 100-millisecond updates during active hours. Coinbase does roughly 500 milliseconds but sometimes batches them. My latency correction factor was built for uniform intervals. I ended up seeing depth that existed a quarter-second before it actually existed in Coinbase's books. A quarter second is an eternity in this market. Took me about six hours of manually logging individual snapshots to figure out what was happening.
Revolutionizing Market Data Analytics With Cryptoquote Solutions
Cryptoquote Solutions is essentially a normalization layer that sits between raw exchange APIs and whatever you're using to make decisions. It takes the raw feed, aligns timestamps across sources, reconciles missing ticks, and gives you a single coherent view of market conditions. That sounds like oversimplification because it is. The actual value is in the messy middle parts. Here's what the setup looks like if you're starting from scratch. First, you need API keys from at least three major exchanges. Don't use just two. Two is a convenience sample. Three lets you actually spot when one is lying to you. I learned that the hard way during the Luna collapse when one exchange paused withdrawals for four hours and kept showing pre-pause prices to its API consumers. The other two had already frozen. If you're only connected to the one that wasn't frozen, your analytics are telling you a story that isn't true. After you have the keys, you configure Cryptoquote to pull from each source on staggered intervals. This prevents a thundering herd problem where all three exchanges hit your aggregator simultaneously and you get rate-limited on all of them. Ten millisecond offsets between sources is usually enough. You'll lose a tiny bit of synchronization precision but your throughput stays stable.
The timestamp alignment step is where most implementations fail. Exchanges use different base clocks. Some report in UTC, some in local time, some include the exchange's own offset. Cryptoquote normalizes everything to a single epoch reference point. But here's what the documentation doesn't emphasize enough: you also need to account for network propagation delay. A trade reported at 14:32:00.000 UTC from Exchange A might have actually executed at 14:31:59.780. If you're doing high-frequency analysis, that gap matters. I wrote a small adjustment script that uses mean time-of-flight estimates based on historical ping data to each exchange's API endpoint. It shaved about 0.3 seconds off my effective latency on average. Not huge, but enough to change which strategies are profitable. Data reconciliation is the next hurdle. When one exchange goes dark for thirty seconds, you don't want your model to think price dropped thirty percent and then recovered. Cryptoquote fills those gaps using interpolation weighted by the other exchanges' data, with a confidence score attached to each imputed value. You should be looking at those confidence scores every single time you pull a report. I've seen too many people ignore them and treat interpolated values the same as real ones. That's how you get surprised. Once the pipeline is running, the analytics layer becomes useful. You can track cross-exchange spreads in real time, detect when an exchange is lagging behind the rest of the market, and identify arbitrage windows that only exist because of synchronization errors rather than actual price dislocation. The last one is important. A lot of apparent arbitrage opportunities are just artifacts of bad data alignment. Cryptoquote's reconciliation process surfaces these so you stop wasting time chasing ghosts.
Get the Full Details

There are limitations you need to accept upfront. Cryptoquote can't create data that doesn't exist. If an exchange doesn't publish certain order book levels, you won't get them. It can't fix systemic issues like exchange manipulations or wash trading that inflate volume numbers. During high-volatility events, interpolation confidence drops sharply and you should treat all derived metrics as directionally approximate rather than precise. I usually switch to a simpler moving average approach during those windows instead of relying on the more sophisticated models that assume stable conditions. Another problem: the solution adds latency. Even with the staggered pulls and efficient processing, you're introducing a middleware layer between the raw feed and your analysis. If your strategy depends on sub-10-millisecond execution, Cryptoquote alone won't help you. You'd need to either bypass it for the critical path and only use it for broader market context, or accept that you're trading accuracy for speed depending on which part of the pipeline you're using. For most people building portfolio-level or swing-trading analytics though, this is where the real value sits. The tool is available through their website and you'll find the setup documentation fairly complete. The confusing parts aren't in the docs. They're in the edge cases like timestamp drift during network congestion or exchanges that silently change their API response format without announcement. I'd recommend setting up alerting on any metric that suddenly changes standard deviation by more than two percent. That's usually your signal that something upstream shifted and you need to verify your pipeline before trusting the next day's numbers.
The bottom line is that market data in crypto is fundamentally unreliable by design. Every exchange is optimizing for its own survival, not for your analysis. Cryptoquote Solutions gives you enough structure to build something that at least tries to be honest about what it knows and what it's guessing. That's about as good as it gets.