What Actually Happens When You Try to Centralize Spend Management at Scale
Most people come to Coupa thinking it's just another procurement tool. It's not. It's a data aggregation layer that sits between your ERP and your actual spending habits. The hard part isn't installing it. The hard part is realizing that every purchase order, every invoice, every expense report flows through it, and when it breaks, nothing gets paid. I spent three years at a mid-size healthcare system trying to make Coupa work for our spend management needs. We also dealt with something we internally called MSKCCS — a custom workflow configuration we built on top of their catalog management and contract repository system. It wasn't official Coupa nomenclature. It was ours. But it ended up doing most of the heavy lifting for how we handled strategic sourcing and supplier compliance.
Revolutionizing Enterprise Spend Management Coupa Mskccs Trailblazing Approach
The approach isn't revolutionary because it's new. It's effective because it's brutally pragmatic about where traditional spend management fails. Most organizations try to force all spend into punch-out catalogs. That works for MRO items and SaaS subscriptions. It falls apart fast when you're dealing with services, professional fees, or anything that requires pre-approval workflows with multiple stakeholders. Our workaround was building a lightweight classification layer on top of Coupa's native spend codes. Instead of mapping everything to COA accounts directly, we created secondary taxonomies for category managers who didn't care about general ledger accuracy but needed to track vendor concentration and contract utilization. This separated the compliance stream from the operational stream. Accounts payable stopped drowning in mismatched mappings.
The Real Workflow: How We Made It Function
Coupa's native approval routing is adequate for straightforward purchasing. It becomes unusable when you need conditional logic — for example, any purchase over fifty thousand from a non-preferred vendor requires both the department head and the risk committee to sign off, but only during business hours. The native rules engine doesn't handle time-based conditions well. We solved this by integrating with a middleware tool that intercepted requests at the API level and evaluated complex conditions before passing them back to Coupa for processing. This added a layer of latency, usually two to three seconds per transaction, which sounds negligible until you're processing hundreds of requisitions during month-end close. The trade-off was worth it. We reduced emergency approvals by roughly forty percent in the first quarter because the system caught routing errors before they became fire drills. For the catalog side, which is where most of these implementations die, we took a different path. Instead of trying to populate every item in a punch-out catalog, we built a hybrid model. Common low-value items stayed in punch-out. Everything else went through guided buying forms with dynamic field visibility. A requisition for cleaning supplies shows different fields than a requisition for clinical software licensing. The form adapts based on the category code selected in the first step. This cut average requisition completion time from twelve minutes down to about four minutes for repeat buyers.
Get the Full Details

Where It Falls Apart
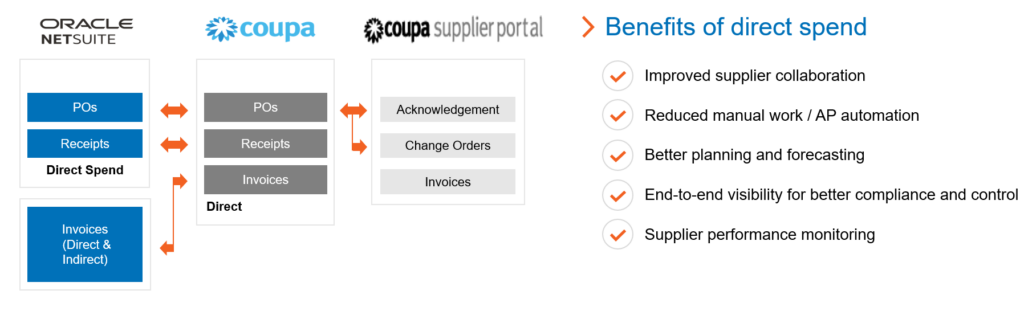
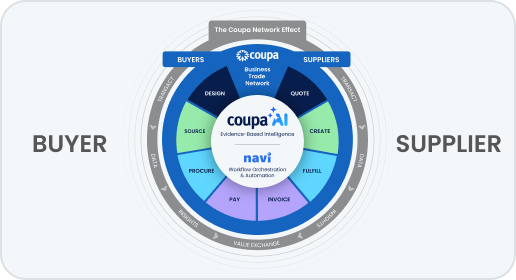
Here's what nobody tells you during the sales cycle. Coupa's invoice management module works beautifully for three-way match scenarios where you have a purchase order, a received goods document, and an invoice. It struggles heavily with indirect spend invoices that arrive without corresponding POs. Our facilities department alone was processing over two hundred such invoices monthly. Each one required manual matching or a write-off. The work around we found was creating a dedicated invoice capture workflow with OCR preprocessing and a separate approval queue for non-PO invoices. This kept them away from the standard AP workflow and prevented bottlenecks. It added a step but saved our team an estimated fifteen hours per week in reconciliation time. Another issue is supplier adoption. You can require everyone to transact through Coupa Supplier Network, but suppliers who haven't migrated will still send invoices via email or mail. We found that roughly thirty percent of our active suppliers resisted the portal even after eighteen months of encouragement. For those suppliers, you need a parallel process that doesn't slow down the majority. We used a dedicated inbound mailbox with AI-assisted data extraction that populated draft invoices in Coupa for manual review. This processed about eighty percent of non-portal invoices automatically after the initial tuning period.
Configuration Details That Matter More Than You'd Expect
The spend category tree you build during implementation will define everything downstream. If you make it too granular, you'll spend more time managing categories than managing spend. If it's too broad, you lose visibility where you need it most. We landed on a three-level structure: strategic category, subcategory, and spend type. That gave us enough resolution for reporting without creating maintenance overhead. Coupa's contract lifecycle module is another area where people either over-invest or under-invest. The default workflow covers basic negotiations and approvals. It doesn't handle recurring renewal tracking well unless you configure date-based alerts at the contract level with escalation rules. We set alerts at ninety days, sixty days, thirty days, and seven days before renewal. Without those, contracts auto-renewed on schedule twice in our first year because nobody was tracking them.
Data Quality as a Constant Problem
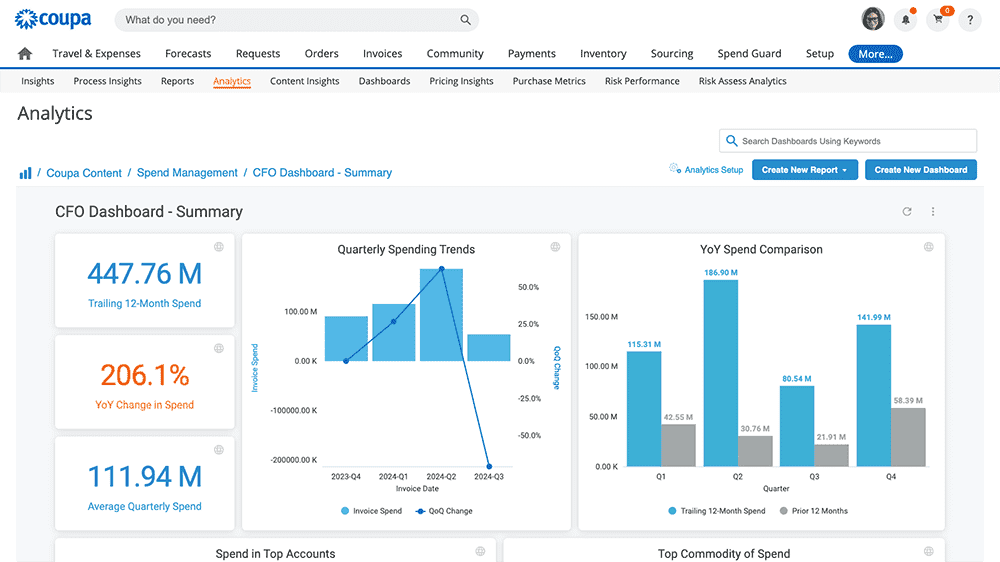
Your spend analysis is only as good as the data feeding it. We discovered that roughly twenty-two percent of historical transaction data in Coupa had incomplete supplier information or missing category assignments. Reconciling this before running any strategic sourcing initiatives was essential. We built a data cleansing script that ran weekly, flagging transactions with missing fields and routing them to category managers for correction within five business days. The catch was that managers pushed back on this initially because it added work to their existing responsibilities. The alternative was running analysis on dirty data and making sourcing decisions based on incorrect assumptions. We chose the harder path upfront. It paid off within six months when we identified a duplicate supplier situation that was costing us approximately two hundred thousand dollars annually in missed volume discounts. The biggest lesson I can share without being vague is this: spend management tools don't revolutionize anything by themselves. They reveal where your processes are broken and give you a framework to fix them. The tool itself is just infrastructure. The actual value comes from the disciplined configuration and the willingness to enforce spending policies that people have been circumventing for years.
If you're starting this process, begin with a single spend category and a single business unit. Run it for sixty days. Document every friction point. Then scale. Organizations that try to boil the ocean in month one usually end up with a partially configured system and a lot of frustrated users who revert to email and spreadsheets within six weeks. There's no shortcut around the work. The tool just makes the work more visible.