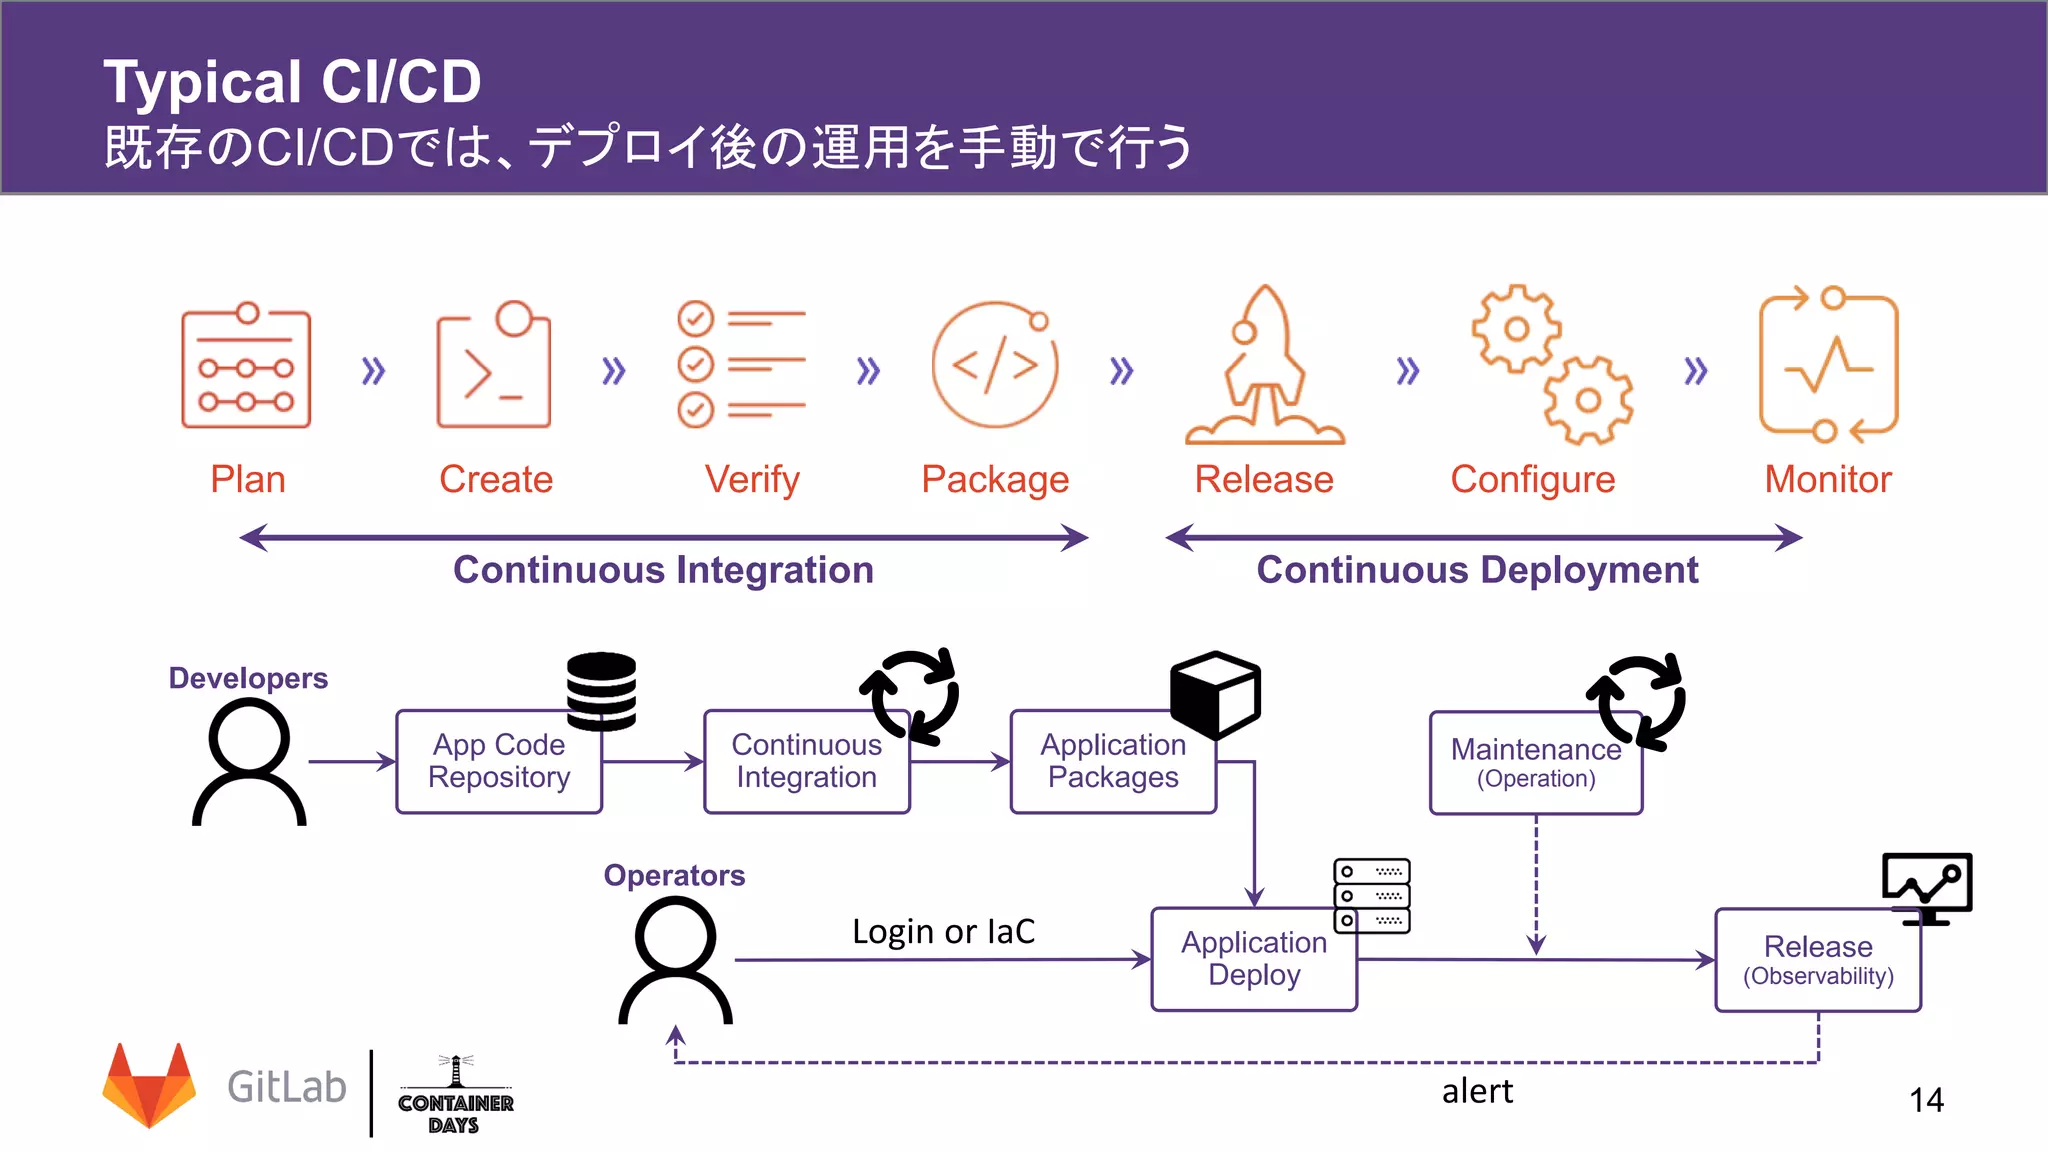
Setting Up a Functional GitLab CI/CD Pipeline for Your Team
GitLab's CI/CD is probably the most accessible platform-based solution available right now, but most teams set it up wrong and then wonder why their pipelines break constantly. I have watched project after project stall because people treat GitLab CI/CD as just another thing to bolt onto their repo instead of actually designing the pipeline around their deployment reality. Community Managed User Groups, commonly called CMUGs, exist in the GitLab ecosystem because the official documentation covers theory far better than it covers the messy edge cases that hit you in production. These user groups share real configuration patterns, workaround scripts, and actual pipeline structures that work. That is where I got most of my working knowledge from. Let me walk through the setup process as it actually plays out, not the textbook version.
First, you need a .gitlab-ci.yml file at the root of your repository. That is non-negotiable. GitLab will not auto-detect your CI/CD configuration from anything else. Put it there and start with a basic structure before overcomplicating it.
The Pipeline Structure That Actually Works
Here is what I use as a starting point. It is not fancy, but it covers the essentials without assuming your infrastructure is perfect. This is a flat pipeline. One job per stage. It is boring, but it works reliably. The problem most teams run into is trying to do too much in a single pipeline file. When you have twenty jobs and three conditional branches, debugging a failure becomes a full-time job in itself. The first issue that hits everyone is parallel job execution. GitLab runners are shared resources on the free tier and heavily contended on shared runners. If you are running on a shared runner and your test stage takes longer than your build stage, you will see pipeline queues building up. The fix is straightforward: configure a dedicated runner for your project. Even a cheap VPS with Docker installed handles this far better than fighting for queue space on a shared runner.
Get the Full Details

The second issue is cache management. GitLab has built-in cache support for dependencies, but it does not clean up automatically unless you configure expire_in on your artifacts. I once had a pipeline fail silently for three hours because the cache was corrupted from a partial upload six months ago. There was no error message pointing to the cache. The job just timed out. Adding a cache key based on the lock file and setting a reasonable expiry fixed it. Here is the cache configuration I use after learning that lesson:
cache:
  key: "${CI_COMMIT_REF_SLUG}-node"
  paths:
    - node_modules/
  policy: pull-push
The pull-push policy means GitLab will fetch the cache on every run and update it after the job completes. Without it, your cache becomes stale and you start getting phantom dependency errors that look like code problems but are not. GitLab provides protected and masked variables through the project settings interface. Use them. Do not hardcode credentials in your pipeline files. This sounds obvious, but I have seen it happen repeatedly. People copy paste configuration from forums and accidentally commit API keys into the repository history. Set your secrets under Settings > CI/CD > Variables. Mark sensitive ones as masked and protected. Protected variables only apply to protected branches like main, which prevents unauthorized merge requests from leaking them into downstream pipelines.
One thing the documentation does not emphasize enough: variable scope matters more than people realize. A project-level variable overrides a group-level variable, which overrides a shared runner variable. If you are managing multiple projects and one breaks after someone changes a runner variable, check the inheritance chain before anything else. I spent two days once troubleshooting a deployment failure that came down to a group variable being accidentally overridden by a newer project variable with the same name.
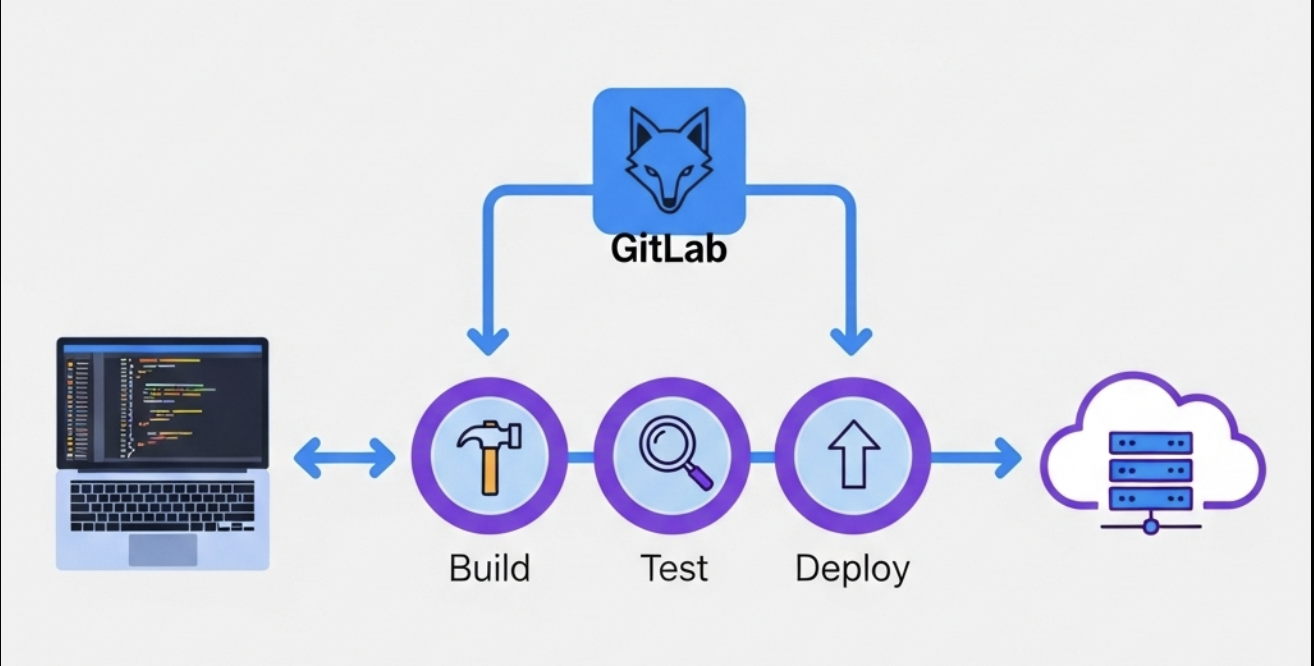
Connecting to Your Infrastructure
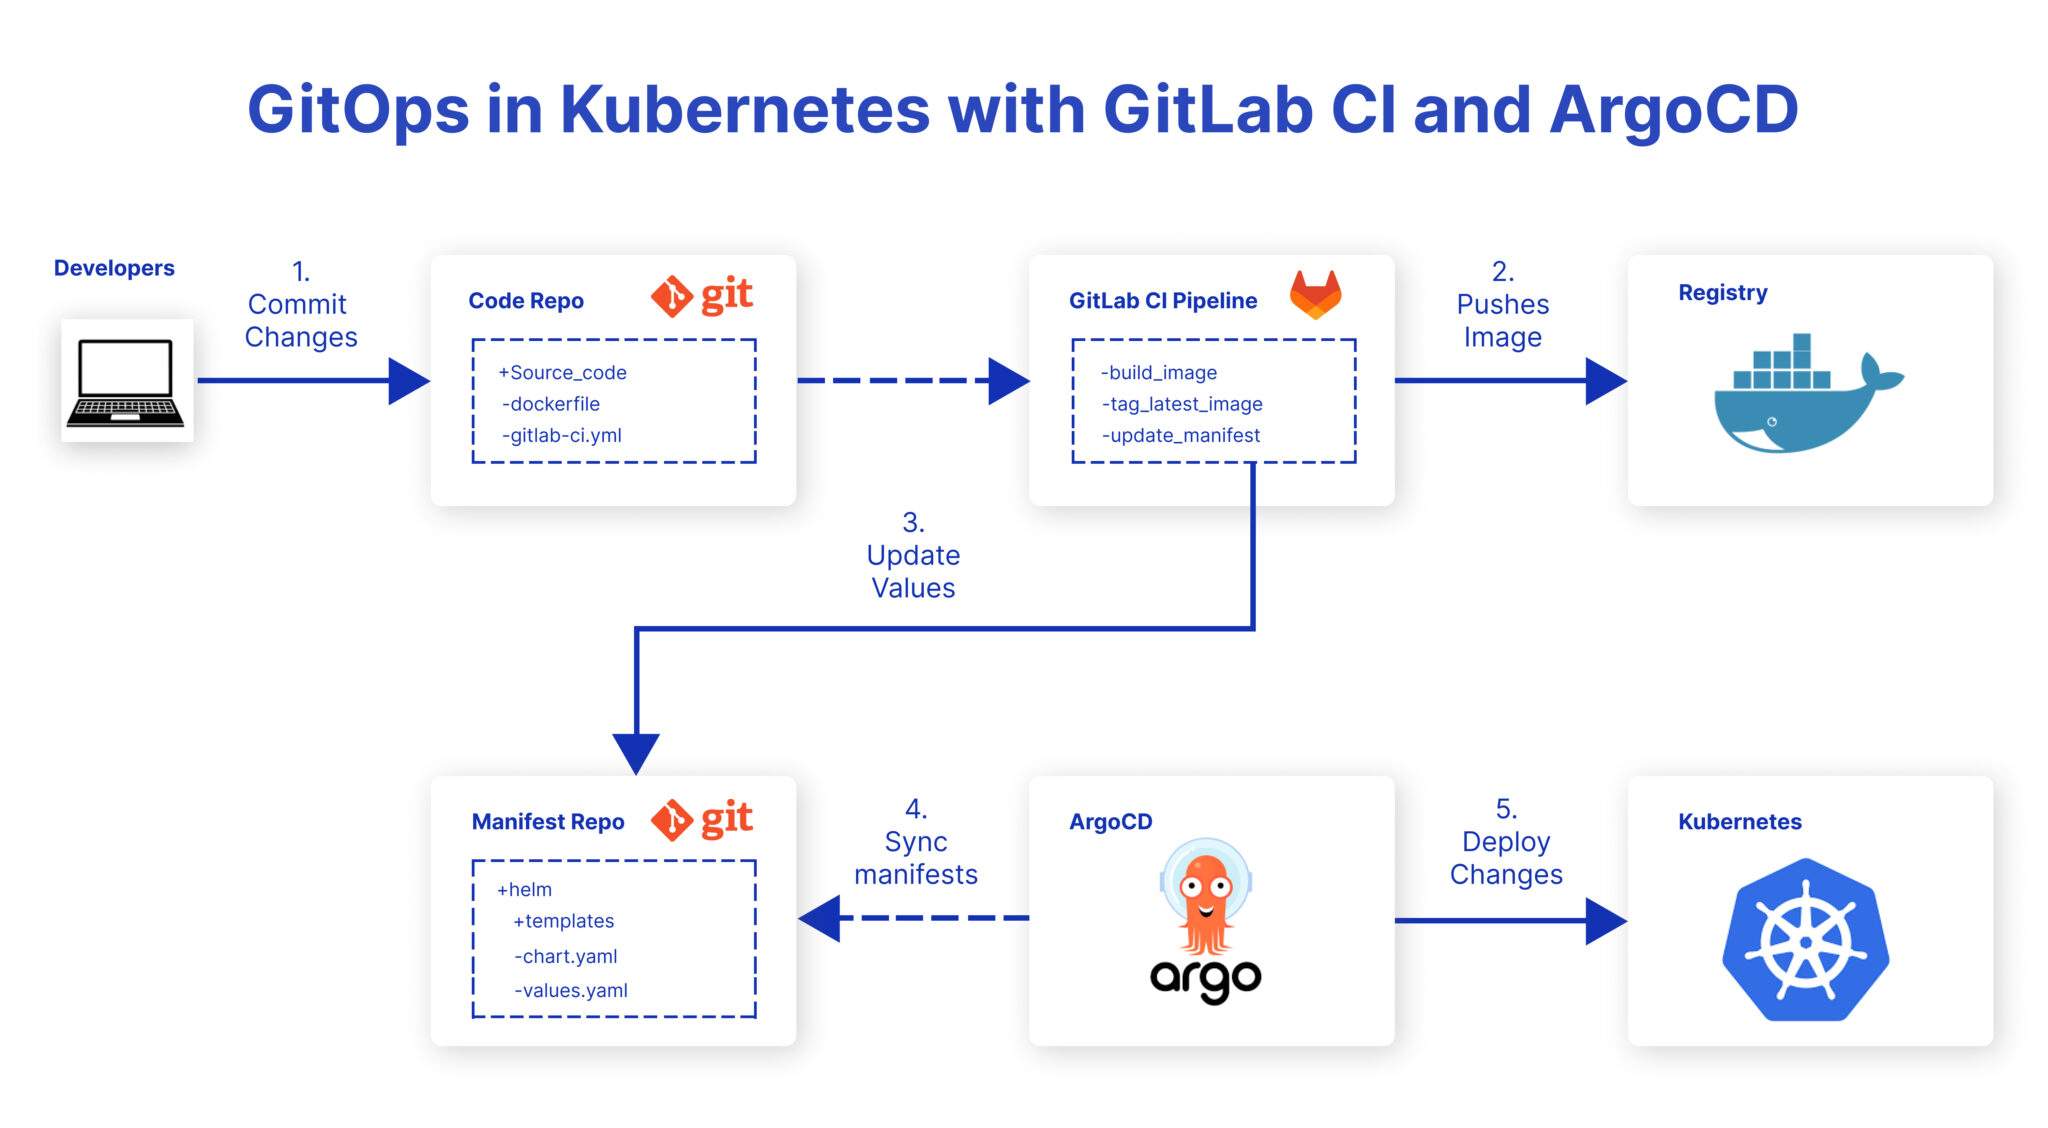
The most common question I see in CMUG discussions is how to connect GitLab CI/CD to external systems reliably. The answer depends on your infrastructure. For Kubernetes deployments, the bitnami/kubectl image works well for simple deployments. You need to store your kubeconfig as a CI/CD variable and decode it at runtime:
before_script:
  - echo "$KUBECONFIG_CONTENT" | base64 -d > ~/.kube/config
  - chmod 600 ~/.kube/config
For container registries, GitLab has a built-in Docker registry you can use if you are already in the GitLab ecosystem. The login step is automatic when using GitLab's own registry, which saves you from managing separate credentials. If you are deploying to AWS, Azure, or GCP, store the service account credentials as a masked variable and use the appropriate CLI tool in your pipeline image. Do not try to wrap everything into a single Docker image. It makes pipeline files unreadable and upgrades painful. GitLab releases a new version every month. Breaking changes are rare but they happen, and the official changelog does not always highlight the practical impact. That is why CMUG participation matters. The user groups post real-world migration experiences, runner configuration templates, and pipeline examples that you cannot get from the docs alone.
I join a few CMUG threads monthly to check if anyone has reported issues with recent versions. A common thread I notice is around runner scaling. When your team grows, your pipeline queue grows with it. The official autoscaling documentation covers the theory, but the actual configuration for your specific cloud provider often requires reading what other people have tried.
A Note on What This Approach Cannot Do
GitLab CI/CD is not a universal solution. If your organization requires air-gapped deployments, on-premises only infrastructure with no internet access, or complex multi-cloud rollouts with cross-region dependencies, you will hit limitations. The platform assumes a certain level of connectivity between GitLab, your runners, and your deployment targets. When that assumption breaks, you need custom runner configuration or a hybrid approach combining GitLab with tools like Argo CD for the deployment layer. For smaller teams with standard cloud deployments, the out-of-the-box experience is adequate. For larger or more constrained environments, expect to spend significant time tuning. That is just the nature of CI/CD platforms in 2026.
Where to Get Help
The GitLab community forums are the most active resource. CMUG threads there tend to have higher signal than general Q&A because the participants are usually people running GitLab CI/CD in production. Search before posting. Your issue has probably been discussed before, and someone has a working pipeline snippet that solves it. If you want to start contributing, set up a personal GitLab instance, create a test project, and break things on purpose. That is the fastest way to understand how the pipeline executor actually works under the hood.