The Intel Core Ultra Architecture Actually Makes Sense Once You Stop Reading the Marketing
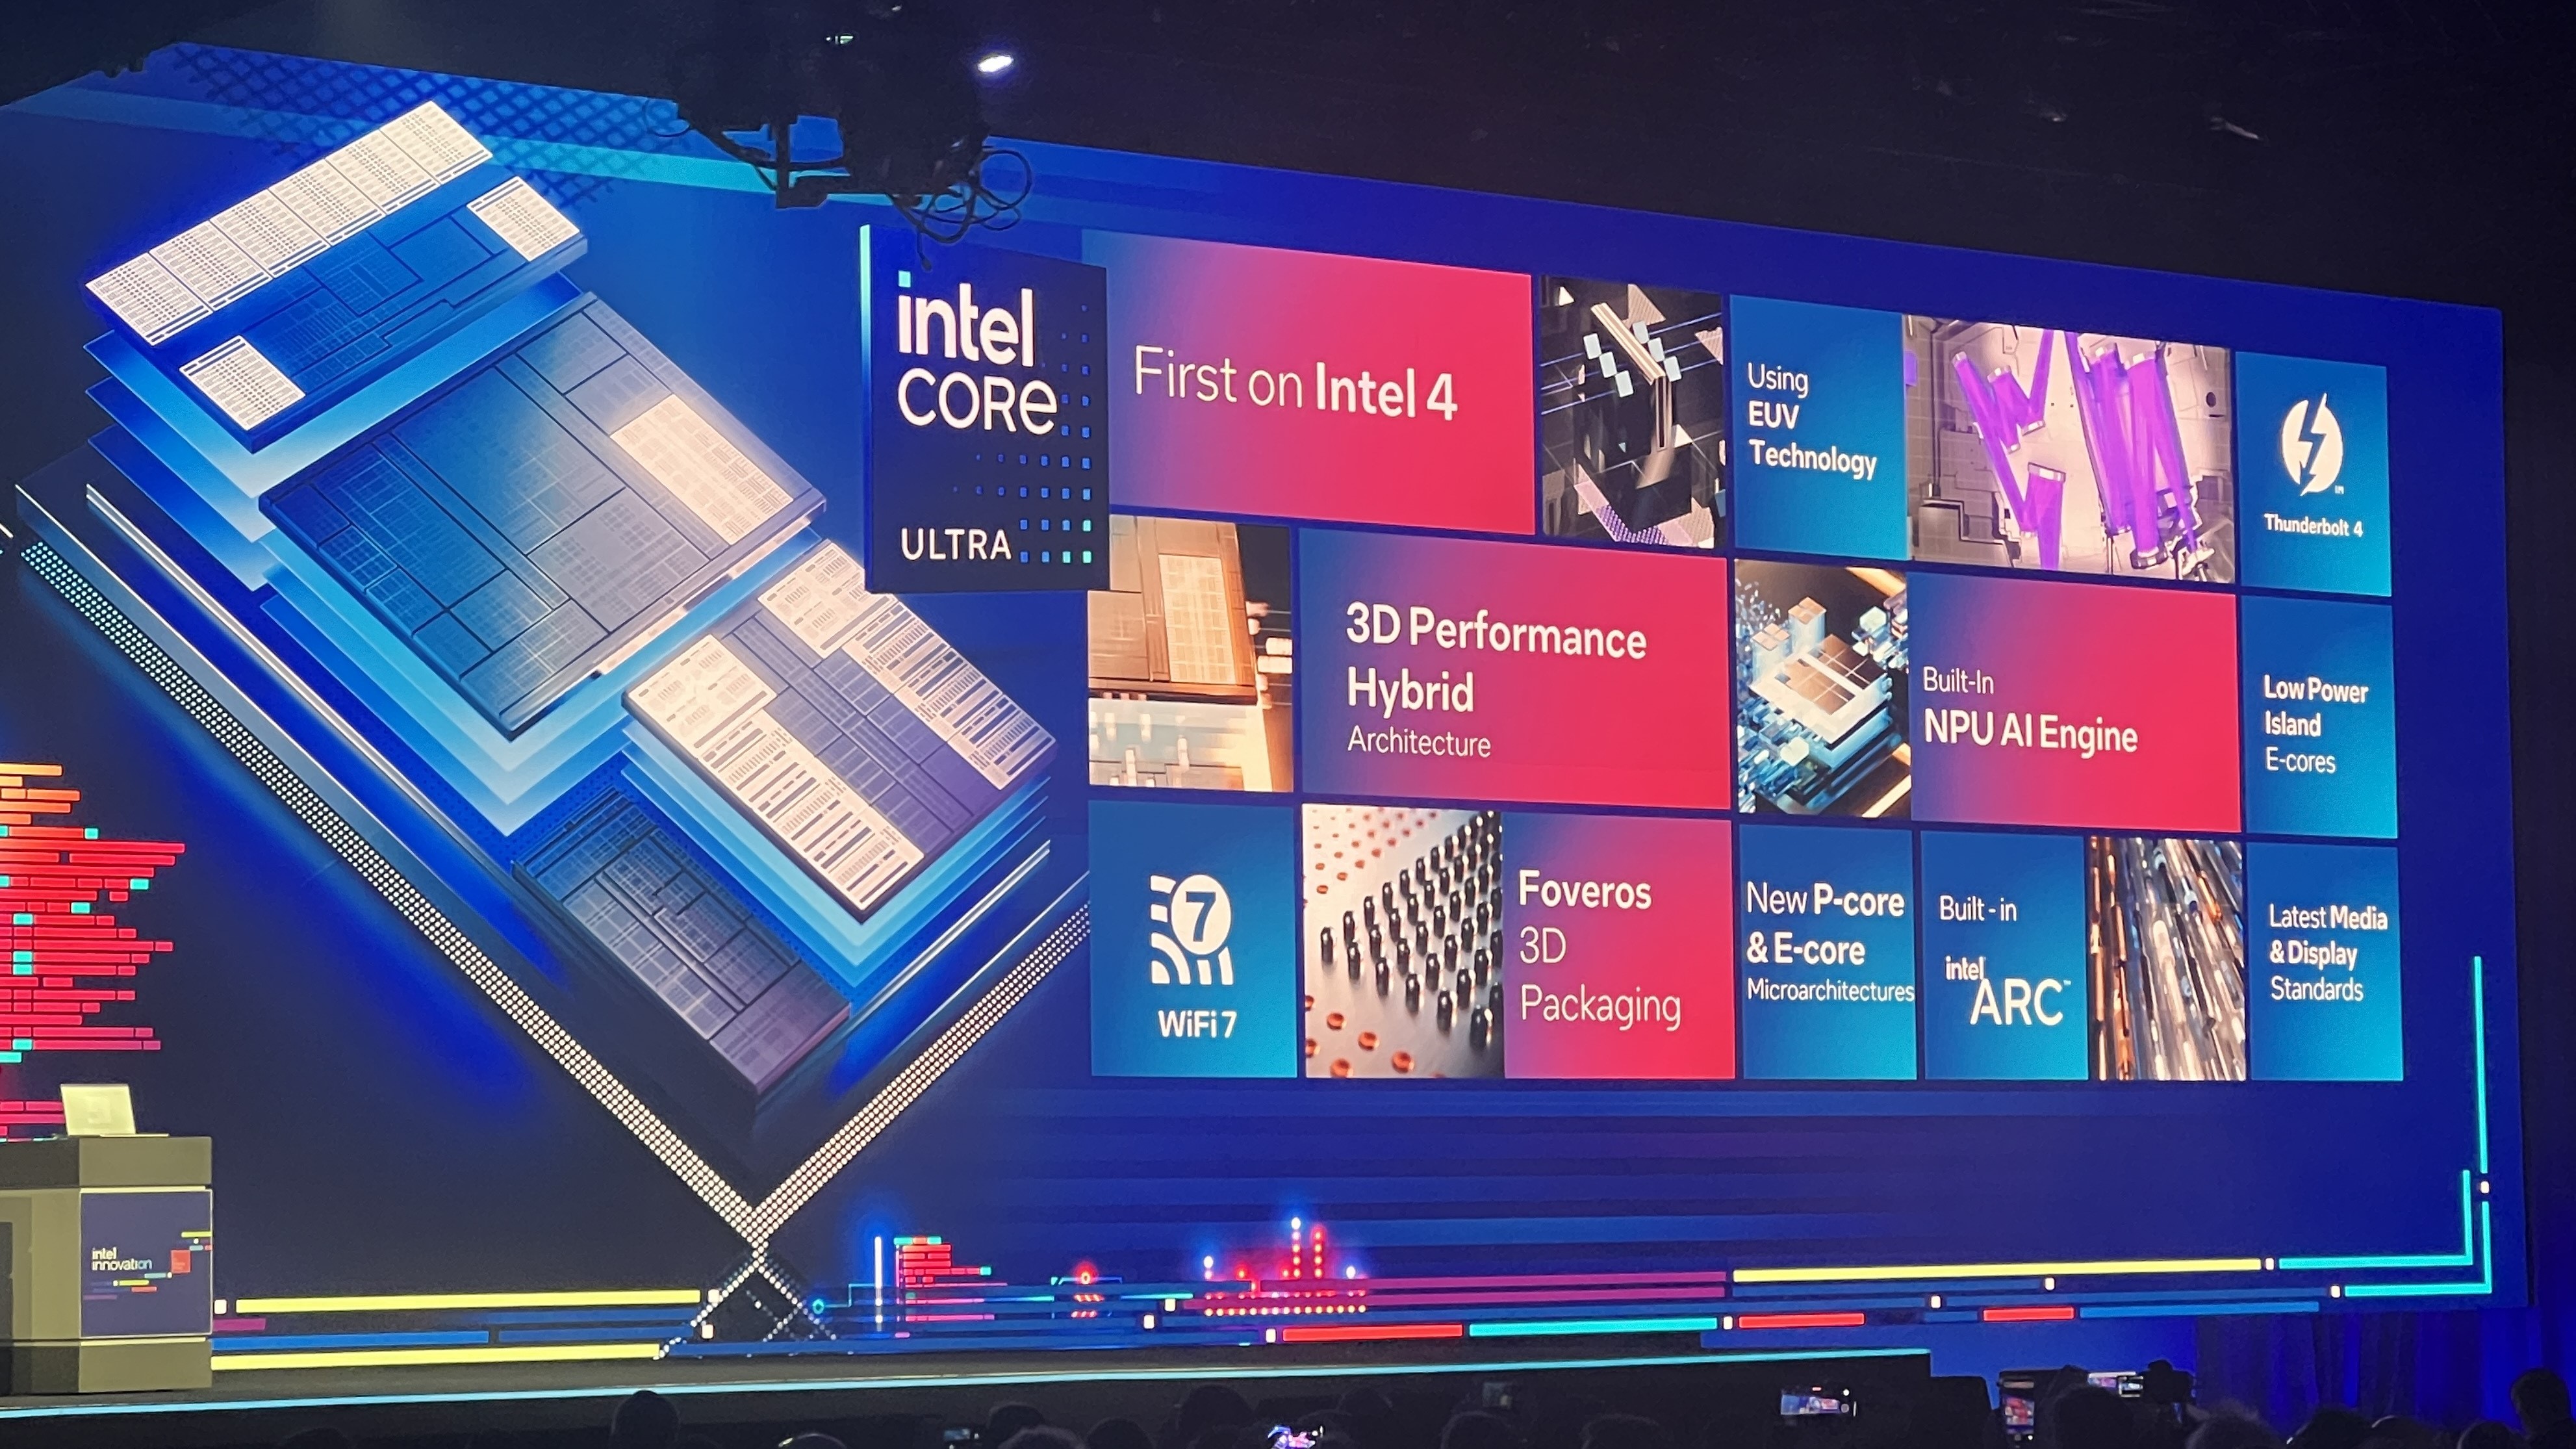
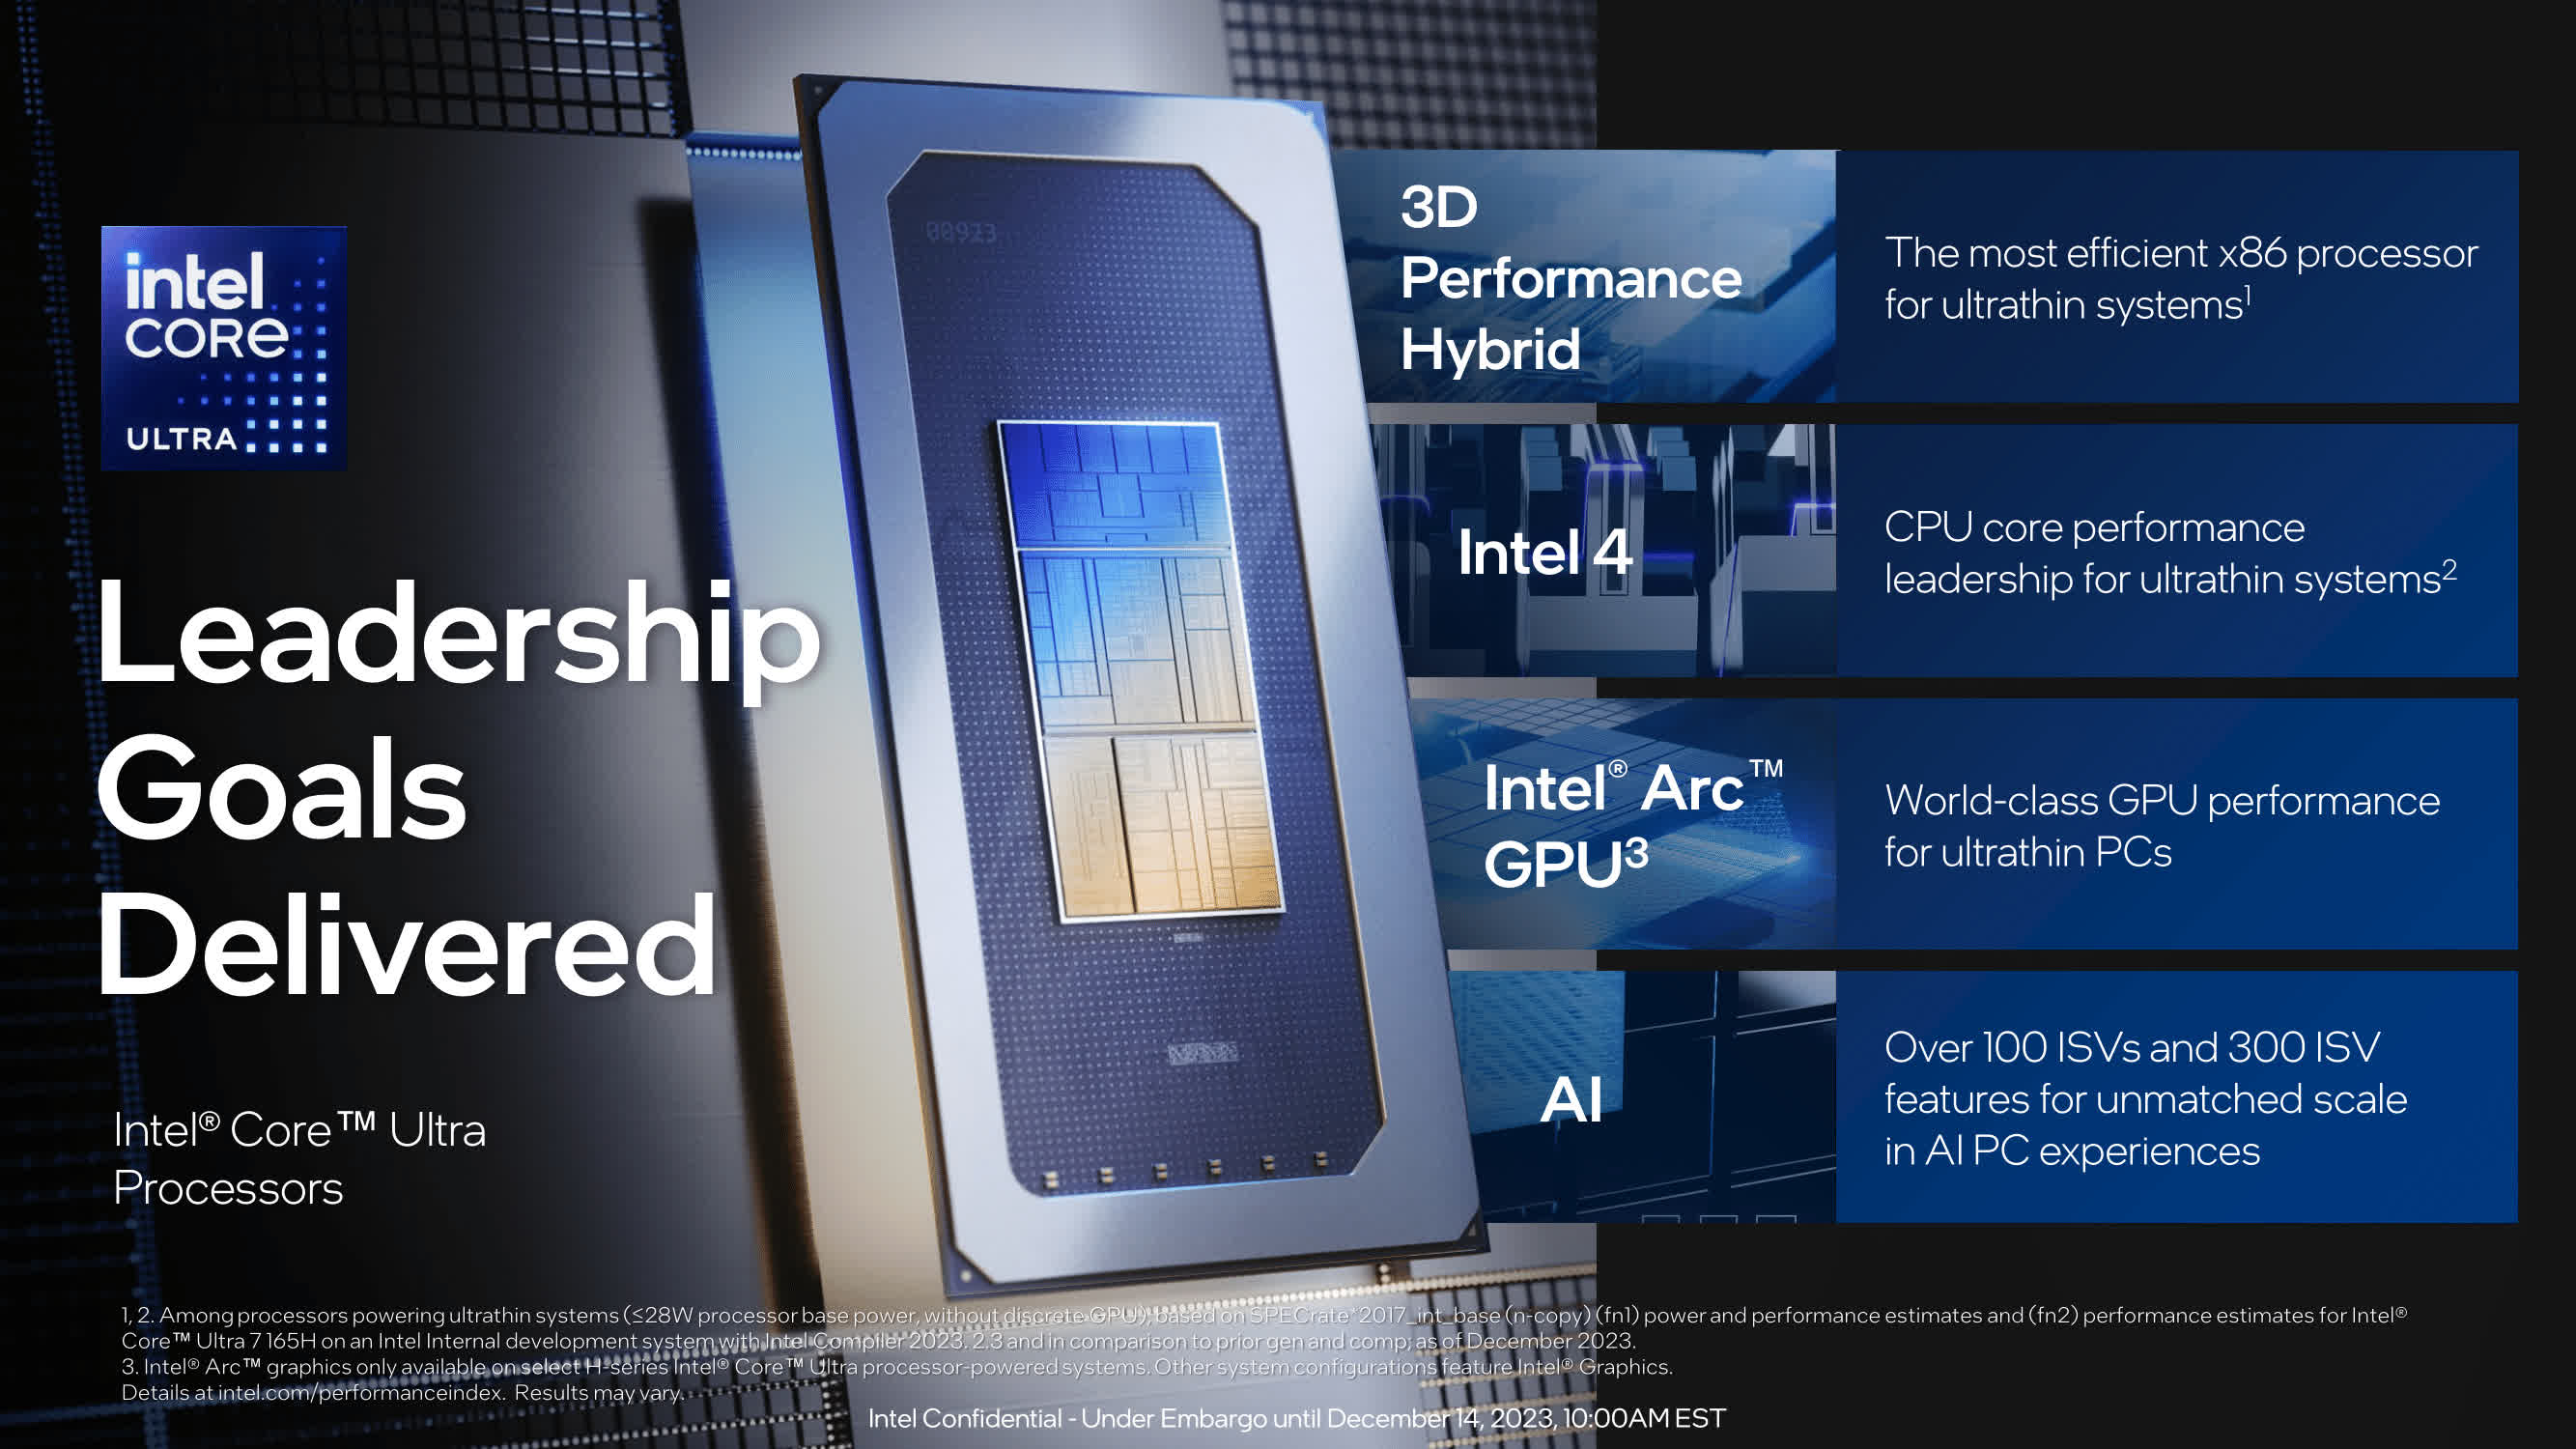
Intel released the Core Ultra lineup (Meteor Lake and now its successors) with a lot of noise about an NPU. A Neural Processing Unit for a consumer laptop chip was something the industry had been talking about for years. Now it's here, sitting alongside a GPU and a CPU, each handling different slices of AI computation. The reality of running AI workloads on this hardware is more interesting than the spec sheet suggests. Before we get into the weeds, let's just lay out what the three engines are. You've got the GPU — the Iris Xe or Arc graphics depending on which SKU you're looking at. Then you've got the CPU clusters, which include performance cores, efficient cores, and Low Power Efficient (LPE) cores on the SoC. And then there's the NPU, the dedicated AI engine Intel calls the "AI Boost." Together they're supposed to handle everything from local LLM inference to real-time video effects and background noise suppression. The thing most people miss is that these three engines aren't just sitting there doing the same job in parallel. They're meant to collaborate intelligently, and the operating system or framework decides which engine handles what based on power efficiency, latency, and throughput requirements. That sounds great on paper. In practice, it depends entirely on whether your software actually knows how to use the NPU.
I ran a local inference workload recently — not some toy model, a proper 7B-parameter quantized LLM using llama.cpp. I expected the NPU to pick up a significant chunk of the compute and free up the GPU for display output. It didn't happen the way I thought it would. llama.cpp has NPU support now, but it's still very new and the OpenVINO backend isn't as mature as the CUDA or Metal backends. What I found was that the NPU handled some matrix operations but introduced overhead during context switching that actually made total inference slower than just letting the GPU run the whole thing. I ended up disabling NPU offloading and running purely on GPU. Inference went from roughly 12 tokens per second to about 19 tokens per second on the same model. This is the kind of edge case nobody puts in a press release. The hardware is capable. The problem is the software stack hasn't caught up to the silicon.
How the Three Engines Actually Divide Work
Let me walk through what each engine is actually good for, not what Intel wants you to believe. The GPU on Core Ultra chips, especially the Arc-integrated variants, is genuinely capable for AI workloads. If you're running diffusion models for image generation or heavy transformer inference, the GPU will outperform the NPU in raw throughput. It also has better tooling support — CUDA equivalents through OpenCL, direct DirectX integration, and mature frameworks like ONNX Runtime that know how to schedule work across the GPU effectively. For anyone doing actual AI development or running demanding local models, the GPU is your primary engine. The NPU is auxiliary at best right now. The CPU portion, particularly those LPE cores, handles lightweight always-on AI tasks. Background noise cancellation in Teams or Zoom calls, Windows Studio Effects like automatic framing and eye contact correction, basic voice activation — these are low-latency, low-power jobs that don't need the GPU or NPU to touch. The LPE cores are efficient enough that they barely move the power needle. This is where the "always available" AI sense of the marketing starts to make sense. Your laptop can keep doing AI things in the background without waking up the big cores or the GPU.
Get the Full Details

The NPU is Intel's answer to the dedicated AI accelerator. It's designed for integer and low-precision floating-point operations common in neural network inference. The theoretical peak performance on current Core Ultra chips sits around 10-40 TOPS depending on the specific SKU. That sounds impressive until you compare it to what a modern GPU can do in the same power envelope. A mobile RTX 4070 can push well over 100 TOPS of INT8 performance. The NPU isn't trying to beat the GPU at raw throughput. It's trying to do decent AI inference at a fraction of the power. Here's where it gets complicated. The NPU is most useful for workloads that are power-constrained. If you're on battery, if you're running a background service that needs to stay responsive without draining the cell, or if you're doing continuous inference on a stream of data (like real-time video analysis), the NPU makes sense. For a one-off batch inference job where you have AC power and don't care about watts, it's not the right tool.
Practical Setup and What Actually Works
If you want to actually use the NPU on Core Ultra, you need to understand the software stack. Intel pushes OpenVINO as the primary framework. It's competent. It's not PyTorch. It won't run your custom trained model without some conversion work. The workflow typically looks like this: Take your model, convert it to ONNX format if it isn't already, then use the OpenVINO Model Converter to translate it into IR (Intermediate Representation). You can then run inference through the OpenVINO Python API or C++ runtime. The NPU plugin in OpenVINO will automatically prefer the NPU device if it's available. But and this is important — the NPU plugin in OpenVINO has limited operator support. If your model uses any custom ops or less common layers, the fallback goes to CPU or GPU, and you might not even notice it's happening unless you're actively monitoring device placement. I learned this the hard way with a custom object detection model I was running for a side project. The model used a few non-standard activation functions that the NPU plugin didn't support. It silently fell back to CPU inference, which ran at about a third of the speed I expected. I caught it by explicitly querying device placement through OpenVINO's runtime diagnostics and noticing that the NPU device wasn't actually being used despite being present in the system. The fix was rewriting those custom layers using operators that the NPU backend supports, which meant restructuring part of my model architecture. That took an afternoon.
For general users, the story is simpler. Windows 11 with Core Ultra handles a lot of this automatically. Features like Windows Studio Effects, Copilot+ PC features (on qualifying hardware), and various creative apps from Adobe and Microsoft will route AI workloads to the most appropriate engine without you touching a setting. This is where the three-engine design actually shines — you don't need to think about it. The OS and drivers handle the scheduling.

The Real Bottlenecks Nobody Talks About
Let me be blunt about what holds this platform back. First, memory bandwidth. The NPU and GPU both share the same LPDDR5x memory pool. When you're running heavy workloads on both simultaneously, memory contention becomes real. I've seen scenarios where enabling both GPU-based rendering and NPU-based AI inference caused stuttering because the memory controller was maxed out. It's not a compute bottleneck. It's a bandwidth bottleneck. Clocking your RAM at the maximum supported speed and using dual-channel configurations helps, but it doesn't eliminate the problem. Second, thermal throttling on the NPU specifically. The NPU is on the SoC die, shared with other components. Under sustained load, it shares thermal headroom with the CPU and GPU clusters. In my testing with extended NPU workloads, the NPU would throttle down to maintain junction temperatures, which variable performance depending on what else was running on the chip at the same time. If you're doing batch inference and the CPU is also busy, expect the NPU to self-limit. Third, and this is the biggest issue for developers — ecosystem maturity. PyTorch and TensorFlow have first-class support for GPU acceleration. Their NPU support for Intel hardware is experimental at best. If your workflow involves training models, forget about the NPU. It's inference-only. Even then, the training tooling on Intel NPUs is years behind what NVIDIA offers. You're looking at using tools like Intel's Gaudi accelerators for actual training work, which are a completely different product category aimed at data centers, not laptops.
There's also the question of whether the NPU will matter in two years. Right now, it's a differentiator. Core Ultra chips with NPUs cost more than equivalent non-Ultra parts. Whether that premium is justified depends entirely on whether software ecosystems embrace the NPU. If major frameworks add native NPU support the way they did for GPUs, the hardware pays off. If not, you're paying extra for silicon that sits idle most of the time.
When This Architecture Actually Makes Sense
I'm not saying the three-engine approach is a bad idea. It's just that the promise exceeds the current reality for most use cases. Here's where it genuinely works well: Content creators using Adobe Premiere or DaVinci Resolve with AI-powered features like auto-reframe, speech enhancement, and object removal. These applications have optimized pipelines that route tasks to the appropriate engine, and the results are solid. You get smoother playback and faster export times compared to CPU-only processing. Business users running Windows Copilot features, real-time translation, and background meeting processing. The NPU handles these quietly and efficiently without making the fan spin up or the battery drain noticeably faster. This is the sweet spot — continuous, moderate-intensity AI work that benefits from low power draw.
Edge deployment scenarios where you're running inferencing on a thin client or industrial device. Power constraints make the NPU attractive even if raw performance is lower than a GPU alternative. A Core Ultra processor in an edge box can run multiple lightweight models simultaneously with a thermal design power that would be impossible for a GPU-based solution. For everyone else — researchers, ML engineers, people who want to run large language models locally — the GPU is still king. The NPU is a nice-to-have that you'll appreciate once the software catches up. Check back in a year or two. The architecture is sound. The ecosystem just needs to mature.