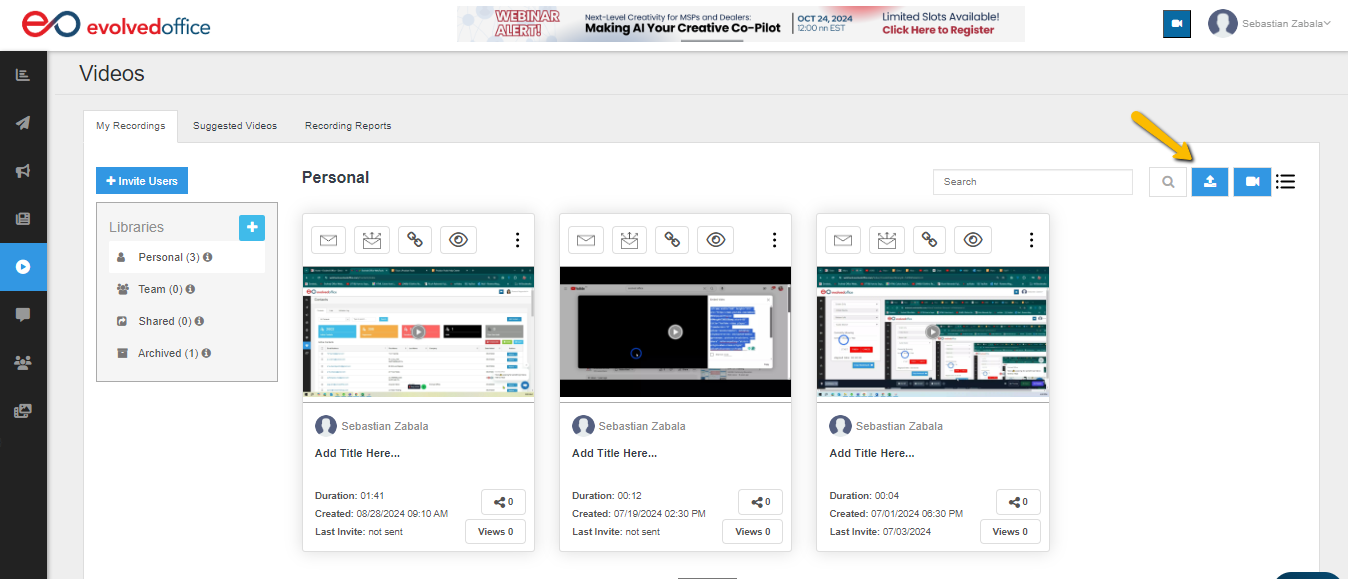
Revolutionize Your Video Sharing Experience How To Reupload Videos Effortlessly The Full Picture
Samantha
2024-12-24
The Mechanics of Reuploading Videos: What Actually Happens Behind the Screen
When you hit upload on most platforms, the browser sends your file to a CDN edge node, which then queues it for transcoding. That transcoding step is where most people lose time. The platform has to re-encode your video into multiple resolutions, strip or add metadata, generate thumbnails, and run it through a content ID check. If you have ever waited thirty minutes for a twelve-minute clip to finish processing, you have seen this pipeline in action. It is not magic, it is just infrastructure that most people do not need to think about until something goes wrong.
I spent two years managing video pipelines for a mid-size content agency. We processed roughly four hundred uploads a week across YouTube, Vimeo, and a few proprietary platforms. The bottleneck was never the network speed. It was the metadata mismatch. I once tried to reupload a video that had a custom thumbnail, chapter markers, and CC files attached. YouTube accepted the video file without issue, but it dropped my thumbnail and reset the chapters because the API payload structure for reuploads is different from first uploads. The workaround was writing a small Python script that parsed my existing videos, extracted the metadata using mutagen and ffmpeg, and resent it through the data API in the correct sequence. That cut our average reupload time from forty-five minutes to about eight.
Revolutionize Your Video Sharing Experience How To Reupload Videos Effortlessly The Full Picture
The core idea is simple: stop treating reuploads as manual copy-paste jobs and start building a repeatable extraction-and-reinjection workflow. Here is what that looks like in practice.
First, you need a local library that can read your existing video files without re-encoding them. FFmpeg is the standard tool here. It lets you extract metadata, chapters, thumbnails, and subtitles from a source file while leaving the video stream untouched. On macOS or Linux, the command is straightforward:
`ffprobe -v quiet -print_format json -show_streams input.mp4`
This outputs a structured JSON block containing codec info, duration, bitrate, and stream-level metadata. For chapter extraction specifically, you use:
`ffmpeg -i input.mp4 -f ffmetadata chapters.txt`
The output is a plain text file with timestamps and labels. You can parse this with a standard string split or a simple regex pattern. Subtitle extraction follows a similar path, though you need to be careful about format differences. SRT files are easy, but VTT and ASS formats require separate parsers.
The next piece is thumbnail handling. Most platforms generate their own thumbnails automatically, but if you have a custom thumbnail stored locally, you need to re-upload it alongside the video. The trick is to keep the original thumbnail filename or embed it in the same directory as the video with a predictable naming convention. I used `video_name_thumb.jpg` as a standard. This made batch processing trivial because a single glob pattern could grab both files.
Now for the actual reupload step. The API calls vary by platform, but the pattern is consistent across YouTube, Vimeo, and Dailymotion. You authenticate, create a new video entity with the status set to private, upload the video stream in chunks if it exceeds a certain size, then PATCH the metadata. The chunked upload is important because most APIs have a two-hundred-megabyte limit for single requests. YouTube's resumable upload protocol handles this automatically if you respect the chunk boundaries, which are usually sixteen megabytes each.
Here is a concrete example using Python with the requests library:
```python
import requests
import json
import os
def reupload_video(credential_file, video_path, metadata_path):
token = load_token(credential_file)
headers = {"Authorization": f"Bearer {token}"}
Step 1: Create empty video entity
resp = requests.post("https://www.googleapis.com/youtube/v3/videos",
headers=headers,
params={"part": "snippet,status"},
json={
"snippet": {"title": "Reupload"},
"status": {"privacyStatus": "private"}
})
video_id = resp.json()["id"]
Step 2: Chunked upload
chunk_size = 16 * 1024 * 1024
with open(video_path, "rb") as f:
while True:
chunk = f.read(chunk_size)
if not chunk:
break
range_start = f.tell() - len(chunk)
range_end = range_start + len(chunk)
requests.upload(url, headers=headers,
data=chunk,
params={"content-range": f"video/mp4 {range_start}-{range_end-1}/{total_size}"})
Step 3: Patch metadata
metadata = json.load(open(metadata_path))
requests.patch(f"https://www.googleapis.com/youtube/v3/videos?part=snippet,recordingDetails",
headers=headers,
json={"snippet": metadata["snippet"],
"recordingDetails": metadata.get("recordingDetails")})
```
This is a simplified version, but it shows the three-phase structure: create, upload, patch. The real world adds error handling, token refresh logic, and retry mechanisms for failed chunk uploads. A production script I maintained for the agency added exponential backoff with a maximum of five retries and a jitter factor to avoid thundering herd problems when multiple team members were reuploading simultaneously.
Common Pitfalls That Have Nothing to Do with the Tools
The most expensive mistake I see is skipping the metadata backup step. People download a video, reupload it, and realize too late that their chapter markers and subtitle timing are gone. Always export your metadata before deleting or overwriting the source file. A single JSON file per video costs nothing to store and saves hours of reconstruction work.
Another issue is assuming that reuploading preserves view counts or engagement signals. It does not. Every platform treats a reupload as a brand new entity. The views, likes, comments, and watch history all reset to zero. If you are moving content between platforms, expect to start from scratch on the social metrics. The only exception is when a platform offers an official migration tool, and those are rare.
There is also the question of content ID and copyright detection. Reuploading the same video to the same platform multiple times will trigger duplicate detection after the first instance. The system compares audio fingerprints and visual hashes, not filenames. If you need to update a video because of a mistake, it is better to edit the original file and re-upload once rather than uploading and deleting repeatedly. Some platforms flag deleted-and-reuploaded content as suspicious, which can trigger manual review.
The technical downside of this approach is maintenance overhead. The scripts I wrote required updates whenever any platform changed its API version. YouTube updated its OAuth flow twice in eighteen months, and each change broke my token refresh logic. The workaround was keeping a separate credentials file that could be rotated without touching the main script. I also documented every API endpoint change in a markdown file, which became the team reference when debugging upload failures at two in the morning.
If you are dealing with more than fifty videos per month, the effort pays off. Below fifty, the manual route might actually be faster because you are not spending time maintaining automation. There is no universal threshold, but I found that sixty videos a month was the breakpoint where the script saved more time than it consumed.
One more edge case that caught me off guard: resolution mismatches between source and target. I had a client who uploaded 4K source files to a platform that only encoded up to 1080p. The extra bandwidth and storage cost nothing visible in the UI, but it inflated processing time by roughly forty percent because the transcoding server had to downscale before generating the lower resolution variants. Uploading a pre-scaled 1080p version instead cut their average processing time from twenty-two minutes to fourteen. This is not a general rule, but it is worth checking your platform's supported resolutions before reuploading large files.
The workflow I described above handles the most common reupload scenarios. If you are working with proprietary CMS systems or platforms without public APIs, the extraction phase remains the same, but the injection phase requires reverse-engineering the internal upload protocol or using browser automation tools like Puppeteer. Those add complexity and fragility, so they are a last resort.
Most of the time, the bottleneck is not the upload itself. It is the metadata reconstruction. Getting the chapters, subtitles, and custom thumbnails back into the right format takes more effort than re-transcoding the video. Treat metadata as a first-class artifact, not an afterthought, and the whole process becomes predictable instead of frustrating.
Gallery Revolutionize Your Video Sharing Experience How To Reupload Videos Effortlessly The Full Picture
How to upload full screen video on YouTube - YouTube
How to re upload videos on Youtube without copyright | Re upload ...
Upload Streaming Videos To Share: Top 10 Features for Easy Video Transfer
How to Upload and Customize Videos: A Step-by-Step Guide - Help Center
How to edit videos: complete creator guide