What You Actually Need To Know About Reverse Proxies
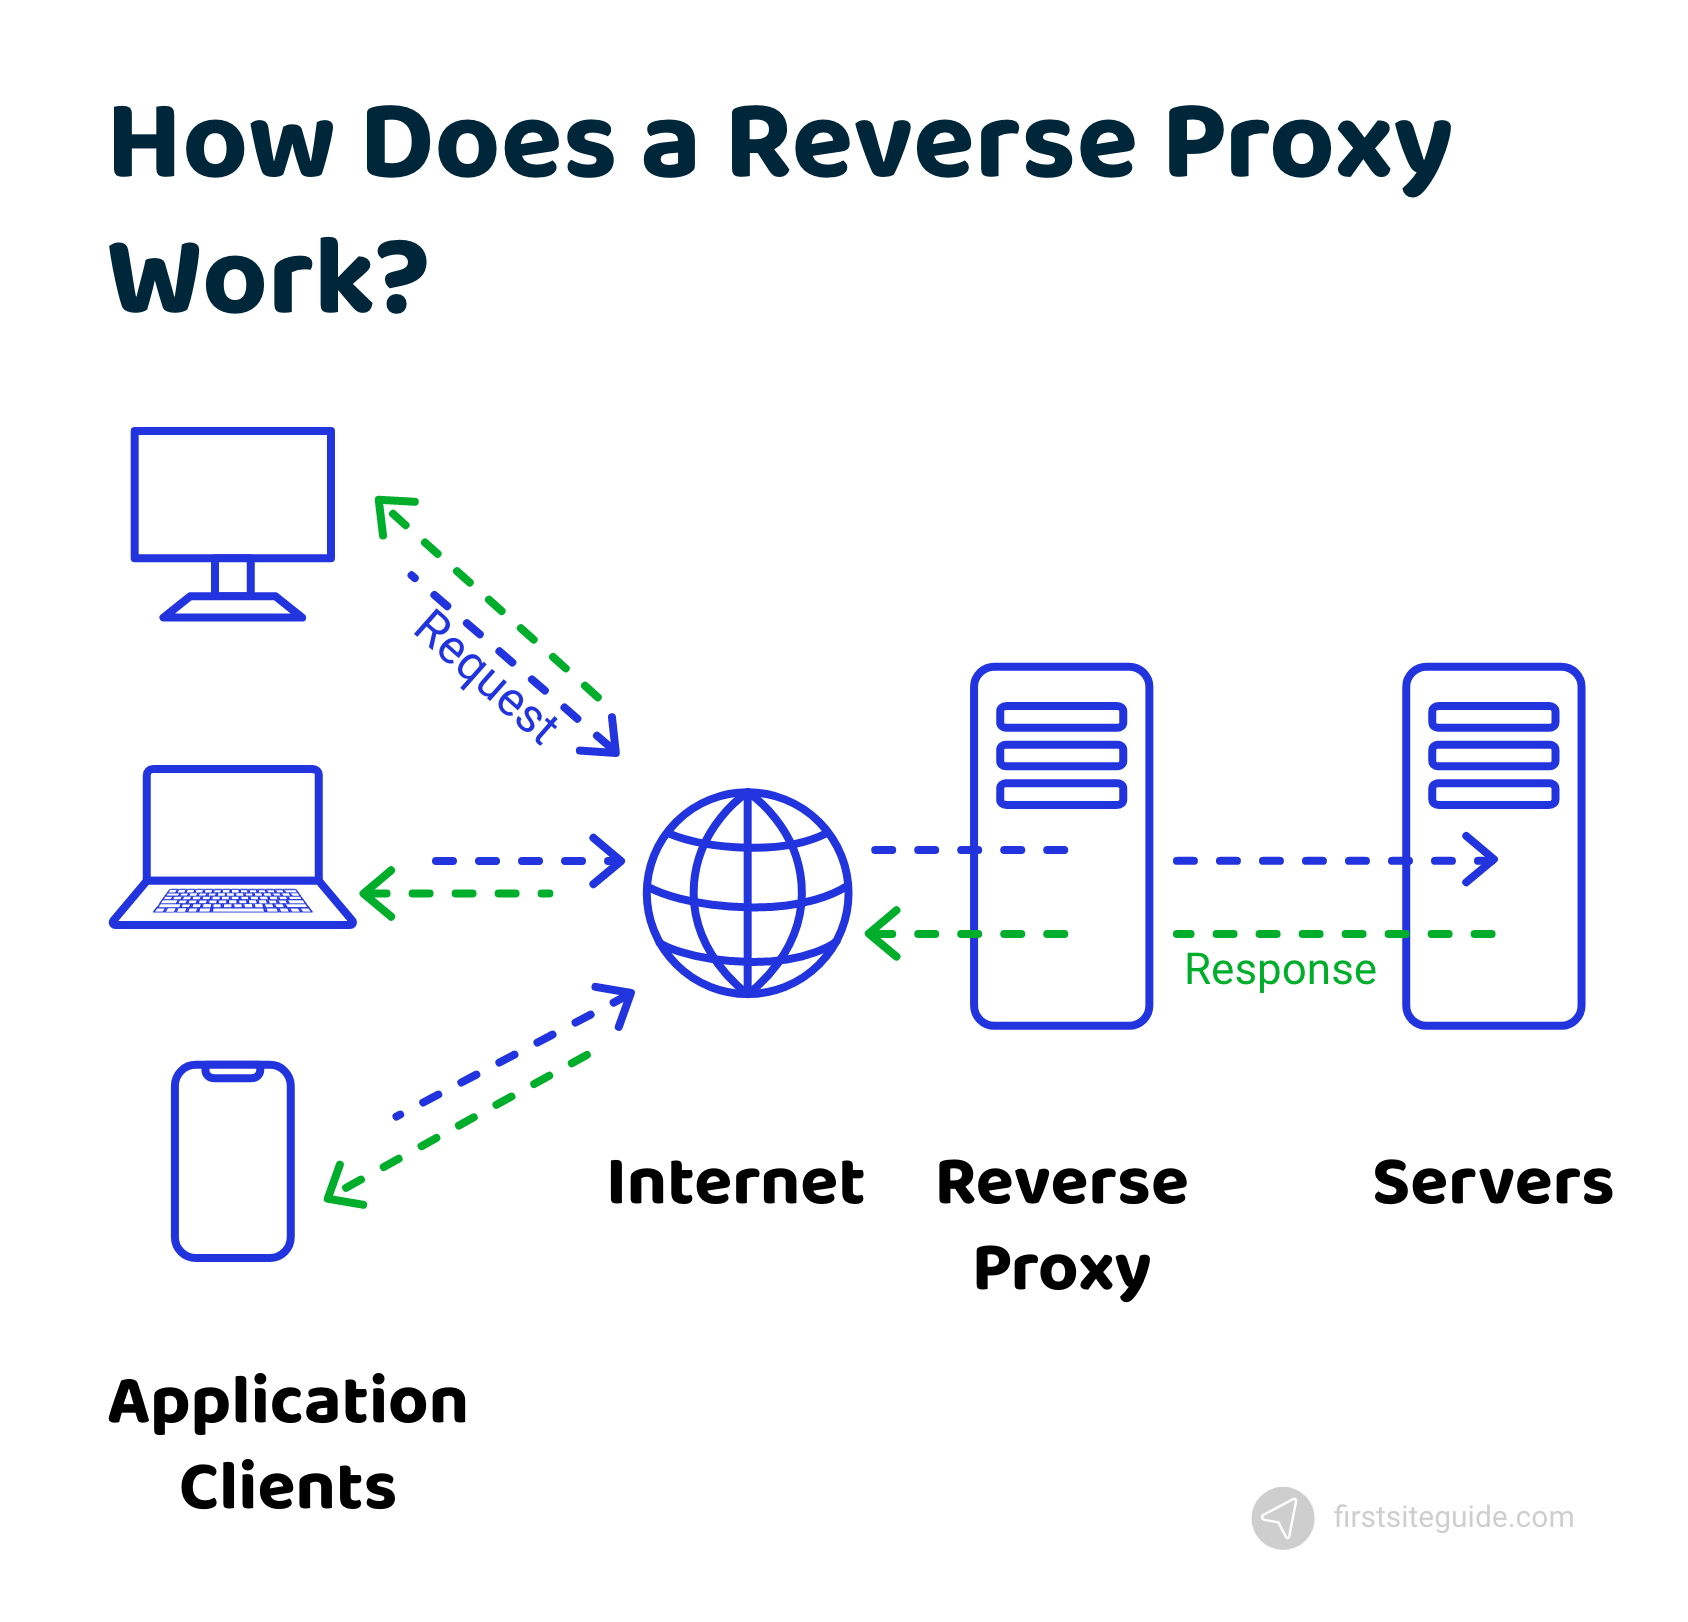
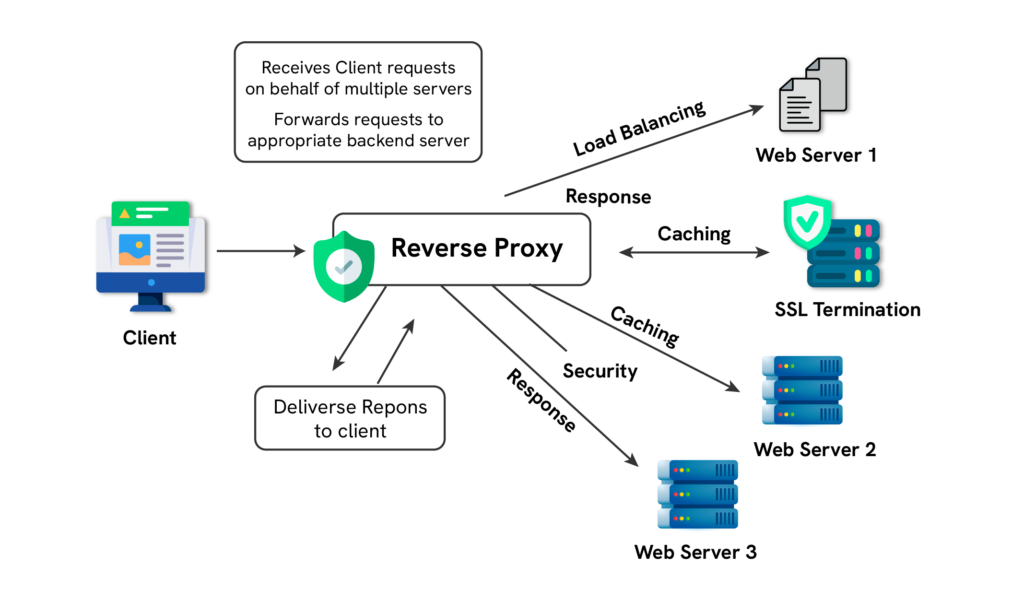
A reverse proxy sits between clients and your servers, forwarding requests and returning responses. That's the simple version. The real version involves termination points, header manipulation, load distribution, and a lot of edge cases that will burn you if you aren't watching. When a client sends a request to a reverse proxy, the proxy receives it, evaluates routing rules, and forwards the request to an upstream server. The upstream server processes it and sends the response back to the proxy, which then relays it to the client. The client never knows the actual origin server exists. This separation is why reverse proxies are used for SSL termination, caching, load balancing, and access control. I used to think this was straightforward. Then I spent three weeks debugging a production issue where clients behind certain carriers were getting 502 errors intermittently on WebSocket connections. The root cause wasn't the proxy configuration at all. It was that the carrier was dropping idle connections after 30 seconds, and our proxy's default keepalive timeout was set to 60 seconds. By the time the proxy tried to reuse a connection to the upstream server, the carrier had already torn down the client side. I solved it by setting proxy_http_version to 1.1 and configuring keepalive_timeout to 25 seconds on both the client-facing and upstream-facing connection pools. The errors stopped immediately.
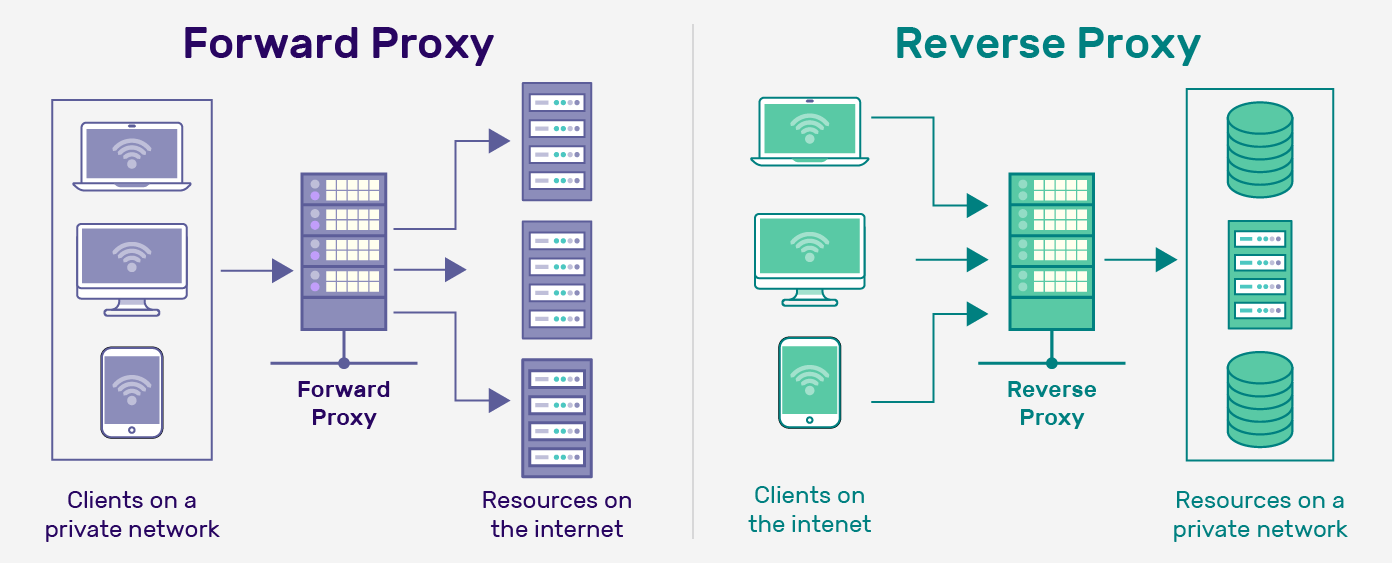
Most people don't realize that a reverse proxy and a forward proxy serve opposite purposes. A forward proxy sits in front of clients and routes their traffic out to the internet. A reverse proxy sits in front of servers and routes incoming traffic to them. They can technically do the same job in different scenarios, but the use cases are completely different. Here's what actually matters in practice: the proxy needs to handle connection pooling efficiently. If you're running Nginx or HAProxy as your reverse proxy, the number of concurrent connections your upstream servers can handle becomes a bottleneck long before the proxy itself becomes one. I've seen setups where the proxy was holding thousands of idle connections open because proxy_read_timeout was set to 300 seconds and the upstream application didn't close connections properly. That tied up file descriptors across the entire server. SSL termination is probably the most common reason people deploy reverse proxies. The proxy decrypts incoming TLS traffic and forwards unencrypted requests to the backend. This offloads CPU-intensive encryption work from your application servers. But it also means the proxy becomes a single point of failure for TLS configuration. If the proxy's certificate expires or the configuration is wrong, everything goes down. Make sure you're monitoring certificate expiry dates. Several companies I know lost revenue during holiday seasons because they assumed automatic renewal was working when it wasn't.
Another thing people miss is how headers behave. When a reverse proxy forwards a request, the original client IP address gets replaced by the proxy's IP unless you configure X-Forwarded-For, X-Real-IP, or similar headers. Your application needs to read these headers to get the real client address. Some frameworks do this automatically if you tell them you're behind a proxy. Others don't, and your logging will show every request coming from the proxy's IP. I spent an afternoon tracing a security incident where the firewall logs showed all traffic originating from a single internal IP because someone hadn't updated the proxy header forwarding rules after a migration. Load balancing is the other major use case. Round-robin is the default algorithm in most proxy software and it works fine for homogeneous backends with similar response times. But if your servers have different specifications or handle different types of traffic, you need weighted routing or least-connections algorithms. I configured a setup once where two of four backend servers were getting twice the traffic because the proxy was balancing by connection count rather than by active request count. The older servers crashed under the imbalance while the newer ones sat half-idle. There are also performance characteristics you should consider. A reverse proxy adds latency. Every request has to traverse the proxy before reaching the backend and back again. For most web applications this is negligible, maybe a few milliseconds. For high-frequency trading systems or real-time gaming servers, that extra hop matters. In those cases you'd want to run the proxy on the same machine as the backend or use kernel-level load balancing instead.
Get the Full Details
Common Configuration Mistakes
Setting buffer sizes too large is one. Default buffer sizes in many proxy configurations are generous, sometimes several megabytes. If you're proxying large file downloads or media streams, this means the proxy buffers the entire response before sending anything to the client. That uses memory and increases perceived latency. Setting proxy_buffering to off or reducing buffer sizes to something reasonable like 4k to 16k usually fixes this without much downside. CORS misconfiguration is another. The proxy needs to pass through or modify Access-Control headers appropriately. If you're handling CORS at the proxy level rather than the application level, you need to make sure the proxy is forwarding the right headers and that your proxy configuration doesn't override them. I've seen proxies strip CORS headers because someone added a generic header cleanup rule without understanding what was being forwarded. Upstream timeouts are critical. If your proxy waits too long for a backend response, clients get timeout errors. If you wait too short, legitimate long-running requests fail. The sweet spot depends entirely on your application. A typical REST API might need 30 seconds. A report generation endpoint might need several minutes. Set proxy_connect_timeout, proxy_send_timeout, and proxy_read_timeout to match your actual requirements. Don't leave them at defaults.
There's also the matter of health checks. A reverse proxy should be verifying that upstream servers are actually responding before sending traffic to them. Passive health checks happen when failed requests are tracked. Active health checks involve the proxy periodically pinging the backend. Most production setups need active checks with configurable intervals and failure thresholds. Without them, the proxy keeps sending traffic to dead servers until clients start complaining. The choice of proxy software matters too. Nginx handles static file serving well but can struggle with very high concurrency on dynamic content without careful tuning. HAProxy excels at pure load balancing and connection management. Traefik integrates well with container orchestration but adds complexity. Caddy has automatic HTTPS but less granular control. Pick the tool that matches your actual traffic patterns, not the one that's trending on GitHub. Security-wise, the proxy becomes a target. It's exposed to the internet and handles all traffic. Rate limiting, DDoS mitigation, and WAF rules should be configured at the proxy layer. I recommend placing a CDN in front of everything if you're handling significant traffic. Cloudflare, for example, absorbs most attack traffic before it reaches your proxy. Without that layer, your proxy configuration becomes your only defense, and misconfigured firewalls on a single server won't stop a sustained volumetric attack.
Logging is essential but often inadequate. The default access log format only shows basic request information. For debugging, you need upstream response time, upstream status codes, and connection details. Add variables like $upstream_response_time, $upstream_addr, and $connection to your log format. This turns a generic access log into something actually useful when something breaks at 3 AM. Graceful reload is another practical consideration. When you update proxy configuration, you don't want to drop active connections. Proper configuration lets the proxy finish serving existing requests before restarting worker processes. Test this after every config change. I learned this the hard way when a deployment script sent a SIGHUP instead of the proper reload command and killed several hundred active connections during peak traffic hours. One counter-intuitive thing about reverse proxies: they don't necessarily make your application more secure by themselves. A misconfigured proxy can expose internal services that were never meant to be internet-facing. I found multiple internal admin interfaces accessible through a proxy that was supposed to only expose the public-facing application. The developer who set it up had used broad path matching rules without proper access restrictions. This happens more often than you'd think.
If you're running multiple services and need fine-grained control over routing, consider a service mesh instead of a traditional reverse proxy. Tools like Envoy with Istio or Linkerd handle service-to-service communication better than a single Nginx instance managing everything. The tradeoff is operational complexity. A service mesh requires monitoring infrastructure and understanding of distributed systems concepts that most small teams don't have. A well-configured reverse proxy handles 90% of use cases without that overhead. The other limitation to be aware of: reverse proxies add a dependency. If your proxy fails, your entire service goes down regardless of whether the upstream servers are healthy. This is why production setups always run multiple proxy instances behind a load balancer or anycast address. You shouldn't be running a single reverse proxy in production without redundancy. Period. Configuration drift is a real problem in larger environments. When you have ten different services each with their own proxy configuration files, keeping them consistent becomes a nightmare. I've seen setups where four different Nginx configurations were handling the same service with slightly different settings, leading to inconsistent behavior that was nearly impossible to debug. Use configuration management tools. Version control every config file. Automated testing of configs before deployment catches a lot of errors before they reach production.
Getting Started Practical Steps
Install Nginx, HAProxy, or your preferred proxy software. Configure a basic reverse proxy rule that forwards traffic from a domain to your backend server. Test it. Verify that headers are being passed correctly. Check that SSL termination works if you're using HTTPS. Monitor the logs for any unexpected behavior. Then add the production-grade settings: proper timeouts, health checks, logging enhancements, and rate limiting. Most tutorials skip straight to production settings without showing the working baseline first. For download links to the software I mentioned: Nginx is available at nginx.org, HAProxy at haproxy.org, Traefik at traefik.io, and Caddy at caddyserver.com. They're all free and open source. Commercial alternatives exist but aren't necessary for most deployments. Pay attention to your upstream servers' capacity. A reverse proxy can generate more load than your application expects, especially with keepalive connections and concurrent request handling. Monitor your backend resource usage after deploying a proxy. If CPU or memory jumps significantly, you may need to tune the proxy's concurrency settings or upgrade your backend infrastructure.
Document your proxy configuration. Not just the current setup but the decisions behind it. Why are timeouts set to specific values? What routing logic exists and why? This documentation becomes invaluable when the proxy breaks at 2 AM and you need to make changes under pressure without reintroducing problems you thought you'd solved. Finally, plan for failure modes. What happens when the proxy can't reach an upstream server? Does it return a custom error page? Does it try another backend? Does it queue the request? The default behavior in most proxy software is to return a 502 or 504 error, which is fine for development but terrible for production user experience. Configure appropriate fallback behavior, custom error pages, and retry logic for your critical services.