How I Recover a Deleted Video Using the Internet Archive
The Wayback Machine is not a video host. It is a snapshot tool. That distinction matters because people approach it expecting it to behave like YouTube with a history tab, and then they get frustrated when a 2018 vlog simply does not appear in the timeline. I spent about three weeks straight last year trying to recover a set of promotional videos from a defunct production company before I actually learned how the crawler works. The fundamental mechanism is simpler than most tutorials make it out to be. The Internet Archive's crawlers passively visit websites and take snapshots of the URLs they find. If your target video page was never visited by a bot, no snapshot exists. Period. There is no backdoor, no hidden request you can send to force a capture. The only reliable way to know whether something was archived is to query the public interface and see what dates come back.
Resurrecting Lost Videos How To Download Content From The Wayback Machine
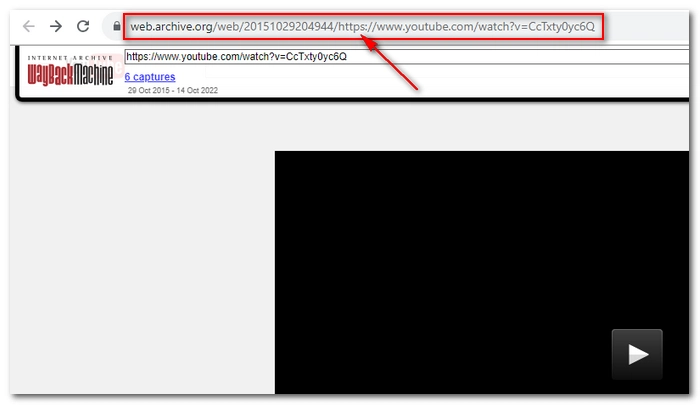
Start by going to web.archive.org and pasting the original URL into the search bar. You will see a calendar grid where dark circles represent captured dates. Lighter dates with faint circles mean the capture succeeded but the page content was mostly empty or failed to render properly. Solid dark dots with a thick border are your best candidates. Here is where beginners usually stall. They click a date and immediately try to right-click save, which rarely works for video content. Most videos on older sites were served through third-party embeds, legacy Flash players, or self-hosted HTML5 video tags with source URLs pointing to dead servers. The Wayback Machine intercepts those requests and rewrites them using its own rewrite proxy, which prefixes every asset with a timestamped path like web.archive.org/web/20180315142037/http://example.com/video.mp4. That rewritten URL is your download link. Open the snapshot, then inspect the page source. Look for <video> tags, <source src= attributes, or Flash embed parameters. When you find a video URL, prepend the Wayback Machine proxy prefix if it is not already there. The format is:
https://web.archive.org/web/2<YEAR>/<TIMESTAMP>id_/<ORIGINAL_URL> For example, if the original source was http://oldsite.com/media/intro.mp4 and the snapshot date is March 15, 2018 at 14:20:37 UTC, the proxied URL becomes: https://web.archive.org/web/20180315142037id_/http://oldsite.com/media/intro.mp4
Get the Full Details

Paste that into a browser or use a command-line tool like curl or wget to download it directly. I typically use this command because it handles the redirect chain cleanly: wget -O output.mp4 "https://web.archive.org/web/20180315142037id_/http://oldsite.com/media/intro.mp4" The id_ segment is critical. Without it, the proxy may attempt to serve the page as HTML rather than the raw media file, and the download will either fail or save garbage. The id_ suffix tells the Wayback Machine to treat the request as an identity mapping, which preserves the original content type header and bypasses the HTML rewriting layer entirely.
My biggest headache came from a specific edge case that took me about four hours to work around. The video I needed was hosted on a platform that used signed URLs with short expiration windows. Even though the Wayback Machine had a perfect snapshot of the page, every time I tried to download the actual video file through the proxy, the signed URL had expired and returned a 403. The workaround was to use the snapshot date as a reference point, find the exact signed URL from the page source, and then manually reconstruct it. Some video platforms regenerate tokens per session but store the base path statically. I found the static base in the archived JavaScript, extracted it, and combined it with the current timestamp-based token using a small Python script I wrote. The resulting URL played fine in VLC even though it no longer worked on the original page. Another thing nobody mentions: the Wayback Machine does not crawl every subdirectory. If a video was embedded inside a dynamic route like /series/episode-7 but the crawler only hit the main series landing page, you will see a snapshot of the index but nothing for the episode itself. In those cases you can try the Save Page Now feature on a different machine, wait a few minutes, and then check if a new snapshot appears. This is hit or miss because the crawler has to physically visit the URL during its next pass, which can take weeks depending on the domain's crawl budget. There are also tools that automate the whole process. The wayback-machine-downloader npm package and the wget --mirror flag both support recursive archiving, but recursive downloads of video-heavy pages are extremely inefficient. I have seen a single 45-minute documentary page trigger over two thousand asset requests when the crawler tried to archive everything the video player loaded. Most of those requests were analytics pixels, ad trackers, and CDN fallbacks. The actual video file was usually one of the last requests to succeed.
For a more targeted approach, I use a combination of the Wayback CDX API and a custom script. The CDX API lets you query all captured URLs for a given domain in JSON format. Here is the query I run: https://web.archive.org/cdx/search/cdx?url=oldsite.com/*&output=json&limit=1000&fl=timestamp,original This returns a list of every archived URL along with its capture timestamp. I filter the results for .mp4, .webm, and .mov extensions, then cross-reference those timestamps against the page-level snapshots to confirm the video was actually accessible at that date. The script then generates the correct proxy URLs with the id_ modifier and downloads them in parallel using aria2c, which handles concurrent downloads much better than wget alone.

The whole process for a single video usually takes between 10 and 20 minutes if the snapshot is clean. If the video was behind authentication or used a streaming protocol like HLS or DASH, you are looking at 30 to 90 minutes of additional work. HLS streams consist of a master playlist and dozens of segment files. The Wayback Machine sometimes captures the playlist but misses the individual .ts segments because they live on a completely different CDN domain that was never crawled. I have recovered some of these by combining snapshots from multiple domains and stitching the segments together manually, but it is tedious and error-prone. Let me be clear about what this cannot do. If the original content was never crawled, no amount of scripting will create a snapshot that does not exist. If the video was hosted on a platform that actively blocks archive bots, you may find a page-level snapshot but the embedded player will load nothing because the video source URLs are rewritten to point at domains the Wayback Machine cannot resolve. If the content was removed by the copyright holder through a takedown request, the Internet Archive may have purged the snapshot entirely, and it is gone from their systems permanently. The most common failure mode I see is people attempting to download entire channels or playlists expecting batch success rates above 60 percent. In practice, a well-maintained channel with regular crawl activity might yield 30 to 40 percent recovery. A neglected site with sporadic captures drops to under 10 percent. The variance depends almost entirely on how frequently the domain was visited by the crawler over the years, which is not something you can control or predict accurately.
For the actual software you need, the Internet Archive provides no official desktop application. Everything runs through the web interface and the public APIs. The most reliable command-line tool remains wget with the --restrict-file-names=nocontrol flag to handle oddly named video files, or curl with -L to follow redirects through the proxy layer. For bulk operations, the Wayback Machine CDX API is the only programmatic interface worth using, and it has a rate limit of roughly one request per second per IP address before you start seeing 429 responses. I keep a simple reference document for this now instead of trying to remember the proxy URL format each time. The format is consistent but the id_ versus ff_ modifier distinction is not obvious from any documentation I have read. id_ preserves the original response headers and content type. ff_ forces a Flash-friendly rewrite that sometimes helps with legacy .swf players but corrupts modern .mp4 files. If you are dealing with pre-2015 video content, try ff_ as a fallback after id_ fails. The tool itself is free. The knowledge of how it actually works under the hood is what separates people who get a handful of usable files from people who waste two days clicking dates and wondering why their downloads are all zero bytes.