Most Backlogs Are Just Graveyards
I have been doing product work for long enough that I can look at a Jira board and tell within thirty seconds whether a team actually knows what they are doing or whether they are just collecting tickets until the server room catches fire. The problem is not that people do not understand backlog refinement. The problem is that almost nobody treats it as the operational discipline it needs to be. You have heard the word before, but the real work is what happens after the ceremony where everyone sits around and says they are "aligned." Here is the thing nobody tells you during onboarding: refinement is not a meeting. It is a continuous state of decay prevention. Features rot. Requirements age poorly. The business context shifts, and suddenly the ticket sitting at the top of your queue is the most expensive mistake in the system because someone assumed it was still relevant. I once spent three weeks preparing to build a reporting dashboard that had been at the top of a team's backlog for fourteen months. We tore into it, started writing specs, and then realized the original stakeholder had left the company eight months earlier and the person who replaced them had no memory of why it existed. That ticket cost us about twelve engineering hours in setup alone before we killed it. Good refinement would have caught that in a five minute review. Start by establishing a hard capacity rule for refinement itself. If you do not allocate a specific portion of sprint capacity to grooming, it will never happen because the next hot feature will always win. I typically see teams set aside one to two hours per week, which is about six to ten percent of total capacity, depending on sprint length. Anything less than that and you are basically just checking boxes in a ritual that makes everyone feel productive without changing anything. The output should be a clearly labeled bucket of stories that are ready to pull into a sprint within the next one to two weeks. That is your "refined" tier. Everything below that is still raw material.
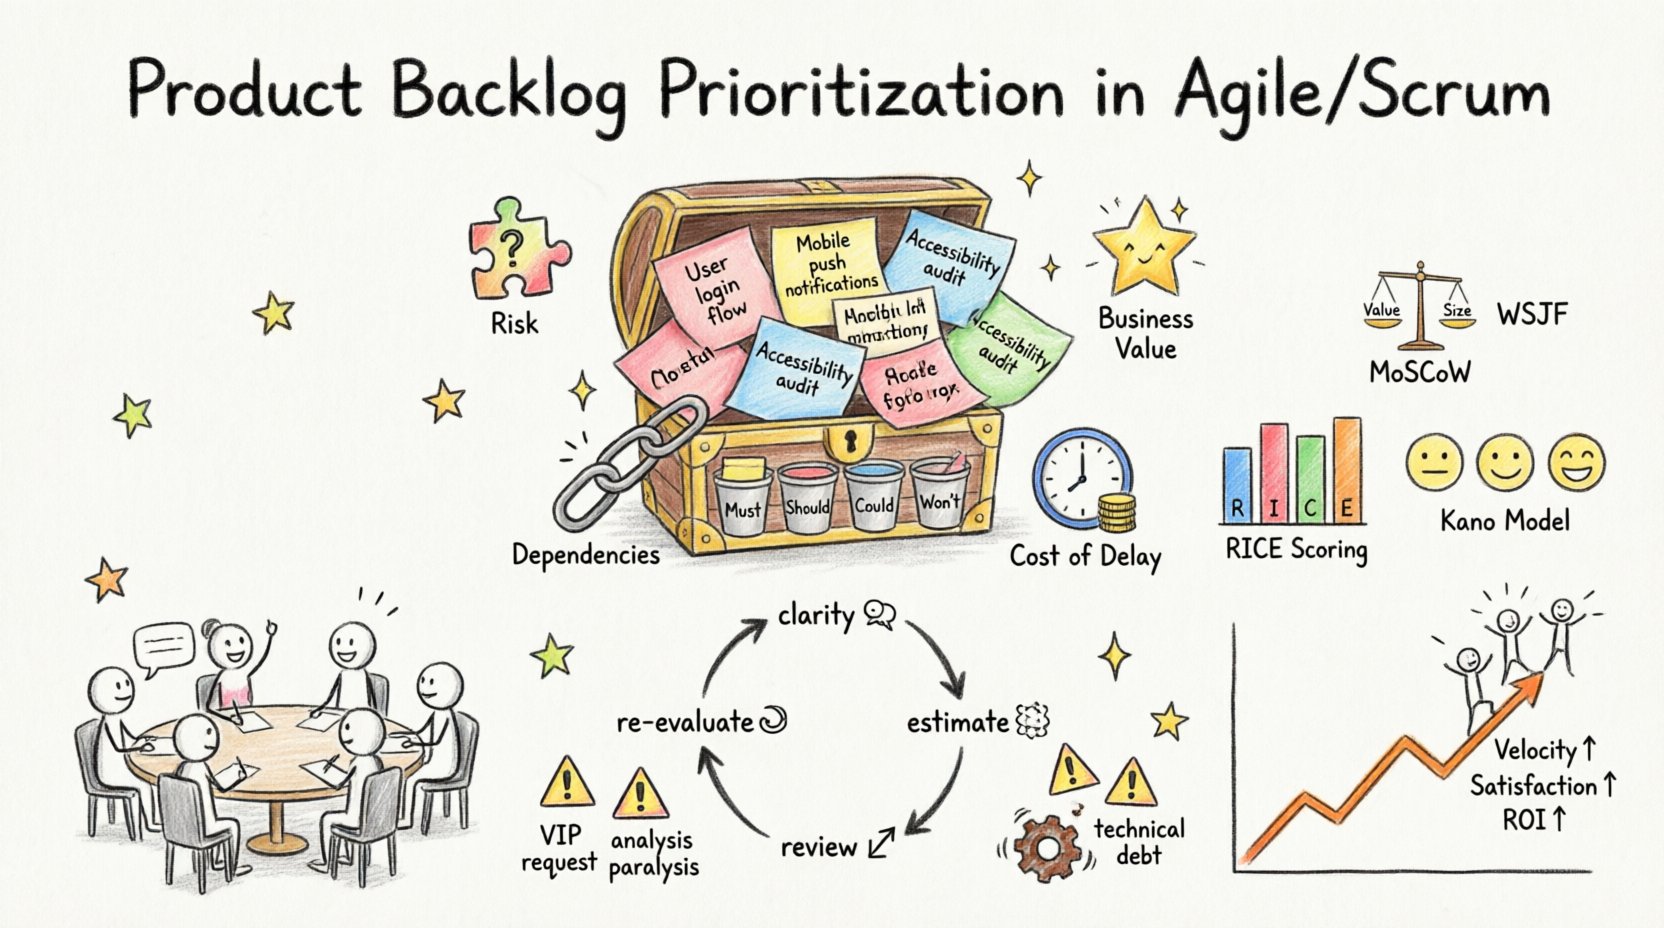
Within that refined bucket, you apply a prioritization framework. The most common mistake I see is teams picking a framework and using it blindly, usually RICE or MoSCoW, without understanding what each column actually measures. RICE sounds scientific, but the impact score is almost always a guess dressed up in math. I have seen impact values range from 2 to 200 on identical features depending on whoever was feeling confident that Tuesday. Use weighted scoring models if you want, but document the assumptions behind every score and treat them as hypotheses that need verification, not as facts. A simpler approach that tends to work better in practice is opportunity scoring combined with effort estimation. Score each item on a one to five scale for customer value, business value, and strategic alignment, then add those together and divide by a T-shirt sized effort estimate. The ratio gets you to a rank fast enough to be useful.
Pitfalls That Destroy Backlogs
The number one killer is scope creep disguised as dependency mapping. Someone will say, "we need to build X before Y," and suddenly your neat prioritized list turns into a twelve item chain where nothing can move until the first one lands. Dependencies are real, yes, but teams routinely inflate them by an order of magnitude. In one engagement I audited a backlog with forty three items flagged as dependencies, and roughly sixty percent of those were either assumptions or things that could be decoupled with a week of architectural discussion. Run a dependency audit monthly at minimum. Break chained items into smaller vertical slices. If a story cannot be delivered as an independent increment of value, it is not one story, it is a project, and projects do not belong in a product backlog. Another issue is what I call priority drift. This is when items slowly sink through the queue not because of a deliberate decision, but because every sprint someone adds a slightly more urgent item to the top. After six months your top twenty contains nothing older than a month and everything else is stale. The fix is simple and brutal: impose a maximum age on refined items. Anything older than roughly two sprints gets revalidated or retired. I enforce this with a hard rule where every refined ticket has an age field, and anything past the threshold requires explicit stakeholder sign off to remain in the refined bucket. This alone removed about thirty percent of dead weight from a backlog I was cleaning up last year without anyone even noticing they had been carrying dead weight.
Get the Full Details

What Good Refinement Actually Looks Like
A refined story should pass the INVEST criteria without someone having to explain what INVEST means in a meeting. Independent enough to stand alone, Negotiable in scope, Valuable to someone who will pay or care, Estimable by the team that builds it, Small enough to fit in a sprint, and Testable with clear acceptance criteria written before development starts. Most teams fail on the last two. Acceptance criteria are not an afterthought. They are the boundary of the commit. If you cannot write testable conditions for a story before it enters the refined tier, it does not belong there. When I walk into a team that has never done proper refinement, the first thing I ask to see is the gap between their top ten items and what their last three sprints actually delivered. There is almost always a meaningful mismatch. Stories get refined and then something newer takes the spot, so the refined story gets shuffled down, abandoned, re-added, shuffled down again, and eventually nobody remembers what the acceptance criteria were. I solve this by implementing a tiered state machine in the workflow: Backlog, Ready, In Progress, Done. Nothing moves from Ready to In Progress without a Definition of Ready checklist being visibly checked off. The checklist usually includes things like clear acceptance criteria, estimated size, identified dependencies, and a named product owner who can be paged during the sprint. Teams that actually enforce this see their sprint velocity stabilize within four to six sprints because the variance that comes from ambiguous items disappearing mid sprint gets eliminated.
When This All Falls Apart
Backlog refinement assumes you have a product, not just a feature factory. If your organization is reacting to customer support tickets, sales promises, and executive whims with no strategic anchor, no prioritization framework will save you. You will refine well and deliver efficiently, but you will efficiently deliver the wrong things. In those cases, the work is not refinement, it is strategy. You need a portfolio layer above the backlog that forces the organization to say no, and saying no usually requires a documented product vision that leadership is willing to defend. I have watched solid refinement processes collapse under companies that treated their roadmap as a suggestion box. Nothing fixes that except executive discipline, which is unfortunately in short supply. There is also a limit to how much refinement helps when the problem is capacity, not prioritization. If a team is consistently at or over capacity and still cannot deliver the top ranked items, refining faster will not help. You will just produce well refined stories that sit there while the team drowns. In those situations, the conversation is about headcount, scope reduction, or removing external work that is being counted as "in scope." Refinement cannot substitute for basic resource planning.
Practical Steps You Can Start Today
Pull your last two sprints and compare what was planned against what shipped. Calculate the carryover rate. If it is above twenty percent, your refinement is either too loose or your estimates are wrong, and you need to fix that before doing anything fancy. Next, pick one sprint worth of items and run them through a dependency audit. You will be surprised how many of them are blocking themselves. Then implement the age rule and the Definition of Ready checklist together. These two moves alone handle the majority of backlog decay in most organizations. Track the change in carryover rate over the next four sprints. If it drops below fifteen percent and stays there, you have a working system. If it does not, the issue is probably upstream, in the strategy or capacity layer, and backlog refinement is the wrong lever to pull. The takeaway is that refinement is maintenance, not magic. It prevents rot. It does not create direction. The teams that treat it like a ceremony collect tickets. The teams that treat it like a disciplined filtering process ship more valuable work with less rework. Most of the time, that is the difference between a product that is going somewhere and a product that is just moving.