
Working With Recombinants And Non-Recombinants In Practice
You run a test cross, score the progeny, and suddenly you're trying to figure out which offspring inherited a crossover chromosome and which didn't. This is the core of any genetics experiment involving linked markers, and it's where most people trip up before they even reach the math. I still remember spending two days debugging a mapping experiment because I'd assumed coupling phase when the parental lines were actually in repulsion. The recombination frequencies came out to roughly 22%, which looked perfectly reasonable on paper, but the parental classes were smaller than the supposed recombinant classes. That should have been the red flag immediately. Once I swapped the phase assumption, everything lined up. The lesson: always verify which alleles are physically linked on each homologous chromosome before you calculate anything.
Recombinants Vs Non Recombinants Cracking The Code Of Genetic Variation
A recombinant offspring carries a combination of alleles that differs from both parental chromosomes. A non-recombinant (parental type) inherits the exact allele combinations that were present on the original chromosomes. The distinction matters because it tells you whether a crossover event occurred between your markers during meiosis. Here's how the workflow actually goes. You start with two homozygous parental lines that differ at the loci you're tracking. Line A might be A B C and line B might be a b c. You cross them to get an F1 heterozygote with genotype A B C / a b c. Then you test cross that F1 to a homozygous recessive tester. Each progeny reveals what gamete the F1 produced, because the tester contributes only recessive alleles. The scoring phase is where people make careless errors. Look at the phenotype or genotype of each progeny and compare it to the two parental chromosome arrangements. If the offspring shows A B c or a b C, those are single crossover classes between the appropriate markers. If you see A b C or a B c, those represent crossovers in the other interval. The most important classes to identify correctly are the double crossover progeny, because they determine the gene order in a three-point cross. They're also the rarest class, so you need sufficient sample size or they'll get lost in noise.
With a standard F2 or backcross population of 200 individuals, double crossovers between markers that are 10 map units apart each should appear roughly once per 50 progeny. That's two individuals in your entire dataset. If you're working with fewer than 100 progeny, you may simply not detect double crossovers, and your map distances will be underestimated. I typically aim for 300 to 500 individuals minimum when doing fine-scale mapping, though coarse linkage groups can be resolved with smaller numbers. One thing that catches people off guard is that recombination frequency is not a direct measure of physical distance in base pairs. A 10 centimorgan region in a heterochromatic block near the centromere can span hundreds of kilobases with relatively few crossovers, while the same 10 centimorgans in a gene-rich euchromatic arm might cover only 200 kilobases. Pericentromeric regions show suppressed recombination. Telomeric regions tend to have elevated rates. If you're trying to correlate genetic map position with physical sequence position, you need a reference genome and you need to accept that the correlation will be loose in some regions and tight in others. Another practical detail: interference. In many organisms, a crossover in one interval reduces the probability of a nearby crossover. The coefficient of coincidence measures this effect. If you observe 3 double crossovers when 6 were expected based on independent probabilities, the coefficient is 0.5 and interference is 0.5. Ignoring interference when calculating expected double crossover frequencies will give you incorrect map distances. You can correct for this by using the observed double crossover class directly rather than multiplying single crossover frequencies together.
Get the Full Details
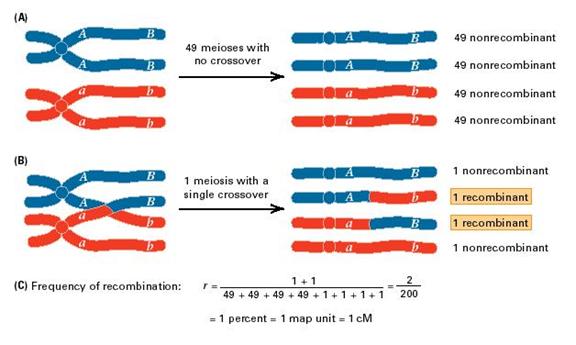
Gene order determination in three-point crosses follows a straightforward logic. Identify the double crossover class. Compare the double crossover genotypes to the parental genotypes. The allele that has switched position relative to the other two markers is the middle gene. For example, if parental chromosomes are A B C and a b c, and the double crossover progeny are A b C and a B c, then B is the middle locus because it's the one that changed its association with the flanking markers. When you move beyond simple model organisms, things get messier. Recombination rates vary between sexes in many species. In humans, females average about 1.6 times more crossovers per meiosis than males, and the distribution across chromosomes differs substantially. In Drosophila, males show zero recombination. If you're building a genetic map from combined sex data without accounting for this difference, your map will be an inaccurate average that doesn't reflect either sex properly. Always separate male and female recombination data when your organism shows sexual dimorphism in crossover rates. Linkage drag is another consideration that matters in breeding programs. When you select for a recombinant that carries a desirable allele at your target locus, you're also inheriting whatever neutral or deleterious alleles happened to be linked in that crossover segment. The smaller the recombination event, the less drag, but small recombination events are rare. In practice, you often need multiple rounds of backcrossing and selection to break unwanted linkages, which adds generations and time to the program. I've seen marker-assisted backcrossing cut this from roughly six generations down to three or four, depending on how tightly linked the unwanted alleles are to your target.
There are also cases where what you think is a recombination event is actually something else entirely. Gene conversion can produce recombinant-like genotypes without an actual crossover. Structural variants like inversions suppress recombination in heterozygotes, which means you won't recover recombinants in that region regardless of how many progeny you score. Translocations can create semi-null recombinant classes that look like missing data rather than biological signal. Before you conclude that a region has unusually low recombination, rule out these confounding factors. The calculation itself is straightforward once you've correctly classified your progeny. Recombination frequency equals the number of recombinant progeny divided by total progeny, multiplied by 100 to get map units. For two-point crosses, that's it. For three or more points, you calculate the recombination frequency for each adjacent pair separately, then add them for intervals that don't overlap. Be careful about adding intervals that share markers without correcting for double crossovers, as this will overestimate distance. Modern pipelines automate much of this classification using software like R/qtl, JoinMap, or TASSEL. You feed them your genotype matrix and their algorithms handle the likelihood calculations and map construction. But automation doesn't replace the need to understand what's happening under the hood. Software will happily produce a map from poor quality data. Garbage in, garbage out applies here with full force. Check your call rates, remove markers with excessive missing data, and verify that your parental genotypes are actually homozygous before you run the mapping algorithm.
What This Means For Understanding Genetic Variation
Recombination is the engine that shuffles existing genetic variation into new combinations. Without it, linked alleles would remain locked together indefinitely, and populations would accumulate deleterious mutations faster than selection could purge them. The non-recombinant classes represent the historical associations that have survived intact, while recombinants represent the novel combinations that selection and drift can act upon. Studying the ratio of recombinants to non-recombinants across a genome reveals the recombination landscape. Hotspots, coldspots, sex-specific differences, and chromosomal features all leave signatures in these ratios. Population genomic methods like LD decay analysis use the same underlying principle, just applied to natural populations rather than controlled crosses. The recombination rate in a region determines how quickly linkage disequilibrium breaks down, which in turn affects the resolution of association studies. If you're designing an experiment, start by clarifying what you're actually trying to measure. Are you mapping a quantitative trait locus? Determining gene order? Estimating recombination rates in a specific region? Each goal has different requirements for population size, marker density, and statistical power. A QTL mapping experiment needs hundreds of individuals and dense markers. A simple gene order confirmation might only need a couple dozen progeny with well-chosen flanking markers.
The most common mistake I see is underestimating the sample size needed. People run a cross, score 50 progeny, calculate their recombination frequency, and declare victory. With 50 progeny and a true recombination frequency of 15%, your 95% confidence interval spans roughly 7% to 23%. That's too wide for most applications. Scale up, or accept that your estimate is rough. There's no shortcut around that. When recombinants are completely absent between two markers, you have a few possibilities. The markers may be extremely tightly linked, within a fraction of a centimorgan. They may actually be the same locus or overlapping sequences. The region may be within an inversion heterozygote, suppressing all crossovers. Or your sample size may simply be too small. Physical mapping or sequencing can resolve the first two. Cytogenetics or PCR-based genotyping for the inversion can address the third. Increasing sample size addresses the fourth. The practical takeaway is that recombinants and non-recombinants are not just categories on a spreadsheet. They represent real biological events with measurable consequences for evolution, breeding, and disease mapping. Getting the classification right determines whether your downstream analysis is useful or misleading. Take the time to verify parental phases, check for double crossovers, account for interference, and use adequate sample sizes. The extra effort saves weeks of troubleshooting later.


