So You Want To Understand Resilience Planning In European Energy Systems
Most people approaching this topic come from one of two camps. They either work in policy and think resilience is a report you write, or they work in engineering and think it's a set of technical specifications. Both are wrong. The actual work sits somewhere in between, and it is usually messier than either side wants to admit. I spent several years embedded with a regional grid operator trying to make their infrastructure actually survive something worse than a bad winter. Not the theoretical "climate change" scenario from a textbook, but the specific, boring kind of cascade failure that happens when three independent assumptions turn out to be wrong at the same time. That experience shaped how I approach this subject now, even though I have not worked in the field directly for a while.
Radina Aneva Architecting Resilience In The Heart Of European Energy Transition
The core idea here is not particularly complicated. You take a system that has always relied on steady baseload supply, and you ask it to absorb shocks it was never designed to handle. Those shocks include geopolitical supply cuts, extreme weather events that coincide across regions, and the rapid retirement of dispatchable generation that happened faster than most planners anticipated. The "architecting" part refers to designing redundancy and flexibility into a system that was optimized for efficiency, not survivability. The first step is mapping your dependencies correctly. Most resilience assessments I have seen fail at this point because they only look at the energy system in isolation. They model generation capacity against demand curves. What they miss is the gas-for-power interdependence, the cross-border transmission constraints, the industrial loads that cannot simply be shed, and the thermal infrastructure that depends on electricity for its own distribution. A heat pump fails when the grid drops. A hospital needs both. When you build the dependency map, you will find chokepoints that do not appear in any standard energy modeling tool. I remember one particular project where we identified that a seemingly minor substation upgrade in one region was actually the single point of failure for three separate interconnection paths. The original design documentation treated it as a routine reinforcement. It was not. We had to redesign the protection scheme and add manual bypass capability before the next review cycle. That took about six weeks and roughly forty thousand euros. The alternative was discovering it on a Friday evening when the whole thing tripped offline.
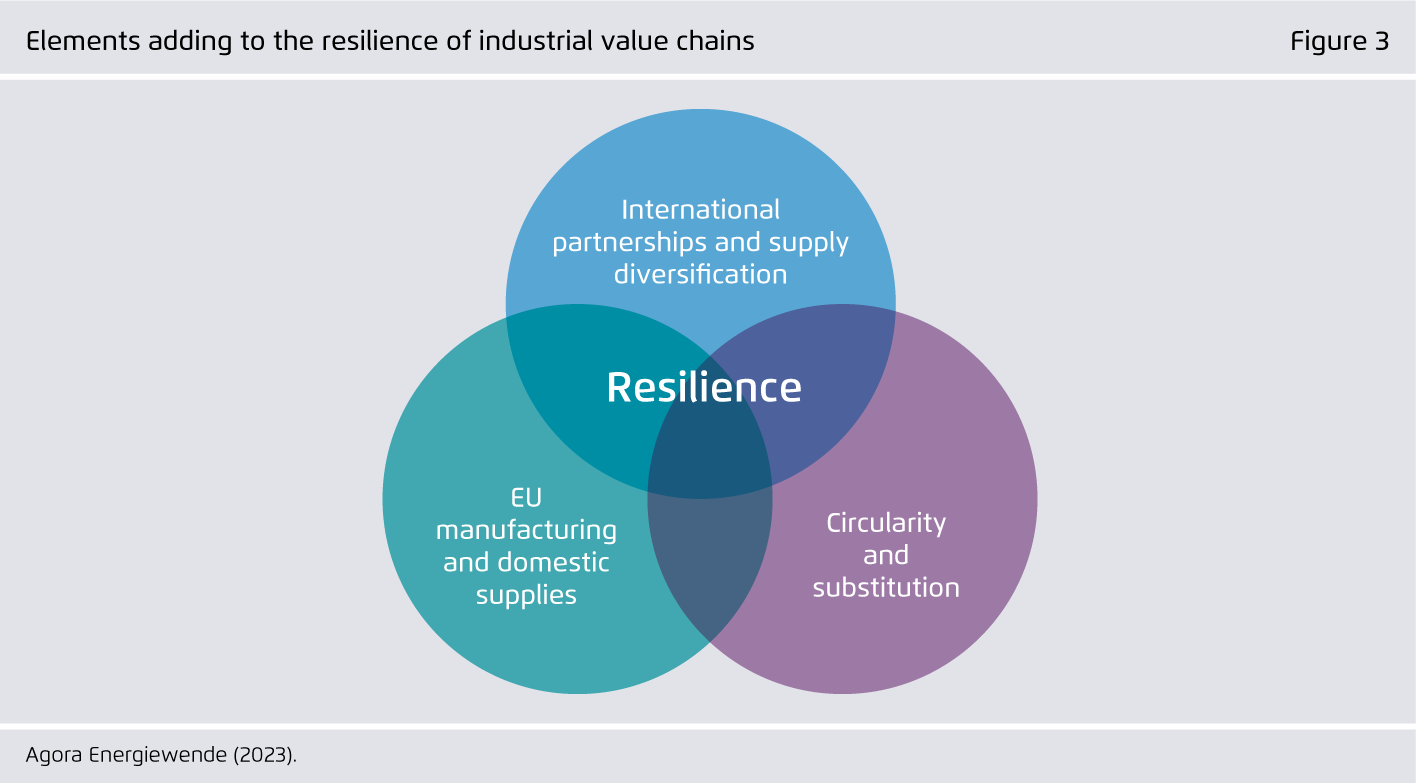
The second step involves stress testing with scenarios that feel uncomfortable. This means running simulations where multiple variables break simultaneously rather than one at a time. Most operators I worked with resisted this because their existing tools were built for sequential fault analysis. The workaround was coupling a power flow model with a probabilistic climate dataset and runningMonte Carlo simulations across seasonal boundaries. The compute cost was significant but manageable if you use cloud instances and batch the scenarios overnight. Resilience planning also requires decisions about what you are willing to sacrifice. Efficiency and resilience are not the same objective, and they often pull in opposite directions. A system optimized for lowest marginal cost will have thin margins for error. Adding redundancy means accepting higher baseline costs. There is no universal answer to this tradeoff, but the decision needs to be explicit and documented rather than buried in assumptions. I have seen too many projects where the resilience layer was added implicitly, then removed during budget reviews because nobody could point to a specific requirement that demanded it. Another counter-intuitive point that beginners miss is that diversification alone does not equal resilience. If all your diverse supply sources share the same vulnerability, you have not improved your position. We saw this clearly when European gas supplies diversified away from one source only to become dependent on a different single point of failure through liquefied natural gas terminals. The lesson is to map vulnerabilities, not just supply routes.
Get the Full Details

Implementation looks different depending on your scale. For a national transmission operator, you are dealing with interconnection agreements, regulatory frameworks, and multi-year investment cycles. For a municipal energy planner, you might be working with a budget that could cover a fraction of what seems necessary, which means prioritizing the most critical nodes and building phased resilience rather than attempting full coverage at once. Neither approach is wrong. They are just different problem spaces. One practical detail that rarely makes it into guidance documents is the importance of communication protocols during actual events. Resilience is not just infrastructure. It is the ability of operators, dispatchers, and coordinating bodies to share information when things go wrong. I worked on a project where the technical systems were sound but the incident response failed because three different organizations used incompatible alerting systems. The fix was a shared messaging standard and regular joint drills, not new hardware. The downside of this approach is that it is slow and expensive relative to the payoff. Resilience improvements rarely show results unless a crisis occurs, and by then it is too late to implement them. There is also the problem of attribution, which makes funding difficult. When a system performs adequately during a stress event, it looks like nothing happened. When it fails, it looks like you did not prepare well enough. The people who fund this work need to accept that they are paying for the absence of disasters, which is a difficult narrative to sell.
If you are just starting out with this, I would suggest beginning with a simple asset criticality ranking. List every component in your system, score it on how many other components depend on it, and identify the ones where a single failure would cascade beyond the immediate area. This takes about a week for a moderately sized system and gives you a clearer picture than any generic framework. From there, you can decide which layers of resilience make sense for your specific constraints. The field is still evolving, and the models are improving, but the fundamental challenge remains the same. You are trying to make a complex adaptive system survive conditions that it has never encountered before, with incomplete information, under political and budgetary pressure. There is no complete solution. There is only better preparation than you would have had otherwise.