Getting Practical Use Out of Columbus Crime Data
I spent about three months digging through every available public crime feed for Franklin County before I stopped treating them like gospel and started treating them like raw material. The platforms are useful, but they require a specific approach if you want actual neighborhood safety insight rather than panic or false comfort. The Columbus Division of Police maintains a public crime dashboard, and several third-party aggregators pull from the same CMRS (Criminal Master Record System) feeds, plus 911 dispatch data. What you see on any of these platforms is delayed, filtered, and often misleading if you don't understand what is being counted and what isn't. Here is how I actually use it. First, I pull the raw data. The city provides API access to their crime incident feed, which is more reliable than clicking through the web interface. I run a Python script that queries the endpoint daily and drops new entries into a SQLite database. Takes about twelve minutes to process a full day's worth of incidents for the metro area. After that, I geocode the addresses, cross-reference with Columbus Neighborhood Association boundary files from the Franklin County Planning Commission, and flag repeat locations using a simple rolling 90-day window.
The output is a color-coded map. Red means more than five reported incidents at the same coordinate within 90 days. Yellow is three to five. Green is under three or no data. This is not a prediction tool. It is a pattern detector. One thing nobody mentions about these systems: the delay. Realtime is a marketing term. Most of the Columbus data lags by 4 to 12 hours depending on the incident type. Property crimes get logged fast because they come from officer reports filed at the precinct. Violent incidents can sit in a queue while detectives finish their initial paperwork. If you are checking the feed after a shooting report and nothing shows up yet, that does not mean it did not happen. It means the database has not caught up. I learned this the hard way on a Tuesday in November when my script flagged a gap in the Near West Side data that turned out to be a two-day backlog from a mass casualty incident processing bottleneck at the central records division. The workaround was straightforward. I added a secondary data source — the Ohio Attorney General's annual crime statistics page, plus the Columbus Dispatch crime beat RSS feed. When my primary feed showed silence for more than 18 hours on a category that usually updates hourly, I switched to manual verification. Cross-referencing with local community boards like the Westerville Community Watch and the Harrison West Neighborhood Association Facebook groups filled the gaps without me having to drive around looking for police tape.
There are serious limitations you need to accept before you rely on any of this. Crime mapping data is presence-biased. Areas with higher police patrol density generate more incident reports, which makes them look more dangerous than they statistically are. Conversely, some neighborhoods report less because residents file fewer complaints or have less trust in the system. A low crime score on the map does not equal safety. It can equal silence. Another issue is the geocoding problem. The Columbus address database still has thousands of addresses that resolve to parcel centroids rather than street-level precision. A reported break-in on a long rural road outside city limits might plot two blocks away from the actual location. This matters if you are using this data for property decisions or route planning. I built a manual correction layer into my system where I flag any incident plotting more than 200 meters from the nearest road centerline and verify against GIS parcel data from the Franklin County Auditor. If you want to set something similar up yourself, you do not need a degree in data science. You need a laptop, basic Python knowledge, and about four hours to get the pipeline running. The Columbus open data portal at data.columbus.gov hosts the incident dataset. It updates every few hours. You can also subscribe to email alerts for specific ZIP codes through the Columbus Police Department's notification system, which catches incidents that the API sometimes misses during peak load periods.
Get the Full Details
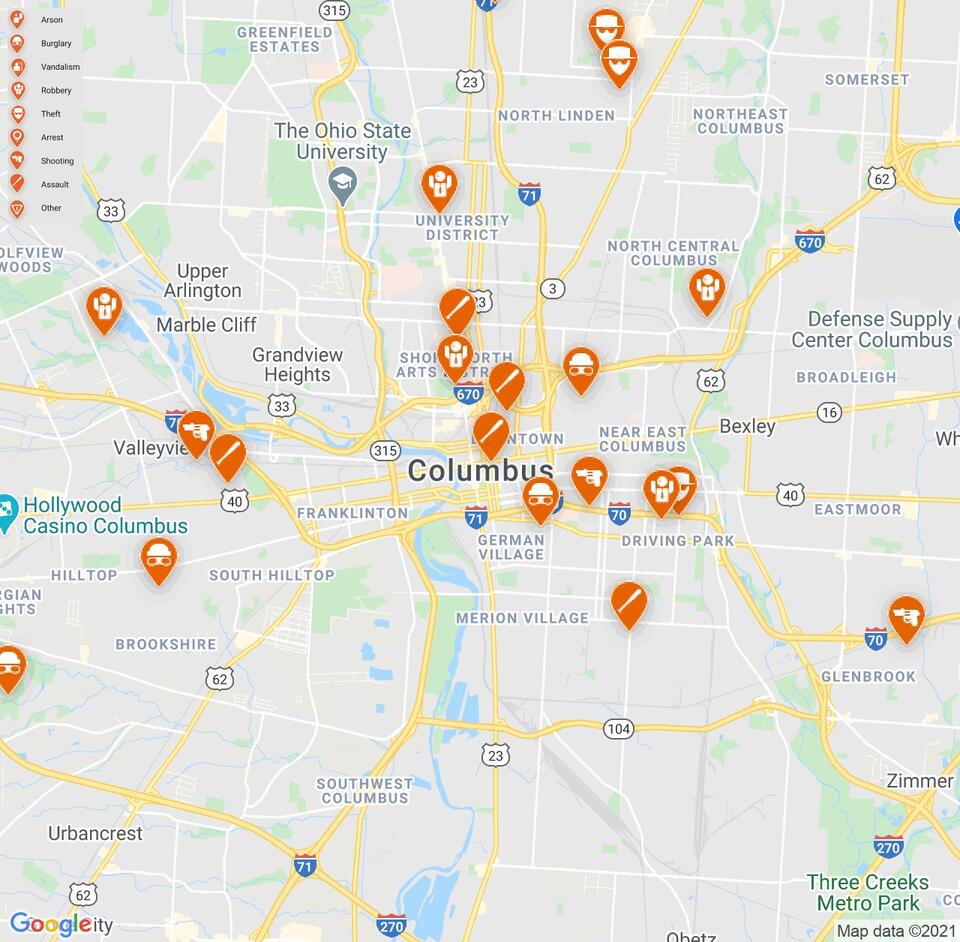
For people who just want quick answers without building infrastructure, the Columbus Police District Crime Maps page gives you the basic view. Zoom into your neighborhood, toggle incident types, filter by date range. It is adequate for casual use. Just remember that a spike in car break-ins this month could be seasonal or it could be a reporting artifact from a new officer on the beat. Context matters more than the numbers themselves. I stopped sharing my map with anyone outside my immediate circle about six months ago. The problem is that once people see color-coded danger zones, they stop reading the nuance. They see red and move. They see green and feel safe. Neither reaction is always correct. The data tells you what was reported, not what happened. Not what will happen. Just what someone decided to report and what a dispatcher had time to log. That gap between reported and actual is where most people get burned. I have seen neighbors avoid a perfectly safe block because a single violent incident from eight months ago kept showing up in someone's unfiltered map query. I have also seen people walk into areas with low reported crime because the real incidents were being resolved through informal community mediation before they ever entered the system. Both outcomes are real. Both are invisible unless you understand what the data cannot show you.
My current setup runs automatically. The script checks Columbus PD feeds at 6 AM and midnight, pulls new incidents, compares against the database, and generates an updated map. If any incident falls within a 500-meter radius of my tracked addresses and involves a violence or burglary category, I get an email alert. Total processing time per run is approximately eight minutes on a standard laptop. The database sits at around 45,000 records going back to 2020, which is enough history to see seasonal patterns without so much noise that the signal gets lost. Most people do not need this level of detail. But if you are buying property, changing your commute route, or just want an accurate picture of your neighborhood instead of whatever the news cycle is selling you this week, building your own pipeline is the only way to cut through the noise. The raw data is there. It is just not presented in a way that protects you from your own assumptions.