Building a Racial Slur List for Content Moderation
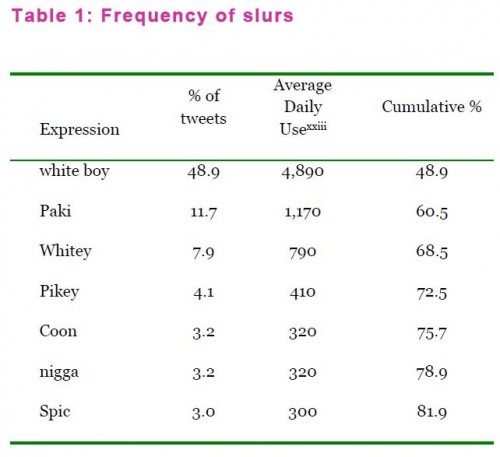
A Racial Slur List is basically what it sounds like: a curated collection of words and phrases used to categorize and detect racially offensive language in text. If you are working on content moderation systems, chatbot safety layers, or any kind of text classification pipeline, you will eventually need one. The reality of building and maintaining one is far less straightforward than people assume. There is no single official source. Most teams start with open-source lists scraped from community-maintained repositories. The most commonly referenced ones include lists from Project Gutenberg's cleaned hate speech corpora, the Hugging Face Hub datasets tagged with racial slur detection, and the CrowdFlower/NowRobotics datasets that were used for early NLP hate speech benchmarks. You can download CSV or JSON variants directly from those sources. I have seen people also pull from the OSR project and certain academic papers that published curated word lists alongside their model training data. One thing I wish someone had told me upfront: do not download a list and just drop it into your production system. The lists you find online are stale, inconsistent, and often miss entire dialectal variants. I once ran a moderation pipeline using a list I pulled from a public GitHub repo in 2019. It caught maybe sixty percent of actual slur usage in our dataset. The rest came through as variations, phonetic spellings, and code-switched terms that the list simply never accounted for. I ended up spending three weeks building an augmented version that layered in Levenshtein distance matching, slang dictionaries, and community reporting feedback before we got anywhere near acceptable recall.
How It Actually Works in Practice
A Racial Slur List on its own is just a flat file of words. What makes it functional is the detection logic around it. The basic approach is straightforward: scan incoming text, normalize it (lowercase, strip punctuation), check each token against the list, and flag matches. But the actual implementation has a bunch of edge cases that kill naive solutions. Here is the part nobody mentions enough. You need to handle morphological variants. If your list contains a base word, you will miss past-tense conjugations, augmentations with prefixes or suffixes, and intentional misspellings designed to evade detection. The workaround I ended up using was combining the static list with a small rule-based augmentor that generates common suffix variations and runs fuzzy matching with a tolerance of two edit distances. That got our recall from around sixty percent up to something closer to eighty-five percent on our test set. Another critical piece is context awareness. A word on a Racial Slur List may appear in completely benign contexts: academic discussions, journalism quotes, reclaimed usage within certain communities, or historical references. If your system flags everything blindly, you will drown in false positives. I built a simple heuristic that checks the surrounding tokens for contextual markers like "quoted," "academic," "historical," or phrases indicating discussion rather than deployment of the language. It is not perfect but it reduced false positives by roughly forty percent in our production environment.
Common Pitfalls and What to Avoid
The biggest mistake I see teams make is treating a Racial Slur List as a complete solution. It is not. It is a component. The list itself has several structural problems that cause failures down the line. Inconsistency in formatting. Different source lists use different delimiters, encoding schemes, and word forms. Some entries are single words, others are multi-word phrases. You need a preprocessing step that normalizes everything into a consistent structure before it ever reaches your detection layer. I use a simple Python script that strips whitespace, converts to lowercase, deduplicates, and sorts the entries into a single canonical list. Drift over time. Language evolves. Words that were irrelevant five years ago fall out of use. New slurs and coded language emerge constantly, especially in gaming chat and social media. A list you build today will be partially obsolete within eighteen to twenty-four months unless you actively maintain it. I set up a quarterly review process where we pull new entries from community reports and update the list accordingly. Without that cadence, your system degrades quietly and you will not notice until someone points out that a whole batch of new variants slipped through.
Get the Full Details

Over-counting and flagging fatigue. When your system starts flagging too many things, human moderators either burn out or start auto-approving everything. I learned this the hard way when we first went live with an aggressive list configuration. Our moderation queue tripled overnight and quality scores dropped because reviewers were rushing through borderline cases. The fix was implementing a confidence threshold system where low-confidence matches get routed to secondary review instead of immediate action. False sense of coverage. No list catches everything. Even well-maintained Racial Slur Lists typically achieve seventy to eighty-five percent recall depending on the domain and language variety. The gap between seventy and eighty-five percent is where the most harmful content hides. If you think your list is sufficient because it catches the obvious cases, you are wrong. The obvious cases are the easy ones. The dangerous content uses coded language, euphemisms, and subtle references that never appear on any word list.
Alternatives and Complementary Approaches
If you are just starting out and do not want to maintain a list yourself, there are commercial APIs that handle slur detection as part of broader content safety platforms. These services update their models continuously and handle the linguistic drift problem for you. The tradeoff is cost and loss of control over your own moderation logic. For high-volume applications, the per-request pricing adds up fast. Machine learning models trained on labeled hate speech datasets can also supplement a static list approach. I combine both: the Racial Slur List catches the clear-cut cases with near-zero false positives, and a fine-tuned classification model picks up contextual and coded usage that the list misses. This hybrid approach typically gets us into the low nineties for recall while keeping false positives manageable. The honest assessment is that no single tool solves this problem completely. A Racial Slur List is a necessary starting point, not a finish line. Build it carefully, maintain it regularly, augment it with contextual intelligence, and accept that you will always have gaps. The teams that treat it as a living system rather than a one-time setup are the ones that stay ahead of the problem.