Using R for Urban Analysis in Pittsburgh: A Practical Guide
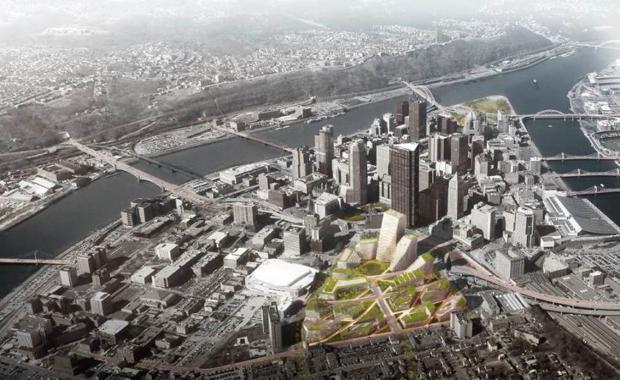
Pittsburgh has spent the last two decades trying to figure out what to do with former industrial land, and the city happens to have one of the more active data communities in the country. The intersection of R programming and urban planning isn't some grand revelation. It is just a tool that a bunch of people here picked up because the city's geography makes standard analysis tools awkward. The term "R Pittsburgh Revolutionizing Urban Development And Revitalization" shows up in local meetups and conference slides sometimes, but it is really just a collection of packages and workflows that have evolved from necessity rather than design. The workflow starts with understanding what data you actually have access to. Pittsburgh Public Schools releases granular datasets. The Pittsburgh Downtown Partnership publishes foot traffic numbers. The Allegheny County GIS office has parcel-level spatial data that updates roughly quarterly. Most people trying to build models from scratch waste weeks just trying to get these datasets to talk to each other. I spent about three weeks in 2022 figuring out why my parcel joins were dropping 40% of records due to inconsistent address normalization across county and city databases. The fix was straightforward once I figured it out. You normalize every address string to the same format before joining. I used the `tidygeocoder` package to standardize addresses through the Census API, then did a fuzzy join with `fuzzyjoin` instead of a hard merge. That recovered the dropped records. The lesson here is that city and county data systems in Pennsylvania do not agree on anything. Assume your keys will not match and plan your normalization accordingly.
Core Packages for Urban Development Work
You will need a baseline set of packages. `sf` handles all spatial operations. `tidyverse` is basically the operating system for everything else. `leaflet` and `mapview` let you visualize results without exporting to desktop GIS software, which saves time if you are iterating quickly. `tmap` is worth learning if you need publication-quality thematic maps. For time series work on things like housing unit completions or employment shifts, `tsibble` and `fable` handle most cases without requiring you to bring in specialized econometric packages. The package most people overlook is `tidycensus`. The US Census Bureau's API is the single best source for tract-level demographic and economic data, and `tidycensus` pulls it in a tidy format that works directly with `dplyr`. You get ACS estimates for every census tract in Allegheny County in about ten seconds once you set up an API key. I used this to layer employment center proximity over neighborhood change data for a revitalization feasibility study. The analysis took maybe an hour total after I had the template script built.
Building a Revitalization Feasibility Model
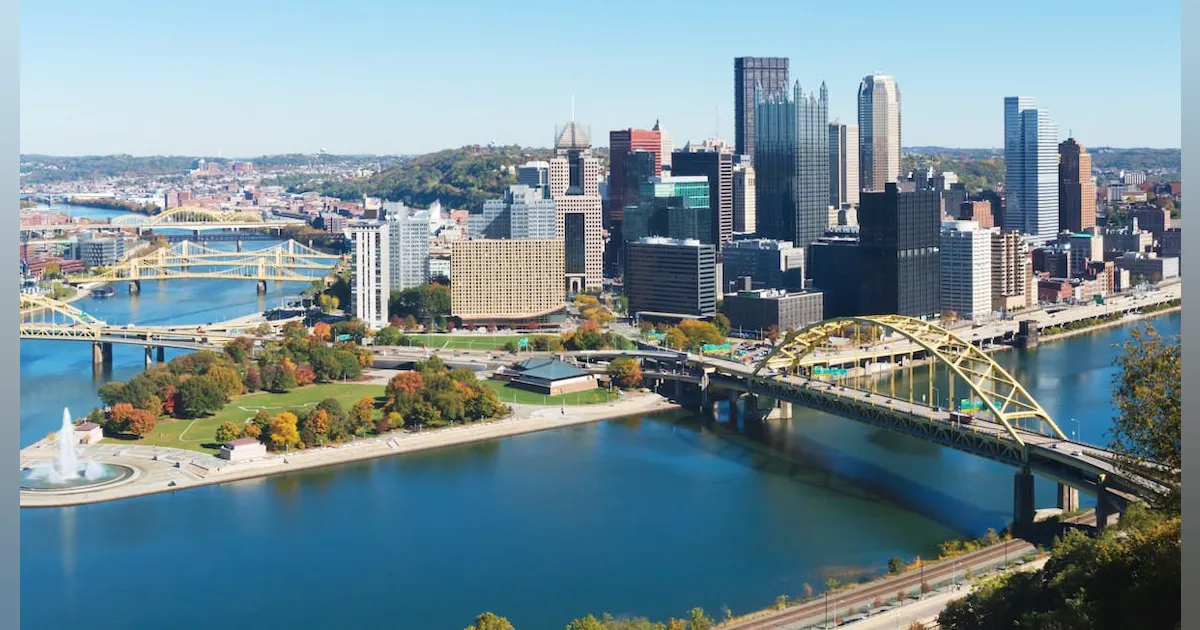
The actual modeling process varies depending on what question you are answering. If you are assessing where new development makes sense, you are usually working with a composite index of accessibility, land availability, infrastructure capacity, and market demand signals. Pittsburgh presents a specific challenge here because the city sits in a valley with three rivers. Distance metrics based on straight lines are nearly useless. You need network-based distance calculations. I used `sfnetworks` to create a road network from Pittsburgh's OpenStreetMap extract, then calculated drive-time isochrones from employment centers using the `osrm` backend. This changed the entire map. Areas that looked underserved by straight-line analysis showed up as well-connected once you accounted for the actual bridge crossings and highway interchanges. The model output shifted which neighborhoods appeared viable for mixed-use development when I factored in real travel times instead of geographic proximity. For the land availability layer, I pulled parcel data from the Allegheny County GIS portal and filtered for parcels meeting certain criteria. Vacant lots under a threshold size, parcels zoned for residential or mixed use, and properties not in floodplains. The floodplain filter alone eliminated roughly 18 percent of candidate parcels. That is a number that matters if you are doing anything involving FEMA or state housing grants.
Get the Full Details

Common Pitfalls in Pittsburgh-Specific Analysis
One issue that catches people off guard is the neighborhood boundary problem. Pittsburgh has officially designated neighborhoods, but those boundaries do not align with census tracts, school districts, or any other administrative geography. If you are aggregating data to the neighborhood level, you need to decide whether to use the official city boundaries from the Department of City Planning or approximate them from tract data. The city provides a shapefile, but it was last updated in 2019. Some neighborhood definitions have shifted slightly due to annexation discussions and rezoning. Another problem is that Pittsburgh's population data is notoriously sparse in certain areas. The 2020 Census showed population decline in parts of the city that continued trends from previous decades, but the granularity of block-level data can produce noisy results in low-density areas. I learned this when building a model for a grant application and got flagged for using raw census counts without applying appropriate smoothing or synthetic estimation for blocks with fewer than fifty residents. The workaround I ended up using was combining census block data with American Community Survey five-year estimates where available, then applying a simple Bayesian smoothing technique using `brms`. It is more computationally intensive but produces estimates that hold up under scrutiny, which matters when you are submitting to state or federal funding sources.
Visualization and Communication
The technical work is only half the job. You will need to present findings to city councils, planning commissions, and community groups who do not speak R. Interactive maps built with `leaflet` or `mapview` serve as a decent compromise because non-technical stakeholders can explore the data themselves rather than staring at static PDFs. I built a dashboard once using `shiny` for a neighborhood planning session. About forty people used it over three hours. The most clicked-on feature was the property tax comparison tool, which tells you more about public priorities than any survey ever could. For static reporting, `ggplot2` with the `sf` integration handles most cases. The default theme settings are not great for policy documents. I recommend setting up a custom theme early that uses the city's official color palette or a restricted set of colors that reproduces well in print. Color blind accessibility matters more than people realize when you are presenting to diverse public audiences.
Limitations and When R Is Not the Right Tool
R is not ideal for real-time dashboards with live data feeds. If you need a dashboard that updates daily with things like permitting status or construction inspection results, a dedicated platform like ArcGIS Online or a purpose-built solution would be more appropriate. R can handle scheduled data refreshes with `scheduled tasks` or CI/CD pipelines, but the maintenance overhead grows quickly and the results are less robust than purpose-built systems. Similarly, R is not the right choice for geodatabase management or large-scale spatial ETL operations. If your workflow requires frequent writes to a shared geodatabase with complex topology rules, PostGIS or FME will handle that more reliably. I used R for the analytical portion of a project where the spatial data plumbing was already handled in PostgreSQL, and the separation of concerns made the whole pipeline cleaner. Trying to manage the database and the analysis in a single R environment turned into a maintenance nightmare. The biggest limitation I encounter regularly is computational performance with large spatial datasets. A parcel layer for Allegheny County containing roughly one hundred and thirty thousand features processes fine. Add satellite imagery analysis or lidar-derived elevation data and you will hit memory constraints quickly. The `terra` package handles rasters better than `raster`, but there are still hard limits around forty or fifty gigabytes of in-memory processing on a typical workstation. At that point, you either move to a cloud computing environment or aggregate the data to a coarser resolution.
Getting Started
If you want to try this yourself, the entry point is straightforward. Install R and RStudio. Create a clean project directory. Set up a virtual environment with `renv` so your package dependencies do not conflict with other work. Install the core spatial packages first, then build out from there. The Pittsburgh Regional Transit API and the City of Pittsburgh's open data portal both have documentation that makes pulling initial datasets relatively painless. The local data science community is active. There are regular meetups, and the University of Pittsburgh and Carnegie Mellon both have publicly available course materials on spatial analysis that apply directly to this kind of work. Reading through other people's GitHub repositories for Pittsburgh-specific projects gives you a sense of the data quality issues you will encounter before you spend time reinventing solutions that have already been documented. There is no single downloadable product called R Pittsburgh Revolutionizing Urban Development And Revitalization. It is a practice, not a tool. The value comes from understanding the local data landscape, knowing which packages solve which problems, and learning through trial and error what works in a city that does not conform to standard planning assumptions. The geographic and institutional quirks of Pittsburgh make it a frustrating place to do this work if you expect standard workflows to apply cleanly. That frustration is also what makes the results more accurate once you figure out the correct approach.