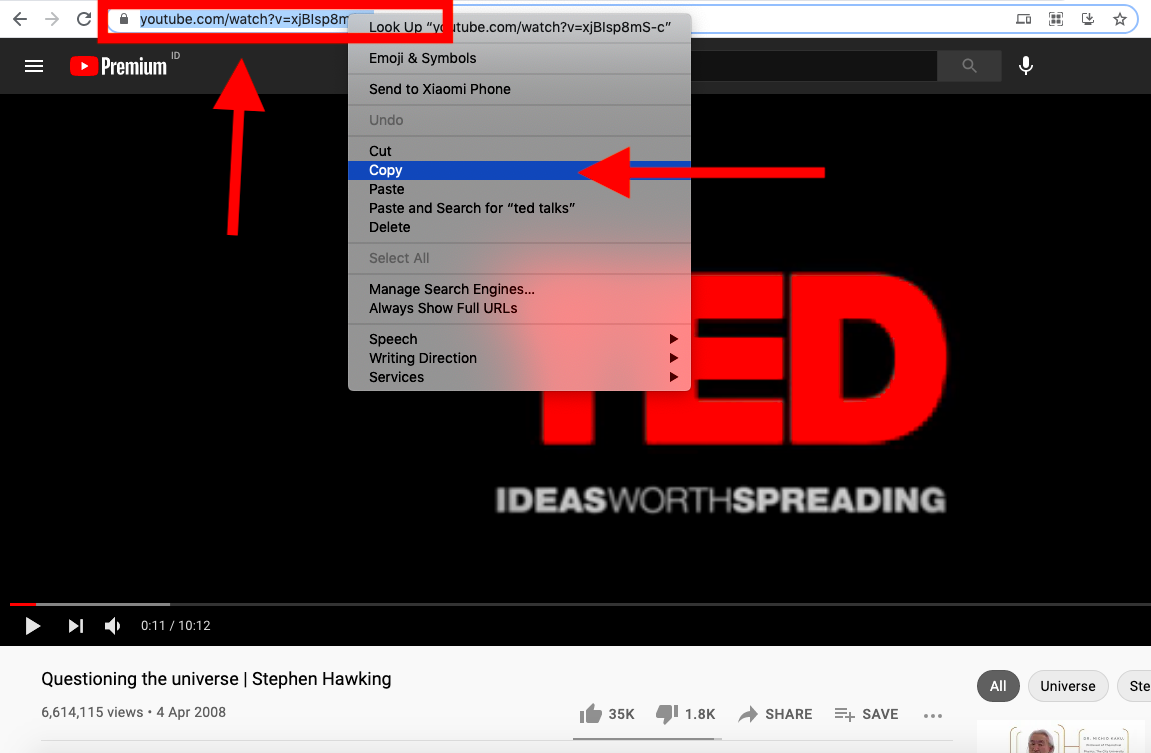
Most people think a YouTube URL is just a link. It's not. The format determines everything about what you can do with it programmatically. Here's the actual structure breakdown.
The standard watch URL looks like https://www.youtube.com/watch?v=VIDEO_ID. The video ID is always 11 characters long — a mix of letters, numbers, hyphens, and underscores. That ID is the single most useful piece of data you can pull from any YouTube link. Everything else is metadata or query parameters.
Then there's the shorthand version: https://youtu.be/VIDEO_ID. Same ID. Less clutter. Easier to parse in scripts.
Timestamps work by appending ?t=345s or #t=345s at the end. So watch?v=VIDEO_ID&t=345s will jump to five minutes and forty-five seconds when the video loads. This matters because some API endpoints and transcript extraction tools ignore timestamps, while others treat them as a parameter. If you're building something that needs to grab a transcript from a specific section, you need to know which approach your tool uses.
Shorts URLs look completely different now. They're structured like https://www.youtube.com/shorts/VIDEO_ID. The video ID is still 11 characters, but you can't use the watch format with a short without YouTube redirecting you. More importantly, some caption extraction services struggle with shorts because they don't have traditional chapter markers or standard-length transcript files.
Embed URLs add an extra layer. https://www.youtube.com/embed/VIDEO_ID is what you'd use inside an iframe. The video ID stays the same. Parameters like autoplay=1 or mute=1 go in the query string after a question mark.
Quick Read How To Use YouTube URLs
If you're trying to get text out of a YouTube video without watching it, here's the workflow that actually works. The fastest path depends on whether you need raw transcript data or a processed summary.
For raw transcript extraction, yt-dlp is the tool I use. It's a command-line program. You install it once and then run a simple command: yt-dlp --skip-download --write-auto-captions --sub-lang en --skip-download "URL". This downloads only the caption file without touching the video itself. The resulting subtitle file is plain text with timestamps stripped if you add --convert-subs srt or --convert-subs txt depending on your needs.
The alternative is using a Python library like YouTube Transcript API, which is lighter weight but less reliable. It works fine for most videos. It fails when creators haven't uploaded captions and haven't enabled auto-generated ones either. That happens more often than you'd expect, especially with shorter videos and content from non-English speaking regions.
I hit a specific edge case last month that took me two hours to solve. I was processing a channel that had over 400 videos with manual captions in English, but also auto-generated captions in multiple languages. The yt-dlp command defaulted to the first available language, which wasn't always English. My output files were a mix of English, Spanish, and some garbled auto-generated noise from songs that had lyrics in other languages. The workaround was to add --list-subs first to see what languages were available, then pipe the results and filter for English specifically. The refined command became a two-step process: list subs, identify the exact language code, then download with --sub-lang en.
For a quicker read without dealing with subtitles manually, there are web-based services. Tools like YouTube Summary with Chat or various AI summarizers let you paste a URL and get a paragraph or two back. These are useful when you need a fast overview. They're terrible when you need accuracy. I found one service that claimed to summarize a technical tutorial video but completely misidentified the programming language being discussed — said JavaScript when the video was clearly about Python. The auto-captions had confused "print()" syntax references with JavaScript console logs.
Here's the counter-intuitive thing nobody tells you: longer videos often produce worse summaries. A 20-minute coding tutorial might yield a 300-word summary that misses the crucial middle section where the actual problem-solving happens. The AI services tend to chunk videos into equal segments and summarize each chunk. The middle chunks get truncated or merged poorly because the context shifts midway through. I learned this the hard way when a summary skipped over a dependency installation step that was the entire point of the video.
For playlists, YouTube URLs support the ?list=PLAYLIST_ID parameter appended to a watch URL. If you want to batch process multiple videos, you can extract the playlist URL and loop through each video ID. yt-dlp has a built-in option for this: yt-dlp --dump-json "PLAYLIST_URL". This outputs JSON metadata for every video in the playlist without downloading anything. The JSON includes title, description, duration, upload date, and available caption languages. You can then filter and process only what you need.
The Things That Break Your Workflow
Private or age-restricted videos won't give you captions through standard API calls. You need cookies from a logged-in browser session. I keep a cookie jar file exported from Chrome and pass it to yt-dlp with --cookies cookies.txt. This takes about 30 seconds to set up and saves hours of debugging later.
Videos under two minutes sometimes don't have transcripts at all. YouTube skips auto-caption generation for very short content because there's not enough audio data to produce reliable captions. I wasted an afternoon trying to extract subtitles from a series of short product demos before realizing this limitation. The workaround was to use speech-to-text libraries on the audio track directly, which is slower but more reliable for short-form content.
Regional restrictions matter too. Some videos have captions available only in certain countries. If you're proxying through a server in a different region, you might get different caption tracks than someone in the source country. I encountered this with a creator who had uploaded German captions for the German audience but only auto-generated English captions for international viewers. The auto-generated English was noticeably worse than any human caption would be.
If you're automating this at scale, rate limiting is the real bottleneck. YouTube allows roughly 10 to 20 caption requests per IP per minute before throttling kicks in. The throttling is soft at first — requests slow down. Then it becomes hard blocks that last anywhere from a few minutes to a few hours depending on severity. I built a simple retry mechanism with exponential backoff that waits 2 seconds, then 4, then 8 between attempts. It turned a pipeline that would fail after the 47th video into one that processes hundreds without issues.
When to Skip the Automation Entirely
Not every YouTube URL needs programmatic. Sometimes the manual route is faster. If you need a one-off summary of a single video and you're not building a tool, just paste the URL into a summarization service. It takes 30 seconds and usually gets you 80% of what you need. The automation path — installing yt-dlp, setting up Python, handling rate limits, debugging missing captions — takes 45 minutes the first time and about 5 minutes after that.
The sweet spot for automation is recurring needs: weekly video digest, batch processing a creator's entire catalog, monitoring a channel for new caption languages, or building a research pipeline that ingests dozens of videos daily. For those cases, the setup time pays for itself within a week.
One more thing about URL parameters that catches people off guard: the listType parameter. If you see URL patterns like watch?v=VIDEO_ID&list=PLAYLIST_ID, the list type defaults to "playlist." But there's also listType=upload which shows a user's uploaded videos, and listType=live for live streams. These behave differently in terms of what data is accessible. Upload lists give you full metadata. Live stream URLs may not have captions at all unless the stream was recorded and processed afterward.
The video ID itself never changes. Even if a creator renames their video, changes the URL slug, or moves it to a private status, the 11-character ID remains constant. This is why parsing the ID is more valuable than parsing the full URL string in most automation scenarios. Store the ID, not the URL, if you're building something that needs to reference videos long-term.
Gallery Quick Read How To Use YouTube URLs
How to Find Your YouTube Channel's URLs: Mobile and Desktop
HOW TO FIND YOUR YOUTUBE CHANNEL URL / LINK ? Quick Tutorial - YouTube
How to get a custom youtube url 2024 | Change Youtube Channel URL or ...
How To Embed A YouTube Video In WordPress (6 Methods)
How To Get a YouTube Video URL Link | Easily Copy Video URL - YouTube