The Reality of Using Python in Finance
Most people who try to bring Python into a finance workflow hit the same wall within a week. They install pandas, load a CSV from Yahoo Finance, and assume they can build something reasonable by the end of the day. The gap between that assumption and a working system is usually where people give up, or worse, ship something that looks correct but isn't. "Py" is just shorthand for Python. The rest is the actual stack. In practice it looks like this: pandas for data manipulation, numpy for numerical operations, scipy or CVXPY for optimization, and then whatever backtesting engine fits the requirement. Sometimes that's a custom loop, sometimes it's something like Backtrader or Zipline, though I have never found those particularly helpful for production-grade work. The real work happens in the data layer, not the optimization layer. I spent most of last year cleaning up a portfolio optimization pipeline at a small hedge fund. The issue wasn't the math. The math was fine. The issue was that the universe of investable securities had a 14% survivorship bias built into the dataset, which meant the backtest was showing returns that would never materialize in live trading. I caught it by comparing the Sharpe ratio of a simple long-only equal-weight strategy against the same strategy using CRSP data, which has survival-adjusted returns. The difference was substantial. We ended up switching to PointFocus data for the universe construction, and the backtest numbers dropped by roughly 40% on annualized returns. That was a hard but necessary correction.
The typical workflow breaks down into three stages. First, data ingestion and cleaning. Second, factor calculation or alpha signal generation. Third, portfolio construction and execution logic. Each stage has its own failure modes, and they compound.
Data Is Where Everything Goes Wrong
Financial data is messy. Prices have splits, dividends, ticker changes, delistings, and holidays that vary by exchange. A naive approach reads OHLCV data from an API and calls it a day. That approach produces garbage results consistently. The practical fix is to build a data layer that handles these events explicitly. Track corporate actions from a source like Bloomberg, Compustat, or CRSP. Map ticker symbols over time because a company can change its CUSIP and still trade under a similar ticker for years. Here is a realistic example of handling a split-corrected price series in Python:
Get the Full Details

import pandas as pd
import numpy as np

Load raw prices and split adjustment factors
prices = pd.read_csv('raw_prices.csv', index_col=0, parse_dates=True)
splits = pd.read_csv('split_factors.csv', index_col=0, parse_dates=True)

Adjust prices for splits (cumulative product of adjustment factors)
adj_factor = splits['factor'].cumprod().reindex(prices.index).ffill().bfill()
adjusted_prices = prices.div(adj_factor, axis=1)
adjusted_prices = adjusted_prices.dropna()
This is basic but it does not work correctly if you do not align the indexes properly. I have seen people divide by the wrong adjustment column because they assumed the split date matches the ex-date. They do not always match. The ex-date is when the price adjusts. The record date is when you need to own the stock to receive the adjustment. Confusing them gives you a biased return series. Most portfolio strategies rely on some form of alpha signal. In academic finance this is called a factor. In practice it is usually a composite score derived from fundamentals, momentum, or alternative data. The mistake beginners make is computing the signal on the entire available history without considering look-ahead bias. Look-ahead bias happens when a feature uses information that was not available at the time the signal should be generated. For example, using a company's full-year earnings to construct a signal in March of that year. Earnings come out in April or May. If your code uses the annual report without shifting it by the actual publication date, you are cheating the backtest. The fix is to maintain a calendar of event dates and lag all fundamental data accordingly.
A proper implementation looks like this:
Lag fundamental data by reporting date
fundamentals = pd.read_csv('fundamentals.csv', index_col=0, parse_dates=True)
reporting_lag = 90  days from fiscal year end to public release

Shift to ensure no look-ahead
fundamentals_lagged = fundamentals.shift(reporting_lag)
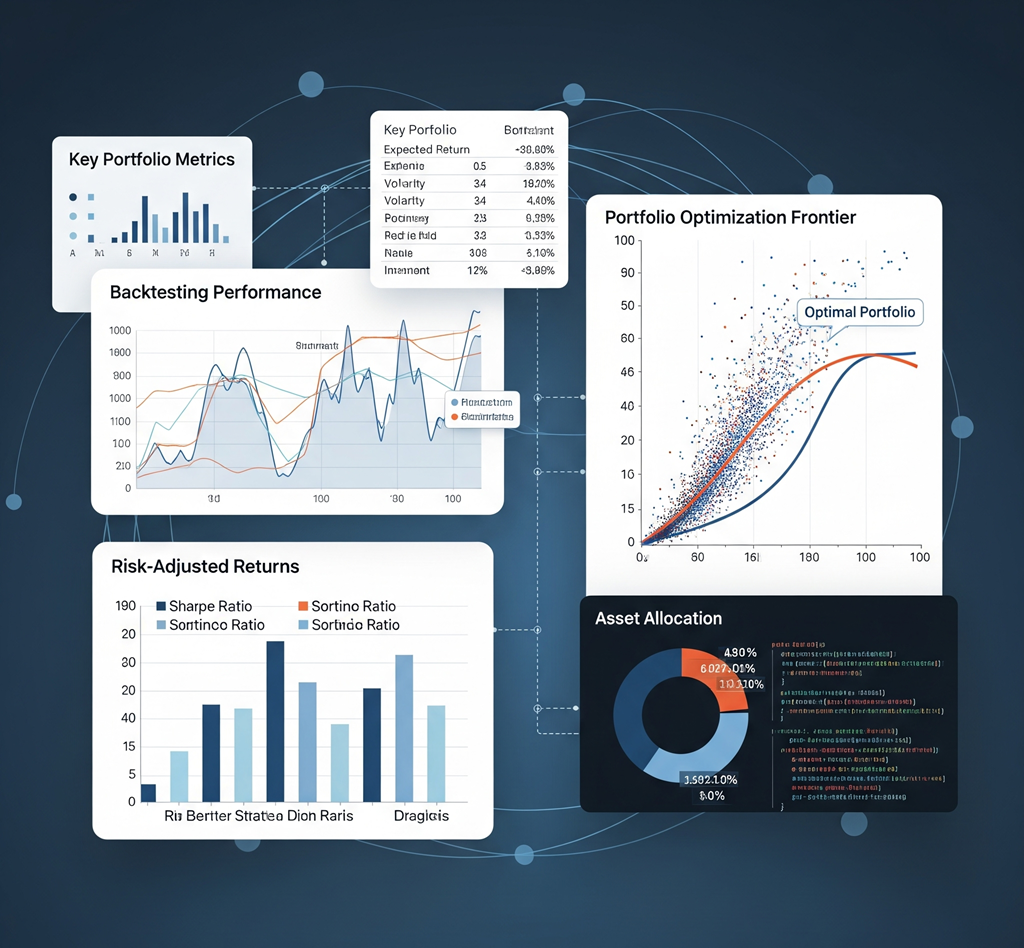
Some people argue for a 10-day buffer to account for market reaction timing. That is valid in certain contexts but adds drag. I usually stick with the lag from the actual earnings release date rather than a fixed offset because it is more accurate. Mean-variance optimization is the standard reference point. Markowitz 1952. The formula is straightforward. You minimize variance for a given level of expected return, or equivalently maximize the Sharpe ratio. The problem is that the covariance matrix is estimated with error, and that error destroys the optimization in practice. Small changes in the input produce wildly different weight allocations. This is well documented in the literature and it is the reason most practitioners use shrinkage estimators or hierarchical risk parity instead of raw sample covariance. Here is a practical implementation using a Ledoit-Wolf shrinkage estimator:

from sklearn.covariance import LedoitWolf
import cvxpy as cp

Compute returns
returns = adjusted_prices.pct_change().dropna()

Shrinkage covariance estimation
lw = LedoitWolf()
lw.fit(returns)
cov_matrix = lw.covariance_

Optimize
n_assets = returns.shape[1]
w = cp.Variable(n_assets)
mu = returns.mean().values

objective = cp.Maximize(mu @ w - 0.5 * gamma * cp.quad_form(w, cov_matrix))
constraints = [cp.sum(w) == 1, w >= 0.02, w = 0.15]
problem = cp.Problem(objective, constraints)
problem.solve(solver=cp.SCS)

weights = pd.Series(w.value, index=returns.columns)
The constraints here prevent any single position from exceeding 15% or falling below 2%. Those numbers are arbitrary but they reflect how actual portfolios are constrained in practice. Without them, the optimizer will concentrate weights in whatever assets have the most favorable estimated return-to-risk ratio, which is almost always noise. A backtest that assumes zero transaction costs and perfect fill prices is useless. The cost of trading in equities typically ranges from 5 to 20 basis points per side depending on liquidity. For less liquid names it can exceed 50 basis points. Including a reasonable cost model changes the viability of many strategies significantly. Transaction cost modeling in a simple backtest:
def apply_transaction_costs(weights_current, weights_target, price,
                              cost_bps=10):
    turnover = np.abs(weights_target - weights_current).sum()
    cost = turnover * 0.5 * (cost_bps / 10000)
    return cost

In the rebalance loop
for date in rebalance_dates:
    costs = apply_transaction_costs(prev_weights, new_weights, prices.loc[date])
    portfolio_return = new_weights @ returns.loc[date] - costs
    prev_weights = new_weights.copy()
I once tested a momentum strategy that looked strong on paper. After adding realistic slippage and market impact costs calculated from average daily volume, the strategy went from 12% annualized returns to -3%. The signal was real. The costs killed it. This is the kind of result that matters more than any theoretical maximum. Survivorship bias remains the most damaging issue. Using a universe that only contains currently listed stocks excludes delisted companies, which tend to be the worst performers. The S&P 500 is a common source of this problem. If you optimize a portfolio using only current constituents, you are implicitly assuming you could have known which companies would survive decades of selection. The performance will be inflated. Another issue that people overlook is the difference between rebalancing frequency and signal decay. A monthly rebalance on a quarterly signal introduces a mismatch where the portfolio holds stale weights while the signal has already moved. The solution is to align rebalancing with signal generation frequency, or to use a half-life based decay function that reduces position weights as the signal ages.
Correlation instability is the third major problem. Covariance estimates from the last 60 days are not predictive of future covariance, especially during market stress. I use a rolling half-life decay approach where older observations contribute exponentially less, combined with a minimum lookback of 120 days to keep the estimate stable. It is not perfect but it is better than a raw sample covariance on 252 days of data.
What Actually Works in Production
The strategies that survive are usually the ones with the most boring implementation. Simple signals with tight constraints, realistic costs, and a disciplined rebalancing schedule outperform complex models that overfit to historical data. A risk parity allocation with volume-weighted transaction cost modeling and a simple sector cap constraint will generally produce more consistent results than a deep learning model trained on daily returns with no transaction cost model. The code I just showed is the kind of thing that actually runs in a production environment. It is not elegant. It is not novel. But it is correct about the things that matter: corporate actions, look-ahead bias, transaction costs, and estimation error in the covariance matrix. The people who skip any of those four steps produce backtests that look impressive until real money hits them.