Working with Pseudogenes Isn't Easy, But It's Necessary
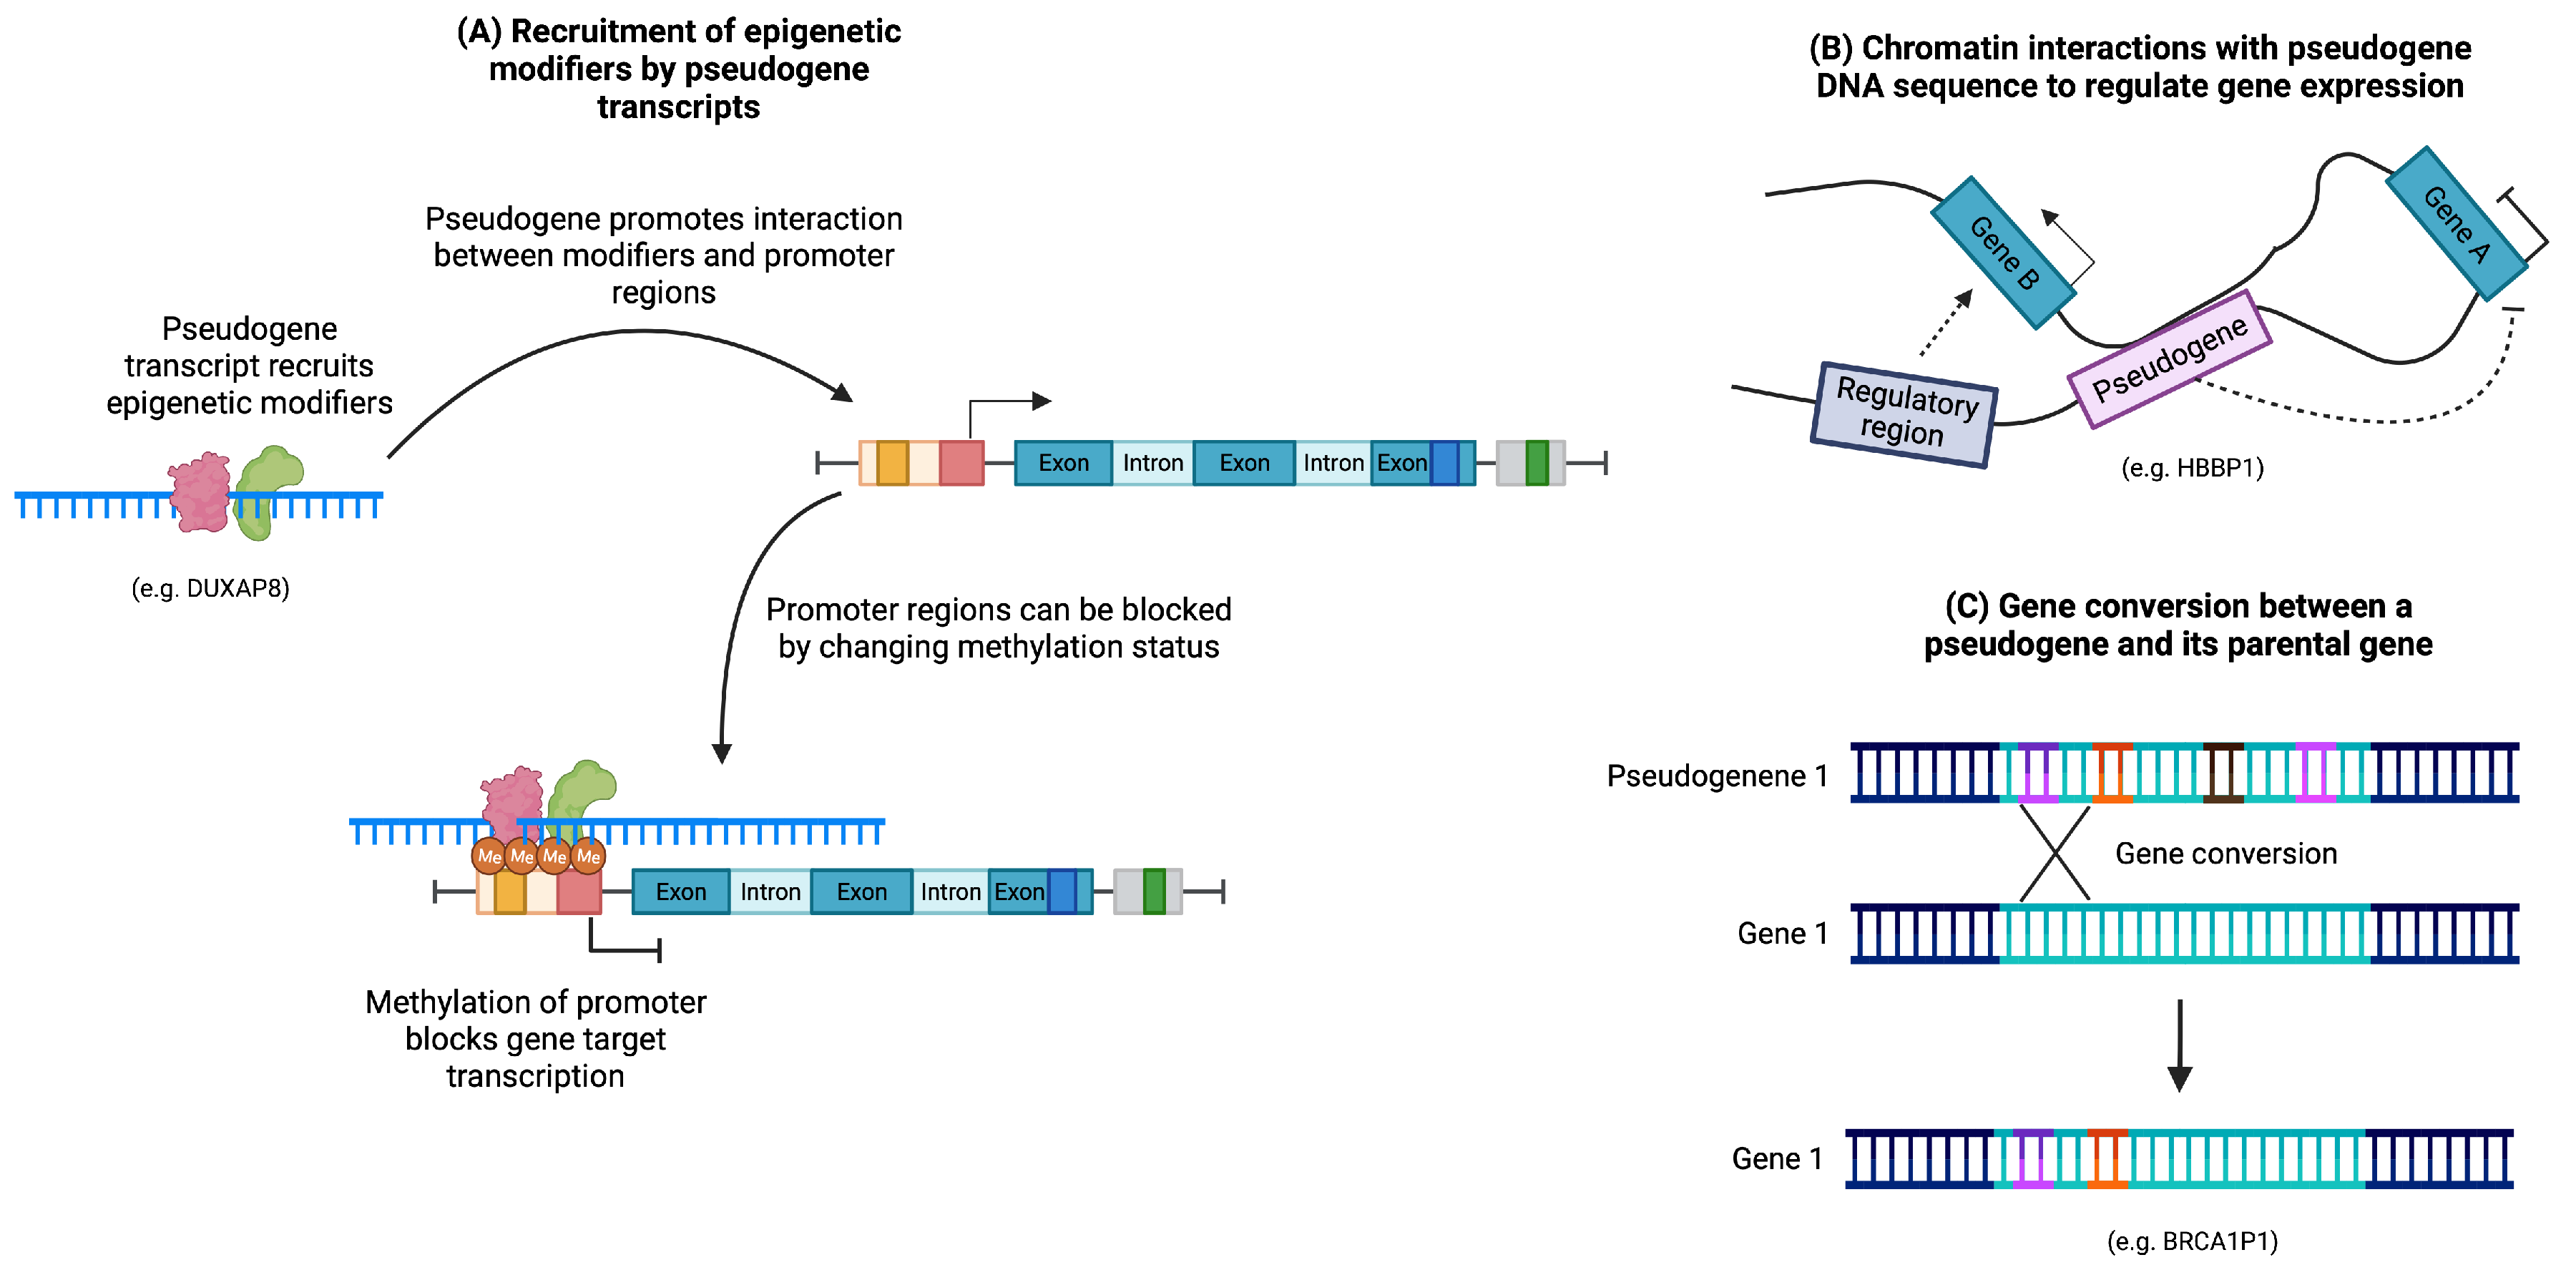
pseudogenes are still showing up as problems in my work. I spent years treating them as junk and just masking them out during alignment. That worked fine for a while, but then you start seeing reads mapping to places that don't make biological sense, and your variant calling looks wrong. Not wrong in a dramatic way, just consistently off in regions you assumed were inactive. The shift happened when people started actually quantifying what pseudogenes do rather than ignoring them. They're transcribed. Sometimes at measurable levels. Some produce RNAs that get processed into small RNAs, and a subset actually gets translated, though that's rarer than most papers claim. The classic textbook definition of a pseudogene as a non-functional relic is too blunt for anything that requires precision.
Pseudogenes Unraveling Their Hidden Role In Our Dna
Here's what you actually do when you need to deal with them in a pipeline. First, you need a reference that distinguishes functional copies from pseudogenes. The GENCODE annotation does this, but the Ensembl flat files don't always make it obvious. You filter the GTF and pull out any feature where the gene_type field says pseudogene, then build a separate FASTA from those sequences. From there you have options. You can create a decoy index by merging the pseudogene sequences into your main genome reference and rebuild your aligner index. If you're using BWA-MEM, that usually means running bwa index on the combined file. Reads that would have mapped ambiguously to both the functional locus and the pseudogene now have somewhere unambiguous to land. This reduces false positive variant calls at the real gene locus, which is the whole point. Another approach, and this is what I use now, is to align to the standard reference first, then take the unmapped or low-quality secondary alignments and remap them against your pseudogene decoy set separately. You get a cleaner picture of what's actually coming from pseudogene loci versus the real genes. STAR handles this kind of two-pass thing better than most people realize, and if you're doing RNA-seq it catches things DNA-level alignment misses entirely.
What Most People Get Wrong
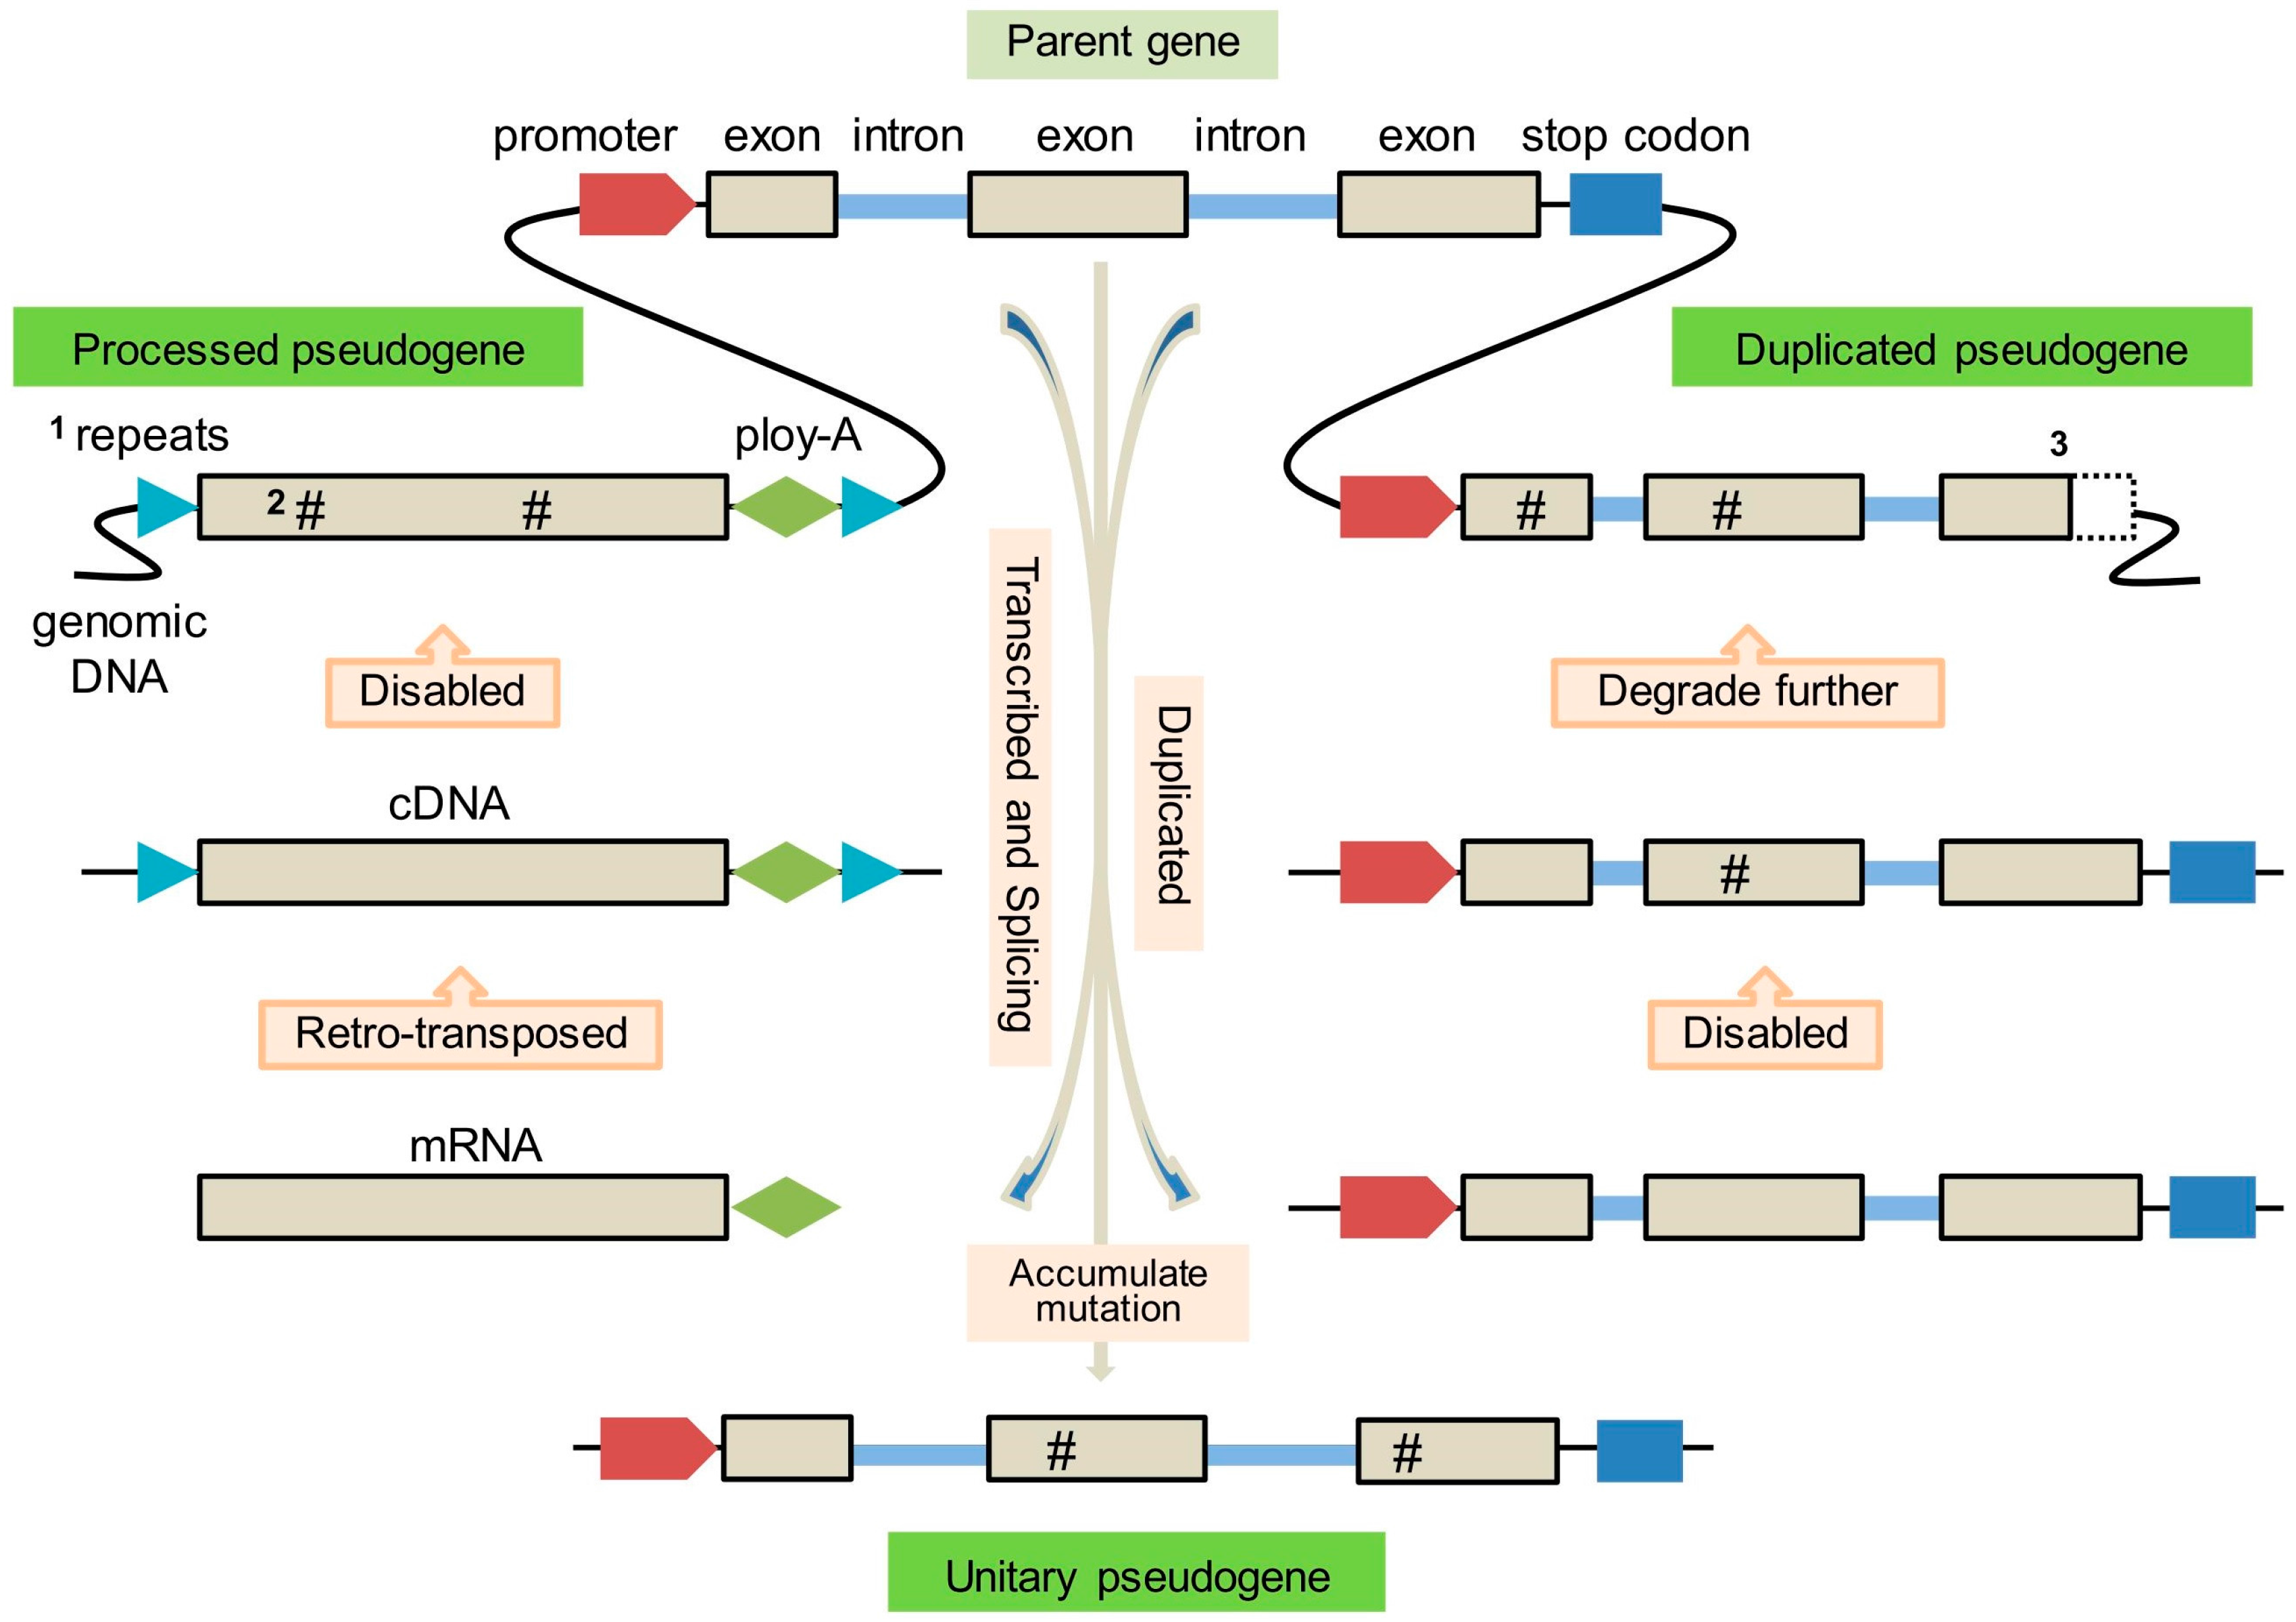
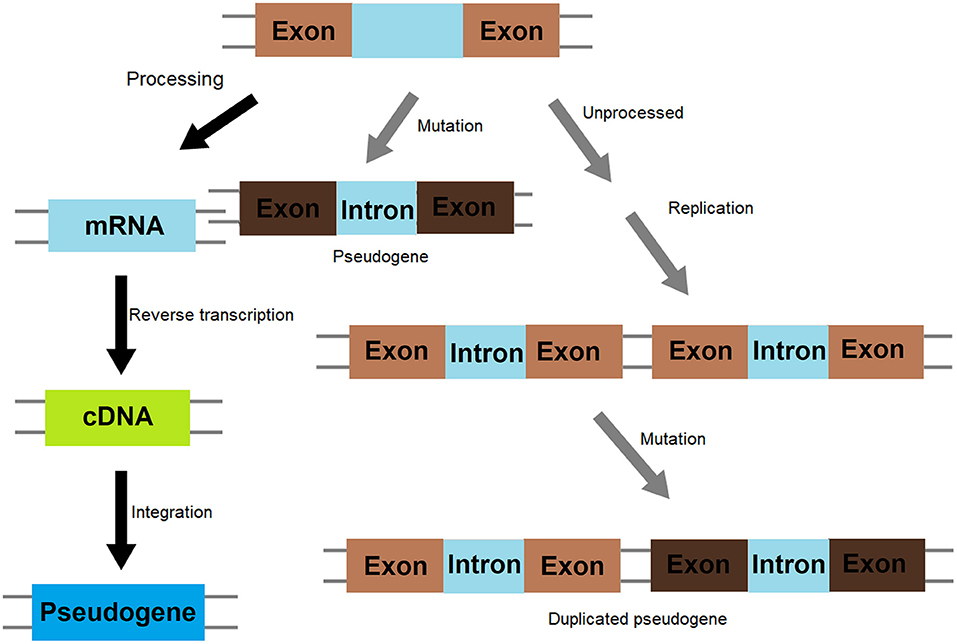
The biggest issue I see is assuming all pseudogenes behave the same. They don't. Processed pseudogenes, which are retrotransposed copies lacking promoters, usually show up as single-exon transcripts if they're transcribed at all. Unprocessed pseudogenes retain intron-exon structure and can sometimes be co-transcribed with their parent gene as read-through transcripts that never get properly processed. Then there are unitary pseudogenes where the original functional copy in the genome has been inactivated. Each category requires a different handling strategy, and treating them identically introduces noise into your analysis. A second mistake is using overly aggressive filtering. I've seen people remove every bit of sequence that overlaps a pseudogene annotation, including flanking regions that might contain regulatory elements. That's unnecessary and it throws away data. The decoy approach keeps the pseudogene sequences in the alignment space without letting them compete for reads that belong elsewhere, and you still get to study the regions around them if you need to.
Get the Full Details

A Specific Problem I Ran Into
Last year I was working on a cancer panel where KRAS had a well-known processed pseudogene on chromosome 6. Standard alignment was pulling variants from the pseudogene locus and reporting them as somatic mutations in the real KRAS gene. The VAFs were suspiciously consistent across samples, which should have been the first red flag. I rebuilt the reference with the pseudogene as a decoy sequence, re-indexed with BWA-MEM2 since we were processing hundreds of samples and the speed difference mattered, and the spurious calls disappeared. The real KRAS variants were still there, just cleaner. If you're working in a space where pseudogenes overlap your regions of interest, this kind of issue isn't hypothetical. It happens regularly with genes like PTEN, BRAF, and several others in the pharmacogenomics space where CYP2D6 pseudogenes mess with copy number calling. The workaround isn't elegant, but it's reliable.
Tools Worth Knowing
For building pseudogene-aware references,GENCODE's download page has the annotations you need, and you can extract the sequences with a simple bioawk one-liner or a Python script using Biopython. If you want something more automated, Salmon and kallisto have built-in handling for transcriptome-level pseudogene ambiguity through their quasi-mapping approaches, though they operate at the transcript level rather than the genomic level, so that's a different layer of the problem. pangenome graphs are the next step beyond decoy sequences. Tools like vg and Giraffe let you include pseudogene variants directly in the graph structure rather than appending them as separate sequences. The memory requirements are higher, but for projects where you're already doing variant discovery in pseudogene-rich regions, it's the more complete solution. I haven't fully migrated my workflows there yet, but it's where the field is moving.
When It Doesn't Work
Decoy-based approaches fail when the pseudogene and parent gene are nearly identical, like with the SMN1 and SMN2 system where the sequences share over 99 percent identity. No amount of indexing tricks will perfectly resolve reads between those two loci, and you end up needing long-read sequencing or specialized assays to distinguish them. That's a limitation you should plan for before you start, not discover after you've spent weeks on an analysis. Another practical constraint: adding a pseudogene decoy increases your reference size, which increases memory usage during alignment. For BWA-MEM2 with a human reference plus a full pseudogene decoy, expect roughly a 20 to 30 percent increase in RAM compared to the standard GRCh38 index. If you're running on a shared cluster with strict memory limits, that matters. The annotation itself is also incomplete. GENCODE catches most pseudogenes, but new ones are still being characterized, and some lineage-specific pseudogenes aren't well represented in the reference. If you're working with non-European populations or less-studied genomic regions, the coverage of annotated pseudogenes drops noticeably. You'll get better results by supplementing with species-specific annotations where available, but that adds steps to your pipeline that most people skip because it's easier.
Bottom line is that pseudogenes aren't a clean problem. They're a real source of error in most sequencing workflows, and the fixes are practical but add complexity. The decoy reference approach gives you the most return for the effort in most cases. If you're doing something that requires higher resolution than that, you'll need to invest in long reads or a graph-based reference, and that's a different project entirely.