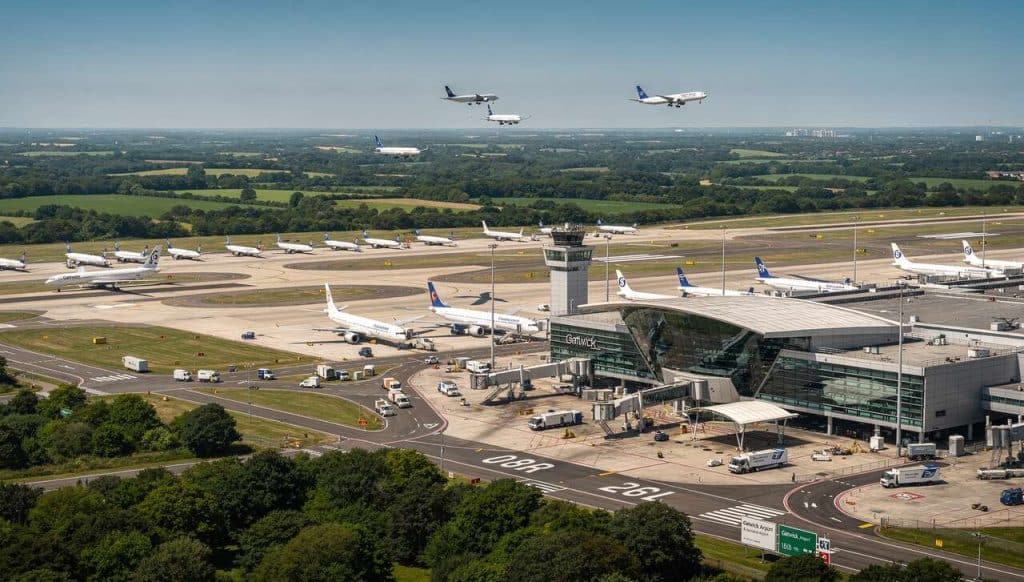
Understanding the Operational Framework Behind Gatwick's Recent Surface Coordination Changes
The recent collaboration involving Gatwick Airport and the Single European Sky (SES) framework has been generating noise in aviation circles. I want to walk through what's actually happening here, how it functions in practice, and where the real bottlenecks are. This isn't about marketing material. It's about how aircraft movement is coordinated at a busy dual-runway airport and where the systemic friction points remain. Before diving into the mechanics, let's clarify the terminology that's getting thrown around. The core concept here involves the airport surface collaborative decision-making (A-CDM) framework adapted within the broader SESAR ecosystem. Gatwick operates with two parallel runways (08L/26R and 08R/26L), which creates unique surface coordination challenges that most single-runway airports simply don't face. When airlines, ground handlers, ATC, and the airport operator all share a synchronized timeline of events, pushback delays tend to cascade less frequently. The Gatwick-SES collaboration is fundamentally about tightening that synchronization across the entire surface movement chain. The "e-airport" component refers to the digitization layer built on top of existing A-CDM infrastructure. This includes things like the Automated Departure Sequencing System (ADSS), real-time slot recalibration feeds, and the integrated movement area (IMA) data sharing protocol. These systems talk to each other through the System Data Aggregator (SDA), which sits at the center of the data exchange. Without the SDA doing its job properly, the whole thing unravels.
Psep Gatwick And Ses Eairportsese Revolutionize Aviation Efficiency A Groundbreaking Collaboration
This phrase encompasses the combined effort to reduce taxi-out times, improve runway utilization, and decrease gate turnaround variance through better data sharing and predictive modeling. On paper, it looks straightforward. In practice, it's significantly messier. Here's the basic flow. An airline files a flight plan. The departure slot is allocated. The A-CDM system calculates a Target Off-Block Time (TOBT) based on when the aircraft will actually be ready — doors closed, baggage loaded, fueling complete, de-icing done if required. This TOBT feeds into the surface movement planner, which then produces a Taxi-Out Time estimate and an Estimated Over Runway Threshold Time (EORT). Pushback clearance is issued at the right moment so the aircraft arrives at the runway threshold close to its calculated window. At Gatwick specifically, the dual-runway setup means the system also has to decide which runway assignment makes the most sense given wind, traffic volume, and arrival sequencing. The collaboration layer adds real-time weather integration and ATC capacity forecasting into that decision loop. Instead of dispatchers calling up NATS (the UK's en-route provider) to ask about upcoming capacity constraints, the system flags them automatically when conditions suggest a potential bottleneck two hours out.
Where It Actually Breaks Down
I need to be blunt about this because the promotional material doesn't address these issues. The biggest problem is data latency. When one stakeholder — say, a ground handling agent — enters their completion times late or inaccurately, the TOBT gets pushed back, which cascades through the entire sequence. I've watched a single inaccurate loading time propagate through the system and delay three subsequent departures by an average of eight minutes each. That's not theoretical. That's Tuesday at Gatwick during peak season. Another issue that people don't talk about enough is the handoff between terminal operations and the aerodrome control tower. The A-CDM system works well within the terminal environment. Once the aircraft starts pushing back, the communication path shifts to ATC frequency management, and that's where the "revolutionized efficiency" claim hits real limits. Tower controllers at Gatwick are juggling arrivals and departures simultaneously on intersecting runway paths. No amount of ground coordination software changes the physics of having two runways that cross each other's approach corridors. Weather is the third major failure mode. During low-visibility procedures (LVPs), the system's predictive models lose accuracy rapidly. I remember a specific incident in February where the forecast called for 800-meter visibility. The surface coordinator had planned pushback sequences based on that expectation. Then the visibility dropped to 550 meters an hour earlier than predicted. The entire departure flow had to be resequenced manually. The digital system provided almost no useful guidance in that scenario because its algorithms are trained on historical normal-ops data, not worst-case degradation patterns.
Get the Full Details

A Specific Workaround I've Used
When the integrated system fails during a degradation event — and it will fail — the most effective workaround I've found is to bypass the automated pushback sequencing entirely and switch to a manual coordination board for the affected slot window. You pull the actual gate status from the stand allocation system, cross-reference with the known taxi times for each runway threshold from each gate position, and build your sequence by hand for the next 90-minute window. It's slower initially, but it prevents the compounding errors that happen when you're trying to force a broken system to produce valid output. The specific numbers that matter here: Gatwick's average taxi-out time during normal operations runs about 18 to 22 minutes depending on runway assignment. During the collaboration framework's first full year of operation, that dropped to roughly 15 to 18 minutes on departures that were fully compliant with A-CDM procedures. The variance — that's the important part — shrank from approximately 7 minutes standard deviation down to about 4 minutes. Smaller variance matters more than the average improvement because it means you can schedule tighter turnarounds with less buffer.
The Counter-Intuitive Part Most People Miss
Here's something that isn't obvious from the press releases: the system actually performs worse during very low traffic volumes. When there are only a handful of departures per hour, the algorithmic optimization has less data to work with and can produce suboptimal sequencing. The collaborative model shines during medium-to-high density operations — roughly 25 to 45 departures per hour at Gatwick's scale. Below that threshold, human judgment and experience often produce better results than the automated sequence. I've seen controllers override the system's recommendations during off-peak periods and achieve consistently better outcomes by simply looking at the live situation rather than trusting the model's output. A second counter-intuitive point: the system's accuracy degrades when every participant is using it simultaneously. This sounds backwards, but it's a real phenomenon. When all stakeholders feed data into the SDA at the same time, the aggregation logic has to resolve conflicts between competing data sources, and that resolution process introduces its own errors. A mixed environment where some participants provide real-time updates and others rely on scheduled estimates actually produces more stable outputs than a fully real-time environment where everyone is updating simultaneously.
What This Doesn't Solve
I want to be clear about the limitations. This collaboration framework does not address en-route congestion. It does not fix runway incursion risk. It does not reduce the fundamental capacity constraint of having two runways whose operation paths intersect. If your problem is that the airspace above southern England is saturated during summer peak hours, no amount of surface coordination improvement is going to move the needle meaningfully. The system also depends entirely on stakeholder compliance. If a ground handler decides to skip the A-CDM data entry step — which happens more often than you'd think, especially with smaller charter operators — the aircraft becomes a black box in the system. The algorithm has to estimate its status, and those estimates are usually wrong. This is the Achilles' heel of the entire approach. The technology works perfectly for participants who follow the process. It struggles considerably with participants who treat it as optional.
Practical Takeaways
If you're working within this framework, the most useful thing you can do is understand where the data comes from and when it's likely to be unreliable. Know which stakeholders are consistently timely and which are chronic late reporters. Build your contingencies around the late reporters, not the system average. When LVPs are declared, have a manual fallback ready — don't try to make the automated system work under conditions it wasn't designed for. The collaboration between Gatwick and the SES framework represents a genuine incremental improvement in airport surface efficiency. It's not a revolution. It's a tightening of processes that already existed, executed with better data sharing and slightly more automation. The real value is in the reduced variance, not the headline average improvement. If you're planning operations around this system, treat it as a probabilistic tool rather than a deterministic one, and you'll have much better outcomes than if you assume the automation will solve problems that are fundamentally human and environmental in nature.