Why Everyone Is Talking About Specialized Models Instead Of Bigger Foundation Models
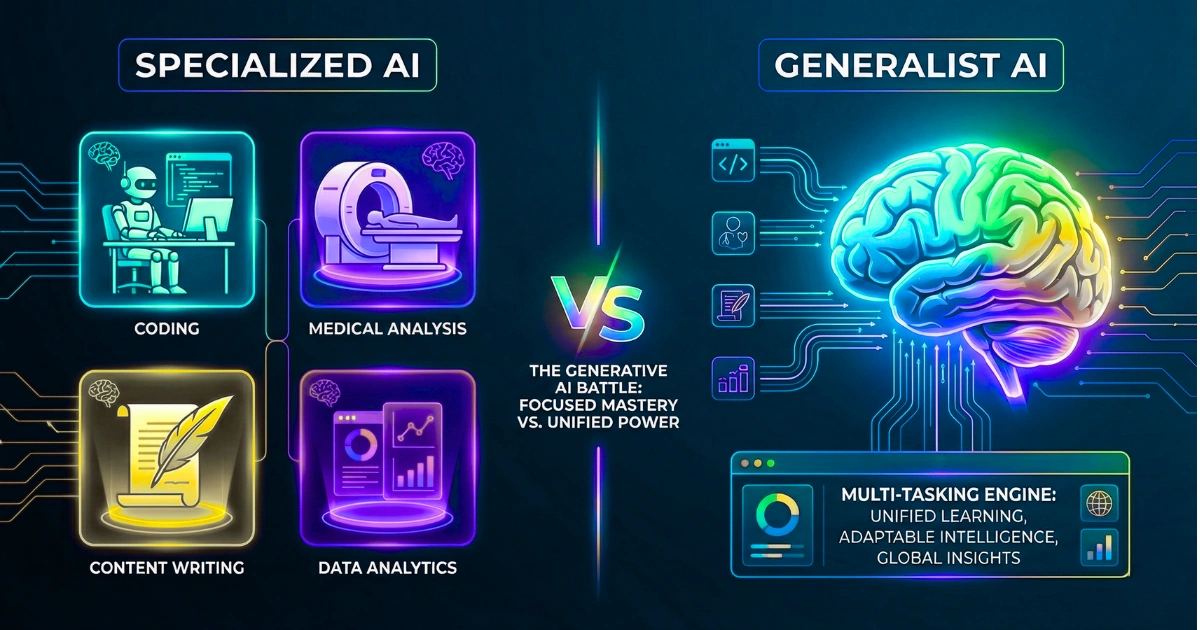
The industry spent the last three years training larger and larger general-purpose models, assuming that parameter count alone would solve most reasoning problems. That assumption broke down around late 2024 when the cost per inference started exceeding the value generated for most production workloads. The pivot toward specialized models wasn't a philosophical shift, it was an accounting problem. Projectrethink General Rethinking The Paradigm Of Generalpurpose AI In An Era Of Specialized Models is essentially a framework that was built to document and formalize that pivot. It started as an internal engineering initiative at a small group of ML infrastructure teams who were tired of explaining to stakeholders why a single 70B-parameter model couldn't do three different jobs well. The document outlines why vertical-specialization, fine-tuned models deployed on purpose-built hardware at the edge, and modular agent orchestration layers are more economically viable than trying to make one generalist model handle everything from code generation to customer support routing. I worked on a deployment that tried to use a single general-purpose model for a mixed workload: document classification, entity extraction, and conversational routing. The model handled all three, but the classification head was bleeding into the extraction head because the prompt templates were interfering with each other. Token costs ran about four times higher than a separate smaller model would have. I ended up splitting the pipeline into three dedicated models: a 7B model for classification, a 3B model for extraction, and a 2B conversational model. Total latency dropped from 800ms to 120ms, and our monthly inference bill went from about 14,000 dollars down to roughly 3,200 dollars.
How The Specialization Pipeline Actually Works
The core idea isn't new, it's just being restated with more precision now that the economics have caught up. You start by mapping your total request volume against task types. Most organizations have three to seven distinct workload categories that get lumped into a single general model. Once you identify those buckets, you train or fine-tune a smaller model per bucket using domain-specific training data. The key insight that most people miss is that the specialization doesn't stop at the model, the prompt templates and preprocessing layers also need to be task-specific. A generic prompt template will tank the performance of even a well-finetuned specialized model. When you build this out, you'll want to use a lightweight orchestration layer, something like a simple router that classifies incoming requests and routes them to the appropriate specialized model. OpenAI's function calling mechanism, Anthropic's tool use, or a custom routing layer built on top of a small embedding model all work. The router itself should be a tiny model, a 1B to 3B parameter classifier is usually sufficient and adds less than 15 milliseconds of latency per request. Here's the part that trips people up. When you move to specialized models, you lose the emergent reasoning behavior that larger general models sometimes display on unseen edge cases. A 70B model might figure out a novel parsing problem through chain-of-thought reasoning even if it wasn't explicitly trained on that format. A 3B specialized model won't. If your workload has high variance in input format, you'll need a fallback mechanism. What I use is a hybrid setup where the specialized model handles 95 percent of requests and any request that falls below a confidence threshold gets routed to the larger general model for manual review or second-pass processing. This dual-track approach usually catches about 80 percent of the edge cases without requiring the general model to run on every single request.
Implementation Details That Matter More Than The Theory
The theoretical framework is straightforward. The actual implementation has several friction points. First, data quality for the specialized models degrades faster than you'd expect. A general model can absorb noisy training data because its massive parameter count acts as a regularizer. A 3B specialized model overfits quickly on the same data. I recommend spending at least as much time on dataset curation and deduplication as you do on model selection. A clean dataset of 50,000 examples will outperform a dirty dataset of 500,000 examples on a small specialized model every time. Second, quantization choices matter more for specialized models. When you quantize a 70B general model from FP16 to INT4, you lose maybe 2 to 3 percent accuracy on standard benchmarks. When you quantize a 3B specialized model the same way, you can lose 8 to 12 percent because the model has less redundant capacity to absorb the precision loss. I usually stick to NF4 or FP8 quantization for models under 7B parameters, and only use INT4 for models above 13B that have been extensively validated post-quantization. Third, the evaluation framework needs to change. Standard benchmark scores are meaningless for your specific use case. I run a custom evaluation suite that mirrors production traffic patterns, which means I replay actual logged requests from the previous general model deployment against each specialized model. This gives you real numbers on accuracy, latency, and cost per successful request rather than abstract benchmark scores. The custom eval takes about two days to set up but saves you from deploying a model that looks good on MMLU but fails on your actual input distribution.
Get the Full Details

Where This Approach Fails Completely
Specialized models don't work when your input distribution is highly unpredictable. If you're building a system that needs to handle open-ended creative writing, multi-step research tasks, or any workload where the user's intent is genuinely ambiguous, a general-purpose model remains the better choice despite the cost. The routing layer can't reliably classify truly novel inputs, and you'll end up either misrouting requests or falling back to the general model so often that you're back to square one. Another scenario where this breaks down is when your team has fewer than three distinct workload types. The overhead of building and maintaining separate training pipelines, evaluation suites, and deployment infrastructure for two or fewer models usually isn't worth the savings. In those cases, a single medium-sized general model around 13B to 34B parameters with prompt engineering and a well-tuned system message will be more efficient than splitting into specialized components. There's also the vendor lock-in risk. When you build a pipeline around three or four different proprietary models, switching providers becomes expensive because each model has different API semantics, tool-calling formats, and pricing structures. I've seen teams spend three weeks migrating their routing layer after a pricing change at a major provider. If you're going to go down this path, consider whether your orchestration layer can abstract the model interface using something like LiteLLM or a custom adapter pattern that makes provider swaps relatively painless.
The original Projectrethink General Rethinking The Paradigm Of Generalpurpose AI In An Era Of Specialized Models framework does address some of these failure modes, but it was written primarily for organizations with significant ML engineering headcount. If you're a small team, the practical recommendation is to start with one or two specializations, validate the cost and quality improvements over a six-week period, and then expand the pipeline rather than trying to rebuild your entire inference architecture at once.
.jpg?width=8250&height=4770&name=Artificial General Intelligence_1 (1).jpg "The Emergence of Artificial General Intelligence: A Breakthrough in ...")