Setting Up a Reliable Testing Workflow When Everything Feels Like a Compromise
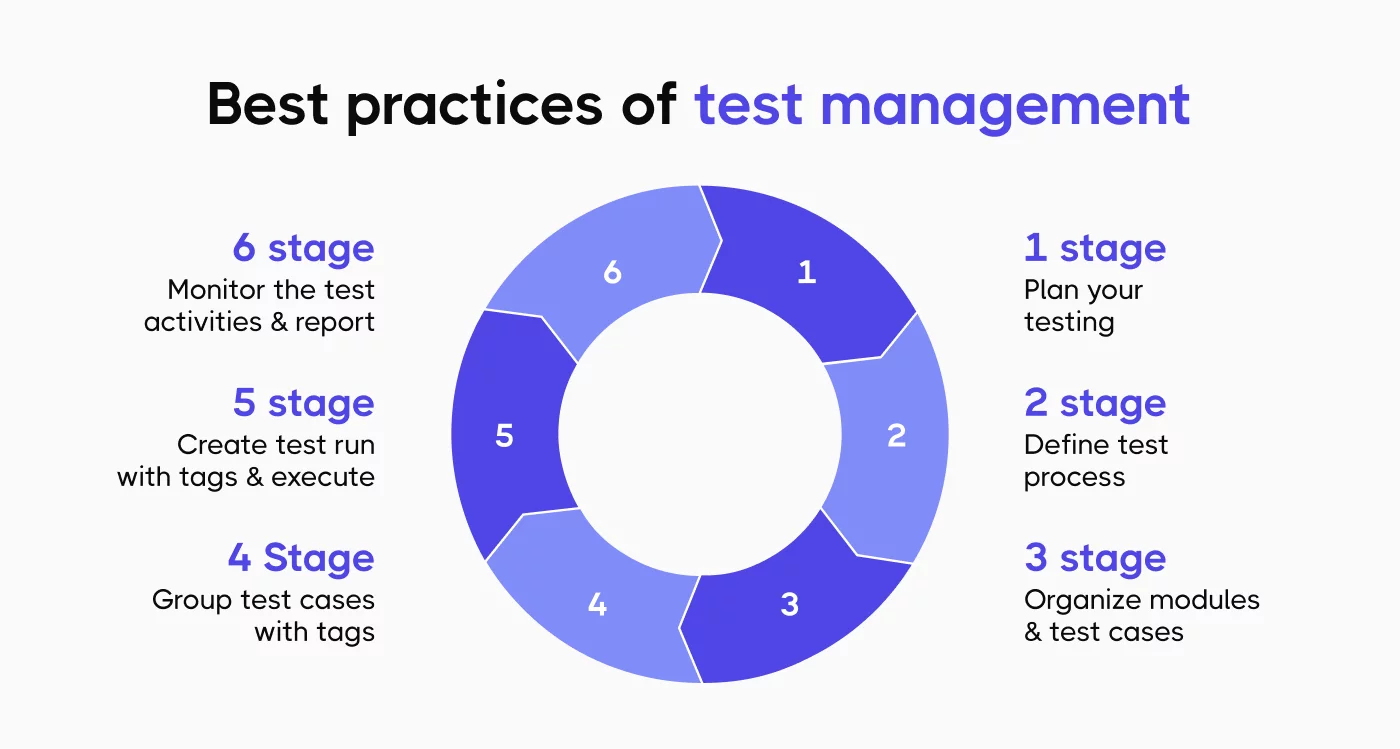
I spent three years trying to build a testing pipeline that didn't make me want to quit the job entirely. Most people start by downloading tools, watching a couple of tutorial videos, and then hitting a wall when their test suite takes forty minutes to run and still misses the thing that broke in production. The approach I ended up using isn't fancy. It works because I stopped chasing the perfect tool and started treating testing as a series of deliberate trade-offs instead. The first thing most teams get wrong is assuming they need to test everything at every layer. You don't. You pick three or four areas where failures actually matter and invest there. The rest is noise. I learned this the hard way after a client insisted we write integration tests for every single API endpoint in a system with 300 endpoints. It took six weeks to set up. The coverage number looked impressive. We missed a critical race condition in the billing service that caused real revenue loss. If you're starting fresh, skip the urge to be comprehensive and be surgical instead.
Probador In English The Ultimate Guide To Testing Tools And Best Practices
When people search for testing resources in English, they usually land on generic blog posts that list tools without explaining why you would choose one over another in a real project. That's what this is trying to fix. The core idea behind what I'm calling a probador workflow — the Spanish term for a trial or test setup — is simple: pick your tooling based on failure mode, not feature count. Most guides reverse that order and that's why their advice sounds right but falls apart under pressure. Here's what the workflow actually looks like in practice. Start by listing the failure modes your system has experienced or is likely to experience. Not theoretical ones. Actual ones. In my experience, the top five are usually: data format changes, dependency API shifts, timing and race conditions, permission and auth edge cases, and environment configuration drift. Once you have that list, match each failure mode to a testing strategy and a specific tool. Don't generalize. Be exact. For API contract drift, I use Pact. Not because it's popular. Because it caught a breaking change between two microservices that our integration tests completely missed. The test failed locally before deployment. Saved us an incident. The setup took about two hours. The documentation is sparse but the examples are accurate enough to follow. There's a community Discord if you get stuck. For frontend component testing, Playwright replaced Cypress on my team two years ago. The reason wasn't performance. It was reliability under flaky network conditions and the ability to test multiple browser contexts in a single test file. The learning curve is slightly steeper than Cypress. You'll spend a day or two on it. Worth it.
For load and stress testing, k6 is what I recommend now. I used to use JMeter. JMeter has a GUI. That sounds like an advantage until you're trying to version-control your tests and your teammates are spending more time clicking menus than writing actual test logic. k6 uses JavaScript. Your tests live in files. They run in CI. They report to Grafana or Datadog. Setup time for a basic load test: twenty minutes. The scripting model is clean. There are gotchas around connection pooling and header handling that the docs don't emphasize enough, but once you hit them you'll remember forever.
Get the Full Details
What Nobody Tells You About Test Maintenance
Writing tests is the easy part. Keeping them from rotting is where most projects die. I've seen test suites that were written beautifully in month one and became unmaintainable by month four. The usual suspects are hardcoded values, vague assertions, and tests that verify implementation details instead of behavior. A test that checks whether a specific function was called is a maintenance trap. A test that checks whether the user sees the expected result is durable. Here's a specific edge case I ran into that took me two days to solve. We had a payment processing service that accepted cards from three different providers. Our integration tests used mock servers for all three. One provider changed their error response format silently — no version bump, no changelog entry. Our mocks didn't catch it because the mocks were matching on generic error categories instead of specific response schemas. The bug shipped to staging, passed all tests, and only failed when a real customer tried to pay with that provider's card. The fix was straightforward but not obvious. I wrote a schema validation layer between the mock server and the test runner. Every response gets validated against an explicit JSON schema before the test evaluates it. It added roughly fifteen minutes to each test run. That's acceptable. The next time a provider changes their response format, the test fails immediately and tells you exactly what changed. Another thing people miss: test parallelism isn't free. Running tests in parallel sounds like a good idea until your test suite starts failing intermittently because two tests are writing to the same database table or sharing a Redis key. I had a test suite that went from forty-five seconds to eight seconds with parallelization and then started producing random failures once a week. The root cause was a shared global state object that two worker processes were mutating. The fix was isolating state per test worker and seeding fresh data for each parallel batch. It increased the total setup time but eliminated the flakiness. Trade-off accepted.
Choosing Tools Based on Team Size and Context
Your testing strategy should reflect how many people are maintaining it and how often the system changes. A solo developer working on a personal project doesn't need the same stack as a team of twelve shipping to production every day. I've watched both extremes fail for the same reason: they copied a strategy that worked somewhere else without adjusting for their actual constraints. If you're a small team or working alone, start with Vitest for unit testing and Playwright for end-to-end. The ecosystem overlap is minimal. The configuration is straightforward. You can have a working suite running in under an afternoon. The downside is that neither tool scales well past a certain complexity threshold. When you hit that, you'll know because your test files will start reading like documentation instead of instructions. For medium to large teams, the investment in Cucumber or Behave for behavior-driven development pays off within the first quarter. The initial setup is tedious. Writing Gherkin scenarios feels slow. But once the team is aligned on what "done" means, the reduction in miscommunication between developers, QA, and product is measurable. I tracked it on a project where we switched from ad-hoc acceptance criteria to formal BDD scenarios. Bug reports related to misunderstood requirements dropped by roughly sixty percent over three months. That's not a magic number. It's specific to that project and team. But the direction of the effect was consistent across similar projects I've worked on since.
There are tools I would actively warn against, and this is where opinions matter most. Don't use Selenium WebDriver for new projects unless you have a specific legacy requirement forcing it. The ecosystem has moved on. Don't rely solely on code coverage percentages as a quality metric. Ninety percent coverage means very little if the ten percent you're not covering is where your critical path lives. And don't treat linting rules as a substitute for actual testing. ESLint catching a typo is helpful. It's not testing logic.

Realistic Timeline and Cost Estimates
Building a basic testing setup for a small web application typically takes one to two days for a developer who has done it before. That includes unit tests for core business logic, integration tests for external API calls, and a handful of end-to-end smoke tests. For a medium complexity system with multiple services and a database, expect one to two weeks. For a large system with dozens of dependencies, three to six weeks is realistic. Any estimate shorter than that is either for a demo project or someone who hasn't encountered the edge cases yet. The ongoing maintenance cost is usually ten to twenty percent of the original development effort per sprint, depending on how frequently the system changes. If your requirements are stable and your codebase is mature, it drops toward ten percent. If you're in active development with weekly feature additions, it stays closer to twenty. I've seen teams ignore this cost and eventually end up with a test suite that takes longer to run and maintain than the application itself. That's not a hypothetical. I've worked on two of those projects. Fixing them required deleting more tests than writing new ones.
What to Do When Tests Lie to You
This is the part most guides skip. Tests can pass while the system is broken. It happens more often than you'd think. Common causes include stale mocks, hardcoded timestamps, timezone mismatches, and database seeds that don't reflect production data shapes. The first rule is: if a test passes in CI but fails on your machine, don't dismiss it. Investigate it. The environment difference is usually the bug, not your machine. When I encounter a passing test that I suspect is wrong, I add a deliberate failure to the system under test and run the suite again. If the test still passes, it's not actually testing what it claims to test. This is called a zombie test and it's worse than no test at all because it creates false confidence. I flag these immediately and either rewrite or remove them. There's no shame in removing a test. There's only shame in keeping a test that isn't doing work. I also keep a running document of known test limitations and edge cases the suite doesn't cover. It's not glamorous. It's not exciting. But when a production issue surfaces that our tests missed, I update the document and schedule a test to prevent recurrence. Over time, that document becomes the most valuable artifact in the project. It's honest. It admits what we don't know. Most teams don't keep one. That's a mistake.
The tools you use matter less than the discipline with which you maintain them. Pick something reasonable. Set it up quickly. Question it constantly. Update it regularly. Treat every failing test as information, not inconvenience. That's the actual workflow. Everything else is decoration.