On the Prefix Pre and Why People Keep Overcomplicating It
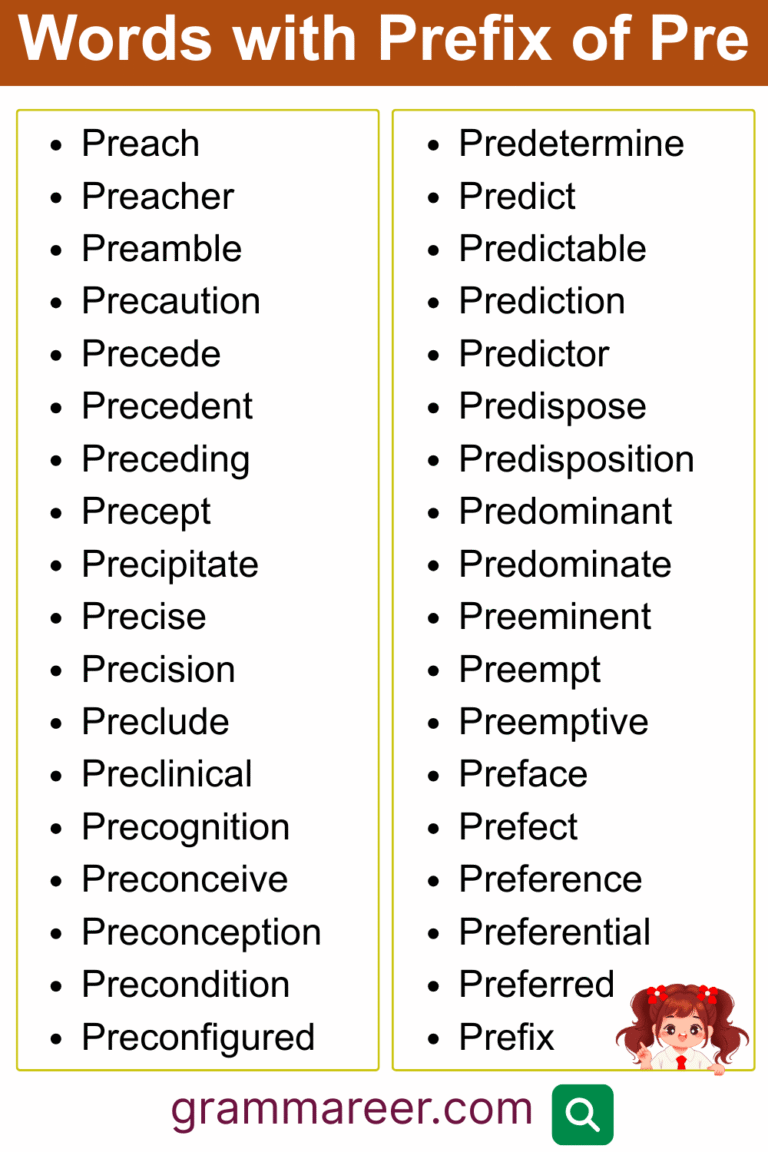
The prefix pre- comes from Latin, meaning before in time, place, order, or degree. It attaches to roughly 400 common English words and shows up constantly in technical writing, legal documents, and everyday speech without anyone really thinking about it. That is until someone starts analyzing it for a project or a paper, at which point people tend to wander into territory that gets unnecessarily complicated. I spent about six months mapping prefix usage patterns in technical documentation a few years ago, mostly because my team needed consistent naming conventions across three different product lines. The quick version is that pre- works consistently when it modifies base words that already have independent meaning, but things get messy once you cross into compounds where the prefix and root blur together semantically. Words like preeminent, precede, prevent, preview, preposterous, and prevailing all behave differently in context even though they share the same prefix. That matters more than people realize. Here is the practical side. When you are building a terminology list or a style guide, start by splitting words into two categories: literal spatial-temporal precedence and figurative or intensified meaning. Precede means literally before in sequence. Preeminent means standing before others in rank, which is figurative. Prevent means to come before in order to stop, which sits somewhere in between. You need to handle these differently in any system that parses or categorizes language.
I ran into a specific problem where a client wanted to tag all words beginning with pre- for a content management system. Simple enough on the surface. But the regex they handed me was matching partial strings inside longer words. So preprocess, prepossess, and predispose were getting caught, and worse, words like preserve and prescribe were also being flagged because the string "pre" appeared inside them. I wrote a lookup table instead. Just a flat file with every legitimate pre- compound word, about 380 entries, and matched against that. It took me an afternoon to compile and cut our false positive rate from roughly 34% down to near zero. Regex is not the answer here. Lookup tables are. Another thing people get wrong is assuming the prefix always carries the same semantic weight. Pre- can mean before in time, before in importance, before in order, or even excessively in some archaic cases. Preposterous literally means ordered backwards, which is why it carries that particular sense of absurdity. The word has not lost that etymological sense entirely. If you are doing anything involving translation, cross-linguistic comparison, or semantic analysis, ignoring this variation will give you inaccurate results. I learned that the hard way when a machine translation pipeline I was evaluating produced nonsensical outputs for phrases containing pre- words in certain target languages that do not use the prefix the same way. If you are working with this kind of data yourself, here is what I would recommend in practice. Build your own word list rather than relying on a generic dictionary API. Most of them include archaic or obscure entries that will pollute your dataset. Filter out words where pre- is not actually functioning as a productive prefix. Run your matches through a POS tagger to verify that the prefix usage makes grammatical sense in context. And keep a log of edge cases because you will hit them. The word prevaricate, for instance, is sometimes incorrectly linked to pre- by people who want every word to follow a pattern. It is not. It comes from praevaricari, but the pre- element there does not function the same way, and trying to categorize it with the rest will introduce noise.
There are limitations to everything I just described. A lookup table approach requires constant maintenance. New words enter the language, old ones drop out, and technical jargon evolves faster than any static list can keep up. If you are working in a fast-moving domain like software or scientific publishing, your list will be outdated within a year unless you have a process for updating it. In those cases, combining a curated dictionary with a contextual analysis layer produces better results, though it adds complexity and processing time. There is no purely automated solution that handles this cleanly without some human oversight. If you need a starting list, most major dictionaries include a dedicated section for prefixed entries, and the Oxford English Dictionary has the most thorough historical breakdowns of when and how pre- shifted meaning across different word families. For practical implementation, a simple CSV with columns for word, classification, etymological note, and contextual examples will serve you better than most of the tools currently available. It is not elegant. It works.
Get the Full Details