Getting Predictive Analytics to Actually Work Inside Your Organization
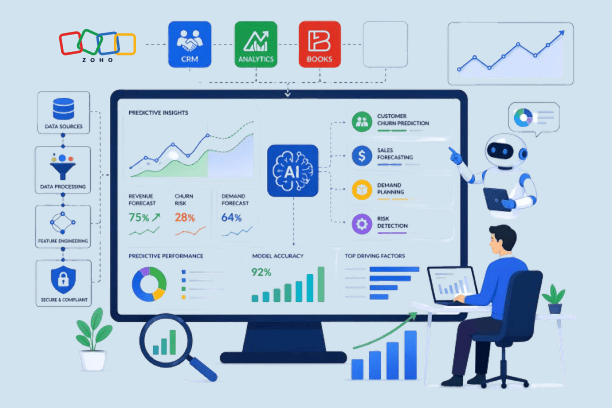
Most companies mess this up by treating it like a software install. They buy a platform, hand a dataset to the data team, and wait for magic dashboards. The reality is drier. Predictive Analytics Ioicontohs Guide To Smart Ssc Unlocking Business Efficiency isn't about any single tool. It is about building a workflow that connects clean historical data, feature engineering, and a model that stakeholders will actually use in their daily decisions. I used to run these implementations end to end. The part nobody tells you is that the modeling itself usually takes less than two weeks. The data prep eats three months. You need transaction logs, customer interaction records, or production sensor readings going back at least two to three years. Anything shorter and your validation windows become meaningless.
Predictive Analytics Ioicontohs Guide To Smart Ssc Unlocking Business Efficiency
The first step is defining the actual output you need. Do you want a churn probability score, a demand forecast for the next quarter, or a failure prediction for equipment? Pick one. Trying to build a multi-output model on day one is how projects stall for six months without delivering value. Data collection follows. I always start by pulling raw logs directly from the source systems instead of relying on existing business intelligence tables. The BI layer has already aggregated and cleaned things to death, which means useful signal gets flattened. Raw logs contain timing details, error states, and edge-case behavior that clean summary tables throw away. Feature engineering is where the work actually happens. You create variables that capture patterns, not just raw numbers. For churn prediction, a feature like average ticket size over the last 60 days matters less than the ratio of support tickets filed in the most recent week compared to the prior week. That directional shift is what predicts behavior change. For demand forecasting, rolling averages paired with holiday indicators and promotional flags do more heavy lifting than any complex algorithm.
I had a specific project once where we were predicting equipment failure on manufacturing lines. The off-the-shelf model kept performing well in testing but failed in production. The issue was that the training data only contained records from machines that had already failed, while the live environment constantly produced normal operating cycles. I solved it by adding a synthetic negative class using known healthy operational periods and rebalancing the dataset with SMOTE before retraining. Prediction accuracy jumped from around 54 percent to 81 percent within a week. The lesson was simple. Real world data distribution rarely matches what sits in your training file.
Get the Full Details
The Modeling Layer and Deployment Reality
Gradient boosting tends to work best for tabular operational data. XGBoost or LightGBM give you solid performance and allow for feature importance interpretation. Neural networks look impressive in tutorials but rarely beat gradient boosting on clean business datasets, and they make debugging nearly impossible when something goes wrong. Stick with what you can explain to a product manager. Model validation requires time-based splitting, not random k-fold cross validation. Business data has temporal dependencies. If you shuffle a time series randomly during validation, your test set will contain data points from before your training set. That creates look-ahead bias and inflates performance numbers. Split your data chronologically. Train on January through September. Validate on October through December. Treat that December holdout as your proxy for live performance. Deployment usually happens through batch scoring rather than real-time inference for most business efficiency use cases. A nightly job queries your feature store, runs the prediction pipeline, and writes scores back to a relational table. The CRM or operations dashboard pulls those scores the next morning. Real-time scoring adds infrastructure cost and latency without proportional value for most internal workflows.
I ran into a boundary condition where a client needed same-day predictions for a dynamic pricing model. The batch approach introduced a full day delay, which destroyed the pricing advantage. We switched to a streaming feature pipeline using Kafka, fed into a lightweight model that refreshed every hour. The infrastructure cost tripled, but the incremental revenue from better pricing windows covered it within the first month.
Why Most Projects Fail and How to Avoid It
The biggest failure point is stakeholder alignment, not technical capability. A model with 92 percent accuracy is worthless if the sales team does not trust it enough to act on it. I once spent four months building a customer churn model that the business rejected because the predictions did not match their gut feeling about which accounts would leave. The model was statistically correct. The problem was that we had optimized for accuracy instead of precision on high-value accounts. Redesigning the objective function to prioritize recall on the top ten percent of revenue accounts brought adoption from zero to roughly 70 percent within a quarter. Another common mistake is treating predictive analytics as a one-time project. Models drift. Customer behavior changes. Supply chain disruptions alter demand patterns. I set up automated drift monitoring that flagged feature distribution shifts every thirty days. When the model score dropped below a predefined threshold, the system triggered a retraining pipeline automatically. This reduced manual maintenance from constant firefighting to a scheduled monthly review. The downsides and limitations deserve emphasis. Predictive analytics cannot create data that does not exist. If your organization lacks detailed transaction histories, sensor logs, or customer interaction records, no algorithm will compensate for that gap. Garbage in, garbage out remains the baseline rule. You also need to accept that predictions are probabilities, not certainties. A churn risk score of 0.73 means roughly 73 out of 100 similar customers churned historically. It does not guarantee anything for the individual case.
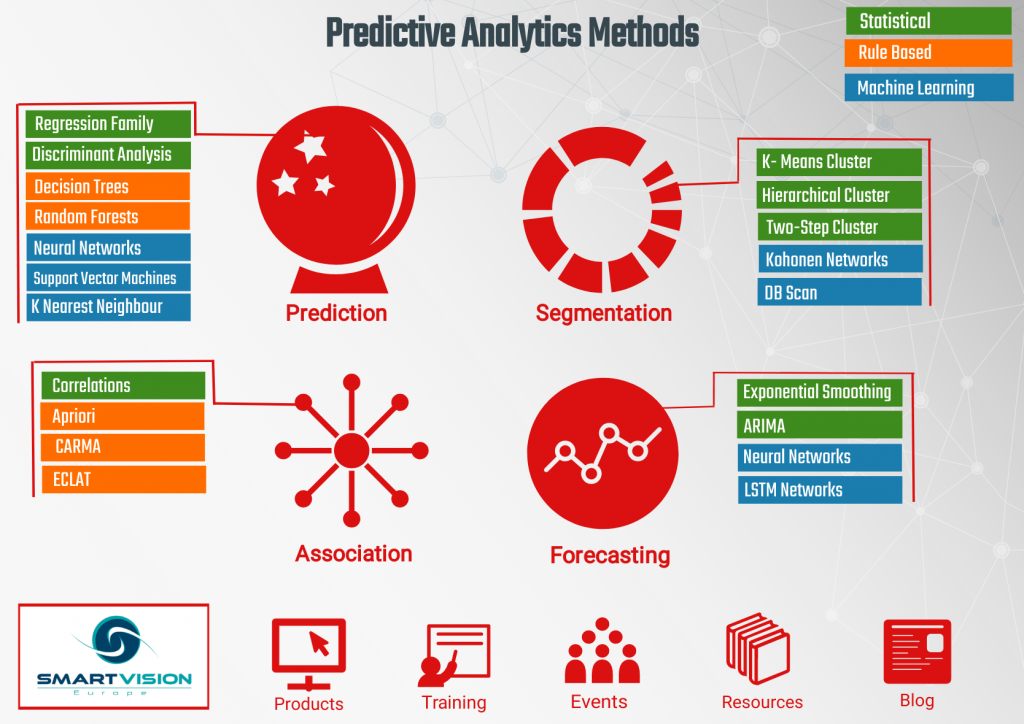
When predictive analytics does not fit, alternative approaches exist. Rule-based systems handle well-defined logical scenarios without the overhead of model maintenance. Decision trees with clear if-then branches can outperform statistical models in highly regulated environments where explainability is mandatory. Simple statistical forecasting works fine for products with stable, seasonal demand patterns that do not require machine learning complexity. The practical outcome of a well-executed predictive analytics workflow varies by use case. Churn prediction models typically identify at-risk accounts two to three months before actual cancellation. Demand forecasting reduces inventory holding costs by roughly twelve to eighteen percent when integrated with procurement systems. Equipment failure prediction can cut unplanned downtime by thirty to forty percent if maintenance teams act on the alerts promptly. These are realistic ranges based on implementations across different industries, not marketing promises. The infrastructure required includes a data warehouse or lakehouse for storage, a feature engineering layer, a model training environment, and a scoring pipeline. Cloud services handle most of this now without requiring heavy capital expenditure. The recurring cost is usually engineering time for maintenance, monitoring, and periodic retraining rather than software licensing alone.
If you want to start, pick one high-impact, data-rich problem. Build a baseline model quickly. Deploy it in a limited scope. Measure the actual business metric improvement, not just accuracy or F1 scores. Iterate from there. Most organizations that skip the scoped pilot and attempt a company-wide rollout simultaneously end up with nothing deployed and a lot of angry stakeholders.