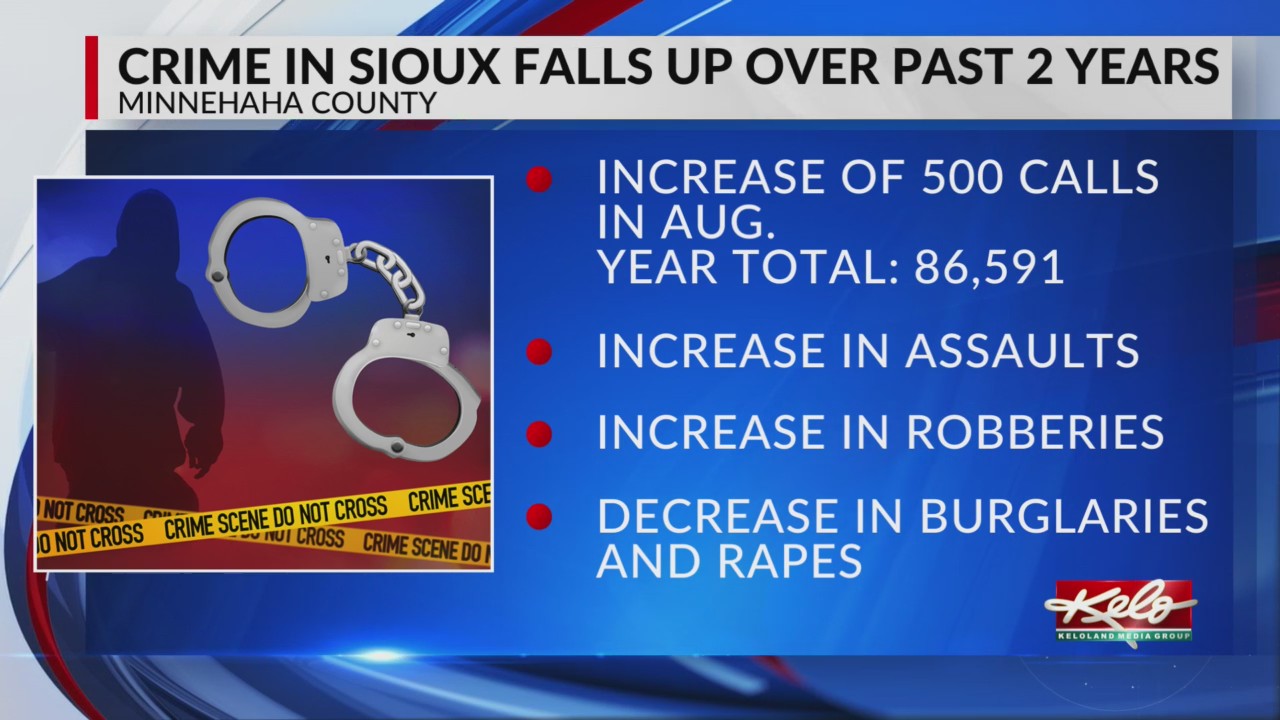
Understanding How Police Call Logs Work In Sioux Falls
Most people think police call logs are simple records of when officers responded to calls. They're not. A police call log is a structured dataset that tracks incident type, location, time stamp, dispatch priority, unit assignment, and resolution status. When you put these records together, you get a picture of what's actually happening across the city in near-real time. Sioux Falls publishes a significant portion of its call data through its open data portal and through periodic public reports. The information covers everything from traffic stops to disturbance calls to theft reports. It's not a live feed, but it is detailed enough to reveal patterns that don't show up in crime statistics summaries.
Police Call Log Sioux Falls Decoding The Pulse Of The City Through Realtime Crime Data
Here's how I actually work with these logs when I need to make sense of them. First, you download the raw data. The Sioux Falls Open Data portal has call-for-service records going back several years. The files are usually in CSV or JSON format, and they contain fields like incident number, dispatch date and time, incident type code, location coordinates, and disposition. The field names aren't always consistent between datasets. I ran into a problem last year where two separate downloads used different codes for the same incident type. One file called it "DIST" for disturbance while another used "NOISE_COMPL" for noise complaint. They were overlapping categories, and trying to merge them required matching on location and time range instead of just the type field. I wrote a quick script that cross-referenced zip code, block address, and timestamp within a ten-minute window to resolve duplicates. Saved me about four hours of manual cleaning. After you have clean data, the next step is temporal analysis. Load the timestamps into a proper date parser. Don't trust spreadsheet auto-formatting. I've seen too many datasets where the date column got misread because some entries used military time and others used standard AM/PM format in the same field. Convert everything to UTC before you do any aggregation.
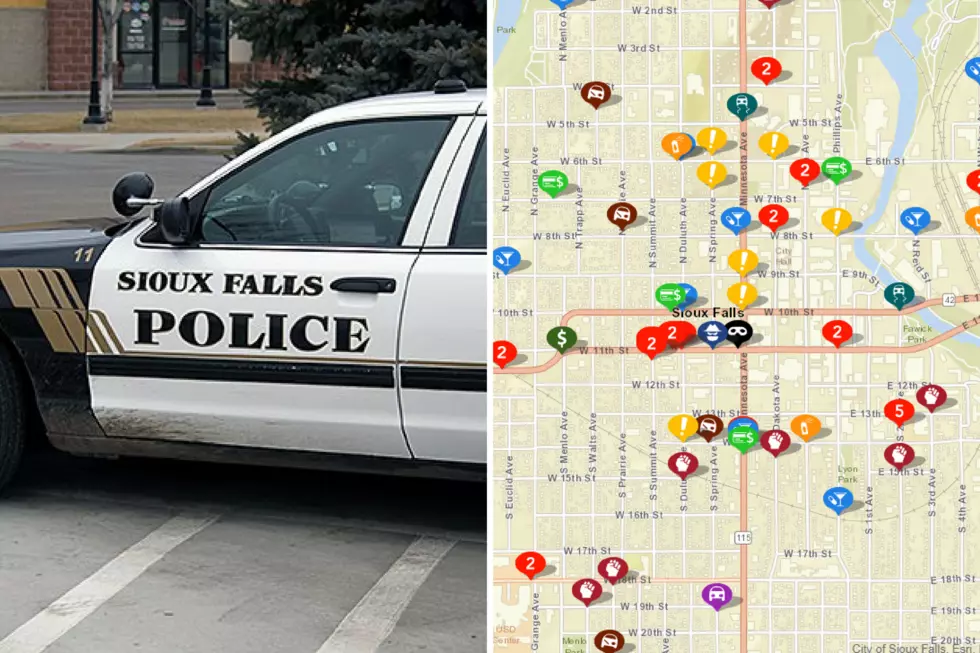
From there you start looking at call volume by hour of day and day of week. This is where you see the real patterns. Weekend nights in the downtown area spike differently than weekday evenings in residential zones. The data tells you exactly which hours have the highest concentration of specific incident types. That's useful information for planners, researchers, and anyone trying to understand service demand across neighborhoods. Location clustering matters too. I use a simple hexagonal binning approach to group nearby incidents. Standard geocoding on address-based data creates gaps because not every call has a precise address. Some entries just have an intersection or a general neighborhood description. Hex bins handle that fuzzy geography better than point plotting and give you a cleaner view of hot spots without the visual clutter. There are limitations you need to account for. The data isn't completely real-time. There's a lag between when a call happens and when it appears in the published dataset. Depending on the department's publication cycle, that lag can be anywhere from a few days to several weeks. If you're trying to use this for immediate situational awareness, it's not going to work. The records are better suited for retrospective analysis and trend identification.
Get the Full Details
Another issue is categorization consistency. Incident types get reclassified over time as the department updates its coding system. I noticed a sudden drop in certain offense categories in one year's data that wasn't a real decrease in activity. It was a code change. The department had merged several subcategories into broader parent codes, and anyone running year-over-year comparisons without accounting for that gets misleading results. Privacy redaction is also a factor. Certain details get removed or generalized in public releases. Exact addresses often become block ranges. Names are excluded. Some incident types get suppressed if they involve minors or ongoing investigations. This means your analysis will always have blind spots, and you should treat the data as a directional tool rather than a definitive record of every incident that occurred. For practical download access, the City of Sioux Falls maintains an open data platform at siouxfalls.opencities.com or through their main municipal website's data section. You can filter by date range, incident category, and geographic area. Export options typically include CSV and JSON. If you're doing this at scale, consider setting up a scheduled pull using an API endpoint if one is available, or a weekly cron job to download the latest dataset and compare it against your local copy for new entries.
The real value comes from combining call log data with other datasets. Population density maps, economic indicators, and weather data layered on top of incident records reveal correlations that nobody would spot looking at the logs alone. I once correlated a spike in particular disturbance calls with construction project timelines in a specific corridor. The calls tracked closely with new residential developments coming online and the associated move-in period. That kind of insight only comes from cross-referencing multiple data sources. If you're just starting out with this, don't try to build something massive on day one. Start with a single month of data from one precinct area. Learn how the fields map to real events. Get comfortable with the quirks of the dataset. Then expand your scope. The learning curve is mostly about understanding what the data can and can't tell you, which comes from actually working through messy, incomplete records and figuring out what conclusions are actually supported by what's there.