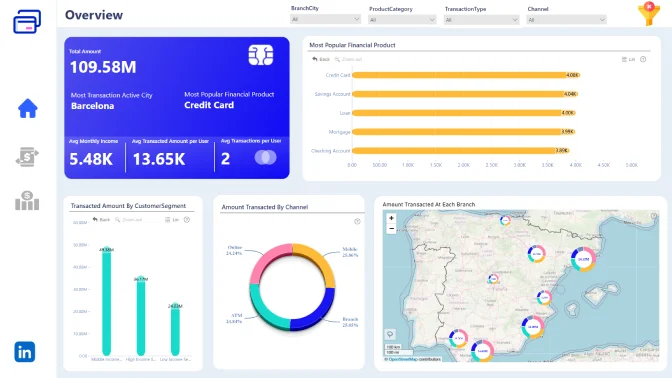
What Plana Crad Bank Data Analysis Actually Involves
Banking data analysis is mostly a cleanup problem. The raw numbers exist, but they're scattered across transaction logs, account summaries, fraud flags, and regulatory reports that were never designed to talk to each other. Plana Crad Bank Data Analysis is the process of bringing those pieces together into something you can actually query without spending three days writing SQL joins that break on a Friday afternoon. I worked with a regional bank that moved about four hundred thousand customer accounts through a nightly reconciliation pipeline. The ledger tables had mismatched date formats, duplicate transaction IDs created when two systems wrote the same record independently, and roughly twelve percent of the records contained null values in the account type field because someone at the branch level could leave it blank. That last one sounds minor until you're trying to run a cohort analysis and your denominators are off by a fifth.
How to Start Plana Crad Bank Data Analysis
The first step is always identifying your source systems and mapping them. Don't skip this. I've seen analysts jump straight into Python notebooks and spend weeks untangling data that was never standardized to begin with. Get the schema diagrams first. Pull the database documentation if it exists, and if it doesn't, run DESCRIBE on every table and compare column names across systems to find where the naming conventions diverge. You need to understand what each table represents before you touch it. A field called trans_amount in one system might be in cents while the same concept in another system is in dollars. A field called acct_status might use 0 for closed and 1 for open in one database and the opposite in another. These are the kind of details that show up during reconciliation and waste hours of your life if you don't catch them early. Once the schema is clear, export a sample from each system—maybe fifty thousand rows—and write a quick validation script. Check for obvious issues: negative transaction amounts where none should exist, dates in the future, account numbers that repeat across different customer IDs. This usually takes about twenty minutes and catches the kind of problems that would otherwise surface when you're three weeks into building reports and suddenly your numbers don't balance.
From there, build your normalized table structure. A typical approach involves creating a central transaction table, a customer dimension table, and an account dimension table, then joining them on standardized keys. The keys themselves need to be consistent—string-based customer IDs work better than numeric ones because some legacy systems pad them with leading zeros and others don't, and converting between formats introduces errors.
Get the Full Details
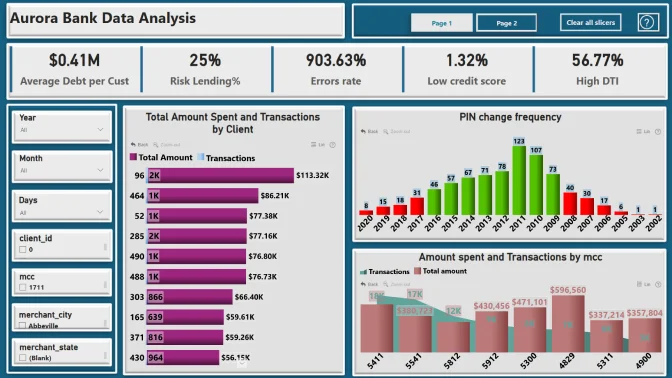
Common Problems and What to Do About Them
Data drift is the most overlooked issue in banking analytics. A report that worked fine in March might produce completely different numbers in May because a business rule changed upstream and nobody updated the transformation logic. One client of mine had a fraud detection model that suddenly started flagging twice as many transactions after a merchant category code update from the payments team. The code changes had nothing to do with the model itself, but the distribution of transaction types shifted enough to throw off the baseline. Duplicate records are the second problem. In my experience, about eight to fifteen percent of banking datasets contain duplicates depending on how the source systems handle retry logic. When a payment fails and the customer retries within the same session, both attempts might be recorded. A simple deduplication pass on transaction ID and timestamp combinations usually handles most cases, but there are edge cases where legitimate duplicate entries exist—think recurring subscription payments that share the same reference number across billing cycles. Missing data is unavoidable. Some fields are optional by design, like a middle name or a secondary phone number. But when mandatory fields go missing at scale, it usually indicates a pipeline issue rather than a data collection problem. I once spent two days tracking down why about three percent of transaction records from a particular branch were missing their currency field. The answer was a firmware update on the branch's ATM system that temporarily dropped the field during a software rollout. The data wasn't lost; it was just sitting in a separate log table that nobody had connected to the main pipeline.
Tools That Actually Work
For smaller datasets under a few million rows, I tend to use Python with pandas and SQLAlchemy. The ecosystem is mature, the debugging tools are good, and you can prototype quickly. For larger datasets, PostgreSQL or BigQuery is more practical. Snowflake works too but adds cost overhead that isn't justified unless you need concurrent analysts querying the same data simultaneously. One tool worth mentioning is dbt for transformation. It turns SQL pipelines into version-controlled code with built-in testing. You can define what a valid transaction looks like and have the system reject or flag records that don't match before they enter your reporting layer. The learning curve is about a week for someone who already knows SQL, and it prevents the kind of cascading errors that happen when a bad transformation runs silently for months. Excel has its place but shouldn't be used for anything beyond validation spot-checks. I've seen spreadsheets with over half a million rows where formulas were breaking, pivot tables were showing stale data, and someone had manually edited cells directly instead of using lookup functions. That's not analysis; that's hope.
Validation and Quality Checks
Every dataset needs a reconciliation step where you verify the numbers add up. Total credits should equal total debits plus any pending transactions. Customer counts should match between the customer table and the transaction table when you group by account. If they don't, you have a join problem or a data loss issue somewhere in the pipeline. I usually run these checks with simple aggregation queries: COUNT DISTINCT per day per source system, SUM of transaction amounts compared against control totals from the general ledger, and distribution analysis on key fields to spot anomalies. A field that normally has eight unique values but suddenly shows twenty-four is either a data entry problem or a system change that wasn't documented. Documentation matters more than people think. A data dictionary that explains what each field means, where it comes from, and how it transforms through the pipeline saves hours of confusion later. I keep a simple markdown file alongside the project with field descriptions, transformation rules, and known issues. It's not glamorous but it's the difference between picking up a project six months later and having no idea what you're looking at versus being able to get back to work immediately.
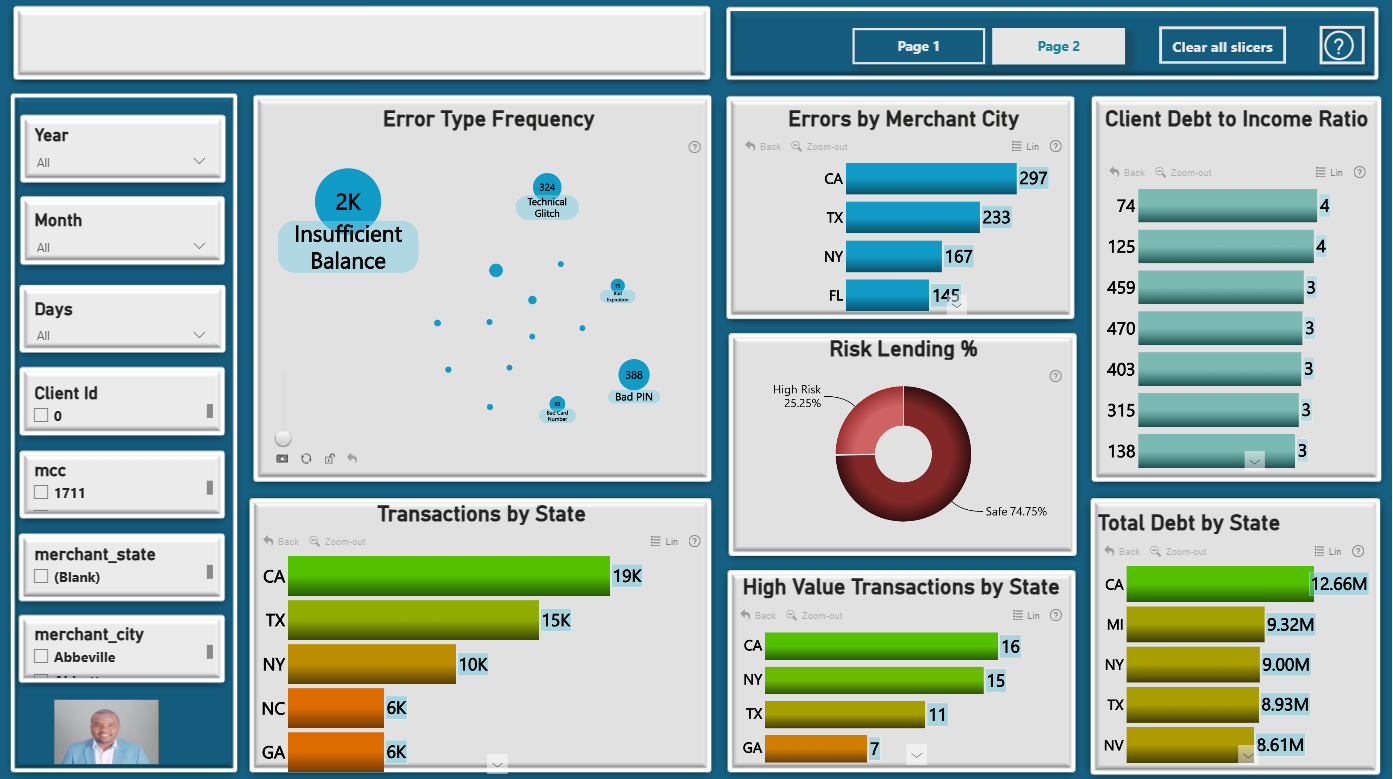
The main limitation of this approach is that it assumes you have access to the source systems and their underlying schema. If you're working with exported files from a system you can't query directly, the analysis becomes much more fragile. You're essentially reverse engineering the structure from samples, and that introduces uncertainty. In those cases, I recommend requesting formal data agreements from the source system owners and building validation tests around every assumption you make. Another limitation is that banking data analysis doesn't solve data quality problems—it surfaces them. The pipeline can only be as good as the source systems feeding it. If the core banking system has structural issues or the branch staff are entering data inconsistently, the analysis will reflect those problems regardless of how sophisticated the methodology is. The best you can do is make those problems visible early so they can be fixed upstream.