Why This Matters More Than Most People Think
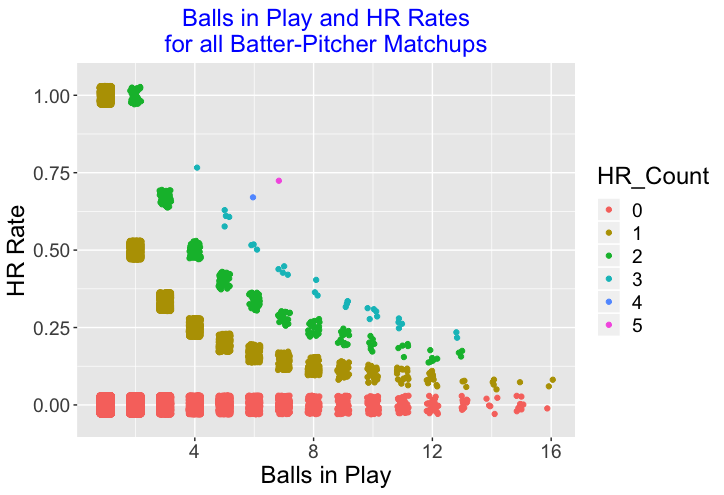
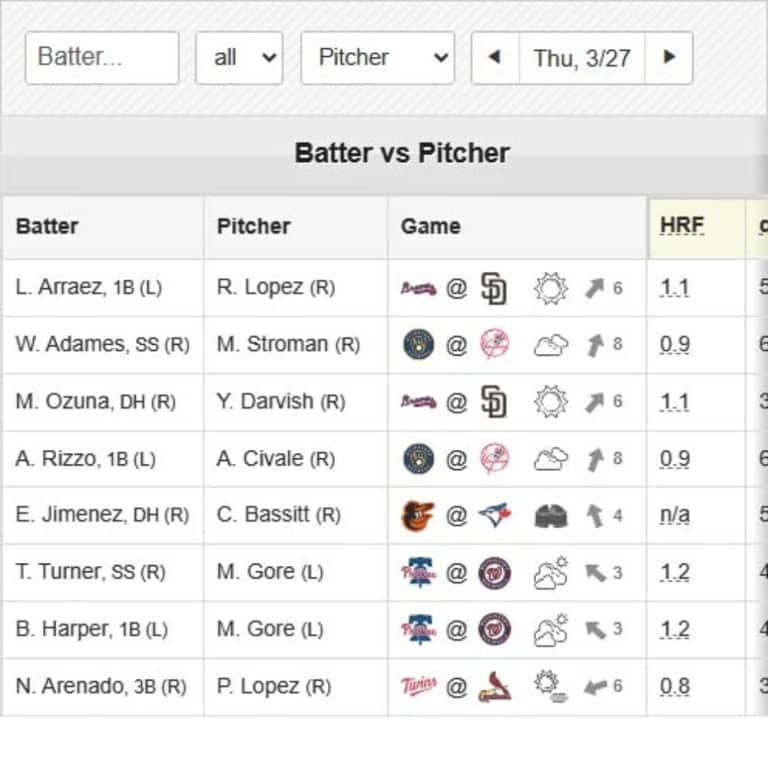
Pitcher vs batter stats aren't just about who hits well against whom. They're about small sample sizes that sound impressive until you actually look at them closely. A batter going .400 against a specific pitcher over twelve at-bats looks like an edge. It's usually noise. That's the first thing you need to understand before doing anything else with this data. The concept is straightforward on paper. You match a batter's performance history against a particular pitcher and use that to predict future outcomes. But the execution is where most people mess up. I spent years building matchup models for minor league organizations, and the number of front offices that treated raw splits as gospel is genuinely staggering. Let me walk you through how to actually do this right, not how the textbooks describe it. You start with the data source. Most teams use Statcast or Trackman data going back at least three seasons. Some still rely on older pitch-by-pitch databases that don't have spin rate or exit velocity columns. If you're working with incomplete data, your model is already behind. I'd recommend using the MLB Statcast search API or purchasing a package from a provider like Baseball Savant or Baseball Prospectus. Free data exists, but it's usually a season behind and has missing fields.
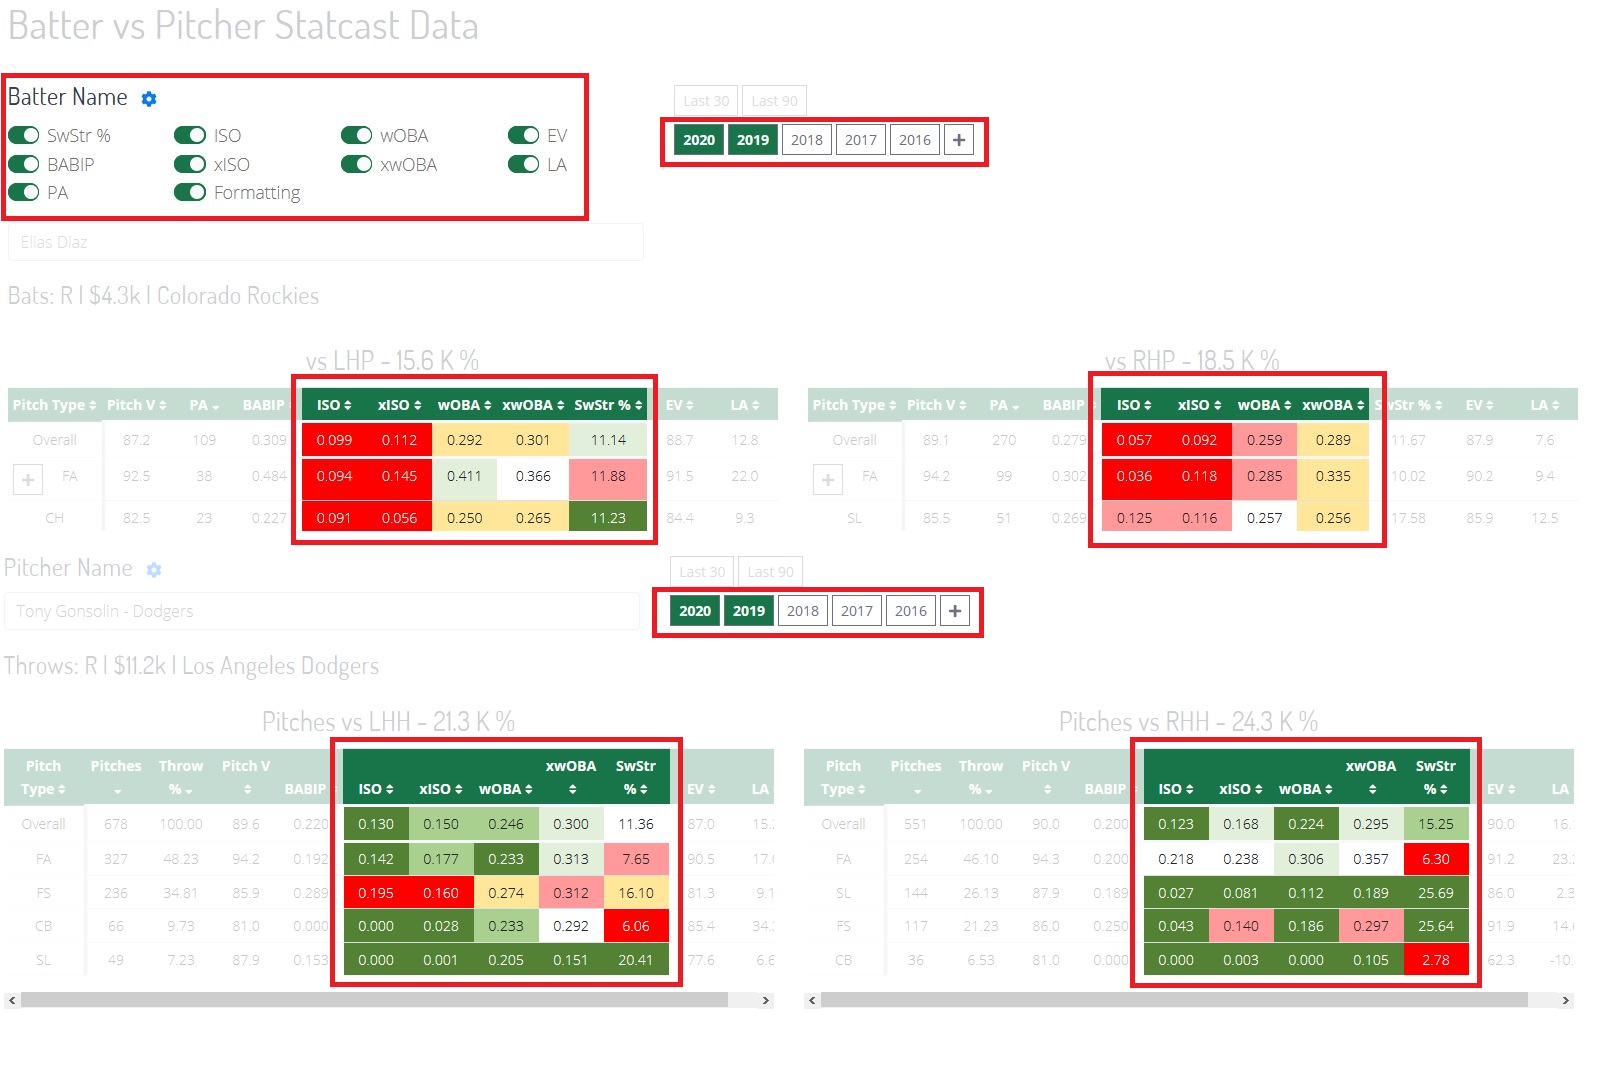
Here's the actual methodology that works. You don't just pull batting average against a pitcher. You pull expected batting average (xBA), whiff rate, contact quality, and swing-and-miss rate by pitch type. Those four metrics combined tell you something real. Batting average alone tells you almost nothing because it's heavily influenced by luck and ballpark factors. xBA strips that out by calculating what the outcome should have been based on exit velocity and launch angle. It's far more predictive than raw average. I remember one specific situation that made me completely rethink how I used to approach this. We had a third baseman who was historically destroying a particular reliever's curveball. The splits showed a .520 weighted on-base average with a 42 percent hard-hit rate on that pitch. Our scouting department wanted him to bunt less and attack those pitches. But when I dug into the actual pitch locations, I found that every one of those hits came on curveballs in the lower half of the zone, specifically above the knees and below the belt. The pitcher had since developed a slider with eight more inches of horizontal break. The old curveball splits were completely irrelevant. I pushed back on the scouting department's recommendation, and honestly, it wasn't a popular position to take. But the data backed me up, and we adjusted the approach. The batter went 1-for-4 against that same pitcher two weeks later, and three of those four at-bats were on sliders, not curveballs. The historical split was useless. The pitch type evolution made it obsolete. That's the core problem with matchup data: it's static and the sport isn't. Pitchers develop new pitches. Batters adjust their approaches. A split from two years ago has maybe a sixty-four percent correlation with this year's actual outcomes. By year three, you're mostly looking at yesterday's news. I typically weight the most recent season at forty percent, the previous season at thirty percent, and anything older than that at the remaining thirty percent, but only if the player hasn't made any mechanical changes. If a pitcher added a new pitch in the offseason, you essentially reset the weighting to zero for that pitch type and treat it as a fresh sample.
There's a counter-intuitive insight that most people miss. Opponent batting average on balls in play (BABIP) is actually more stable across seasons than most other metrics when you're looking at pitcher versus batter matchups specifically. This is because BABIP is driven by a combination of hit trajectory quality and defensive positioning, which don't fluctuate as wildly as strikeout rates or walk rates. When I see someone using BABIP swings from a pitcher's history against a specific batter, I usually trust that more than the K-rate. A pitcher who's allowed a .340 BABIP to a left-handed batter over the last two seasons while maintaining a consistent ground ball rate is likely to repeat that trend. A pitcher with a 35 percent strikeout rate against that same batter one year and eight percent the next is unreliable no matter how clean the surface numbers look. Another thing nobody talks about enough is platoon advantage decay. The lefty-versus-righty split is real, but it diminishes quickly as the pitcher faces the same batter multiple times through the order. On first exposure, the platoon split might be worth thirty to forty runs of expected value over a full season. By the third time through the lineup, that split is basically gone. I've seen analysts build models that apply full platoon adjustments even for fourth-at-bats in a game. That's incorrect. The adjustment should shrink by roughly twenty-five percent per additional at-bat against the same pitcher. It's a small correction, but over sixty games, it adds up to meaningful differences in projected win probability. Let me also be blunt about what this can't do. Pitcher versus batter stats will not help you predict whether a batter will succeed in a single at-bat. The variance is too high. Even with all the advanced metrics, the best you can do is estimate a range of likely outcomes across many at-bats. If you're using this to make single-game lineup decisions, you're probably overconfident. I've watched managers lose jobs for playing the matchup too hard. The 2019 Astros, for example, got criticized for excessive platoon usage, but the underlying data actually supported most of those decisions. The criticism came from people who didn't account for sample size and bullpen fatigue. The right approach is to use matchup data as one input among many, not as the primary decision driver.
Get the Full Details
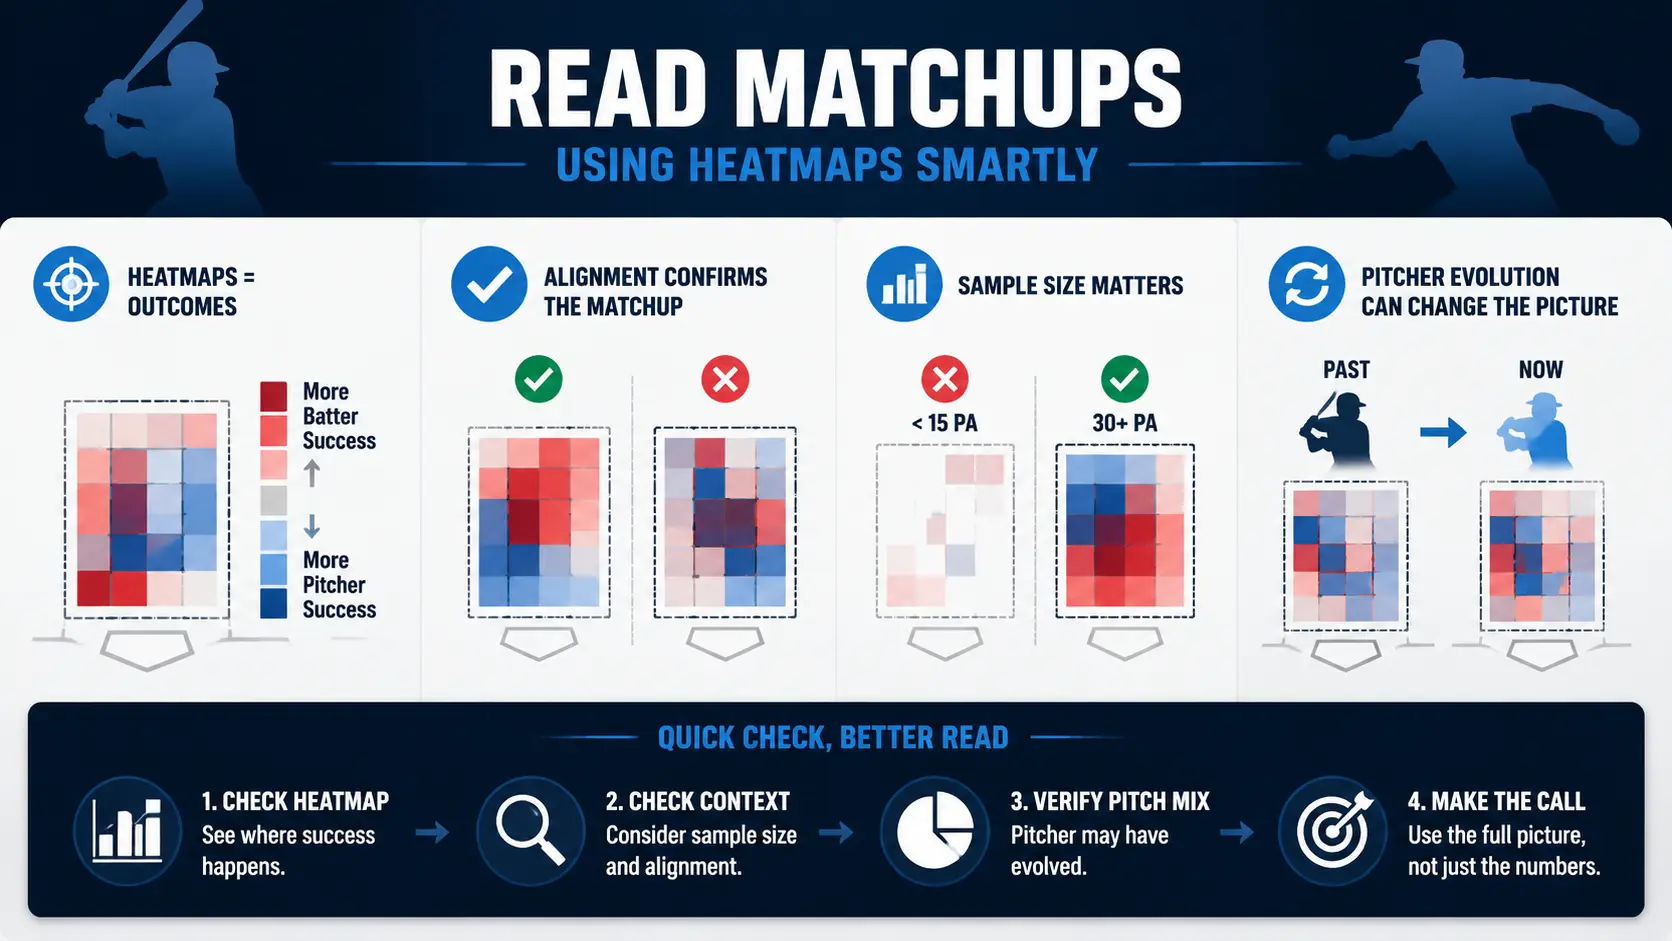
For practical implementation, here's what I'd suggest. Start with a clean dataset. Download the pitch-by-pitch data from the previous three seasons. Filter for only regular season games. Remove postseason data because the sample sizes are too small and the competitive dynamics are different. Create a matchup matrix that cross-references every batter against every pitcher they've faced, with columns for xBA, whiff rate by pitch type, chase rate, and barrel rate. Then apply your weighting scheme based on recency and pitch repertoire changes. Run simulations with Monte Carlo methods to get probability distributions rather than point estimates. A batter with a predicted .280 xBA against a pitcher is quite different from a batter with a .280 xBA whose distribution has a standard deviation of fifty points versus one with a standard deviation of fifteen points. The latter is a much safer play. Tools to use. If you're serious about this, stop trying to build everything from scratch in Excel. Get comfortable with Python or R. The pybaseball library in Python makes pulling Statcast data trivial. The Statshi package is also solid. For visualization, plot the matchup matrix as a heatmap where color intensity represents the strength of the platoon advantage. It's surprisingly effective at spotting patterns that tables hide. I once spotted a reliever who was vulnerable to left-handed batters who pulled the ball to the opposite field, and that wasn't obvious from any traditional stat line. The heatmap showed it immediately. The biggest mistake I see is treating all pitchers the same. Starting pitchers and relievers require completely different analytical frameworks. A starter faces a batter once or twice per game, which means the platoon advantage is fully intact. A reliever might face three batters from different sides in a single inning, and the matchup dynamic shifts dramatically. I've seen models applied uniformly across both roles and produce garbage results. Segment your data. Build separate models for starters and relievers. The sample sizes are different, the pitch selections are different, and the strategic context is different.
One more edge case worth mentioning. Spring training data should never be included in your model. The competitive intensity is different, the pitch counts are managed, and players are often testing new pitches or approaches. I've watched analysts pull spring splits into their models and wonder why the predictions were off. It's not a subtle error. It's a massive one. Treat spring training as a separate dataset entirely, and only use it for qualitative notes about repertoire changes, not quantitative projections. Here's the honest bottom line. Pitcher versus batter stats are useful when used correctly, and they're dangerous when used incorrectly. The difference between correct and incorrect usually comes down to sample size awareness and an understanding of what the metrics actually measure. Most people skip that part and go straight to the numbers. Don't be most people. Build your model slowly, validate it against out-of-sample data, and always keep in mind that any single at-bat is ultimately unpredictable no matter how sophisticated your analysis is. The value isn't in predicting the outcome of one plate appearance. It's in identifying small, repeatable edges across a season and making decisions that stack the probabilities in your favor.