What POGIL Actually Does in the Phylogenetics Classroom
POGIL is Process-Oriented Guided-Inquiry Learning. It's not a curriculum. It's a structure where students work in small groups through a series of questions designed to lead them to construct knowledge rather than receive it. When applied to phylogenetic trees, the activity typically gives students datasets—morphological traits, DNA sequences, or both—and asks them to build, interpret, and critique evolutionary trees through guided questions. I've run these labs for years now. The material itself is straightforward, but getting students past the surface-level mistakes takes deliberate design. Most introductory biology courses still teach cladistics as if it were just coloring in boxes. POGIL forces the misconception out into the open because the guided inquiry format makes every inference a visible step.
Phylogenetic Trees Pogil Decoding Evolutionary History Through Guided Inquiry
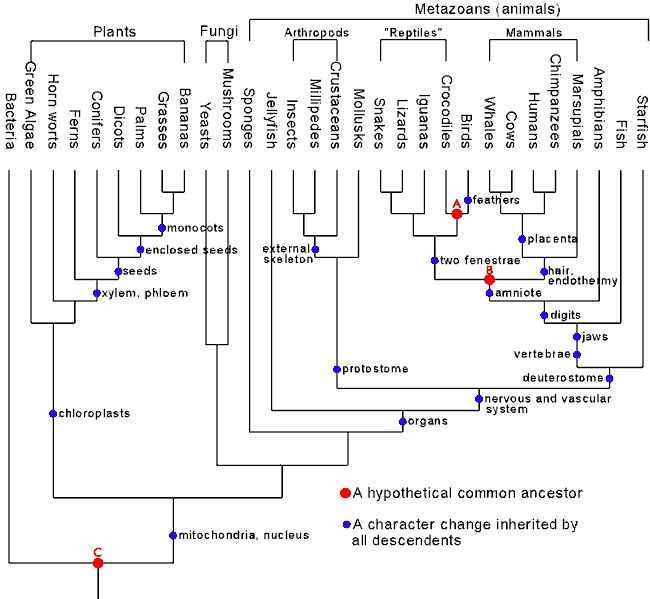
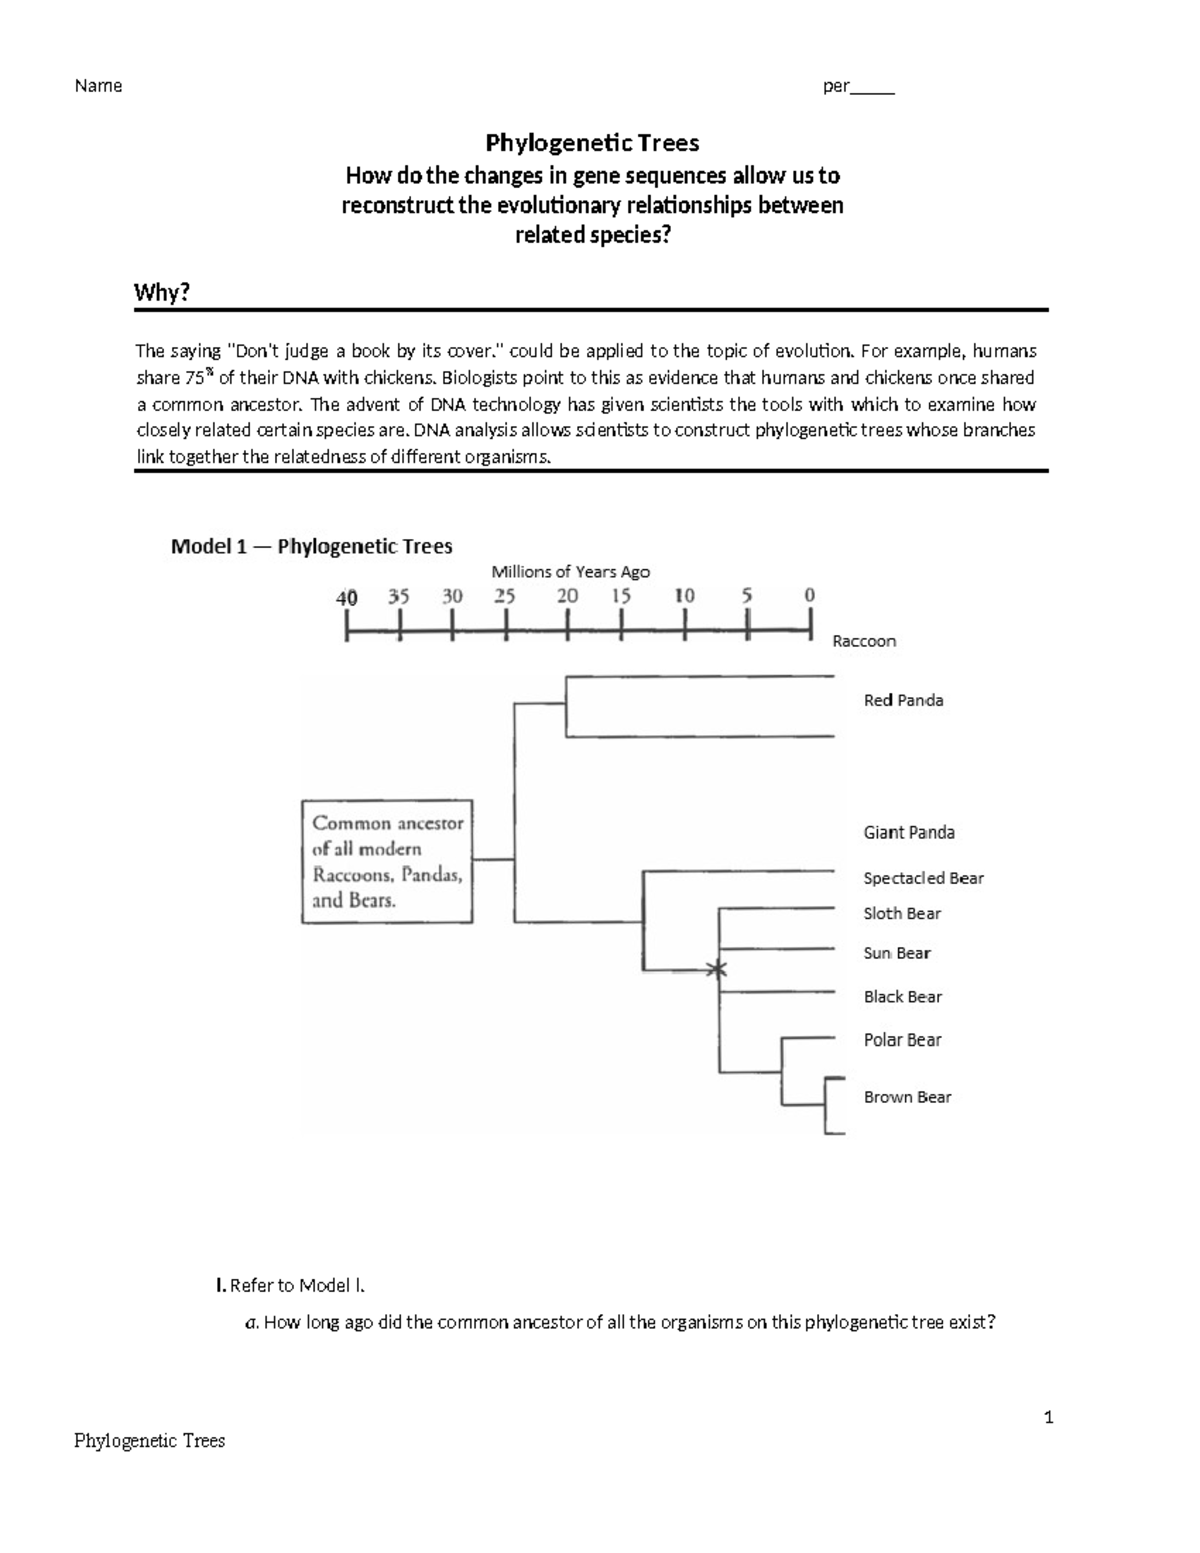
That full title you'll see floating around course packs and institutional repositories describes a specific POGIL module for teaching tree-building. The actual resource usually consists of a student handout with four to six sections, a set of background readings or data tables, and a facilitator guide with answer keys and common student misconceptions flagged. Some versions come with pre-made character matrices. Others expect your class to extract characters from provided sequence alignments or specimen images. I found a version a while back that used a cytochrome c amino acid alignment across twelve species. The question set walks students through building a character matrix, identifying shared derived characters, and then constructing a parsimonious tree. The tricky part isn't the mechanics. It's that the activity assumes students already understand what a synapomorphy is versus a symplesiomorphy. If they don't, the whole thing collapses into guesswork within twenty minutes. One practical problem I ran into repeatedly: students conflate branch length with time or with degree of difference. The standard POGIL tree diagrams are cladograms, which by definition show topology only, not branch proportions. I had a group last semester insist their tree was wrong because the branches looked uneven. We spent twelve minutes untangling that before moving forward. Now I start the session by explicitly stating whether they are building a cladogram or a phylogram, and I make sure the instructor materials specify the difference. That alone saves roughly fifteen minutes per class period.
The guided inquiry structure works like this. Section one presents raw data. Students answer basic descriptive questions about it. Section two introduces the concept of outgroups. They apply it. Section three moves into character optimization. By section four they're evaluating alternative tree topologies and arguing about which is most parsimonious. The questions are sequenced so each answer becomes a prerequisite for the next. That sequencing is the whole point. It prevents the common shortcut where students flip to the answer key and try to reverse-engineer the logic.
Get the Full Details
How to Actually Use This in a Lab Setting
Assign the handout before class if you can. POGIL activities take longer when students encounter the data format cold. Give them ten minutes to read the background material and skim the dataset. Then they get twenty-five to thirty minutes in groups of three or four during the session. Group roles matter. I assign a manager, a recorder, a skeptic, and a reporter. The skeptic role is the one most people skip. It's also the most valuable. Someone has to challenge the assumption that the most obvious grouping is the correct one. When students hit the section on choosing an outgroup, watch for two consistent errors. First, they pick the outgroup based on perceived simplicity rather than phylogenetic position. Second, they root the tree incorrectly by placing the outgroup inside the ingroup cluster instead of on the basal branch. I correct this by having them state explicitly why the outgroup shares an ancestor with the ingroup but diverged before the most recent common ancestor of the ingroup taxa. Getting them to write that sentence down catches about half the errors before they build anything. For the parsimony calculation step, I recommend having groups use a simple manual counting method first. Don't jump straight to a program. The educational value is in seeing how each character change maps onto the branches. Once they've done it by hand for maybe three characters across two alternative trees, introduce PAUP*, Mesquite, or even the free web tool FigTree for visualization. The hand-built exercise takes about eighteen minutes. The software demonstration takes another ten. Together they beat a lecture on cladistics every time.
There is a version of this activity that uses morphological data from museum specimens or high-resolution photographs. That approach works well in departments without sequencing infrastructure. The trade-off is that morphological datasets introduce homoplasy much more frequently than molecular ones, and the guided questions sometimes don't push students hard enough on convergent evolution. I've seen groups confidently group two species together based on a shared trait that turned out to be analogous, not homologous. The activity doesn't always flag that clearly. When that happens, I pause the class and walk through a known example of convergence, like the flippers of penguins and dolphins, to illustrate why the character selection matters more than the matrix formatting.
Pitfalls That Will Waste Your Time
Students will treat the tree as a ladder of progress. This is the oldest mistake in the book. No amount of POGIL scaffolding eliminates it entirely. You still need to intervene directly. Point at a terminal node and ask where the "most evolved" organism is. Let them struggle with the fact that the question is malformed. That discomfort is the learning moment. Another issue: the handouts sometimes provide simplified datasets that produce unambiguous results. Real data doesn't work that way. When all the characters support a single topology, students leave convinced that tree-building is deterministic. It usually isn't. I supplement the POGIL activity with a second dataset that contains conflicting signal. Even five characters with homoplasy are enough to show that different analytical methods can yield different trees from the same organisms. It takes an extra twenty minutes to set up, but it prevents the misconception from hardening. If you're assigning this as homework rather than in class, it loses most of its effectiveness. The group dynamic is where the guided inquiry does its work. Students defend their reasoning to peers. That peer confrontation is what replaces the lecture. Without it, you're just handing them a worksheet and hoping they read the background material. They won't.

Where This Approach Falls Short
POGIL works well for teaching the logic of tree construction and the vocabulary of phylogenetics. It is not a substitute for hands-on experience with actual phylogenetic software. The activities rarely cover bootstrapping, model selection, or Bayesian inference. Students finish the module understanding cladistic reasoning but unable to evaluate whether their tree is statistically supported. That gap matters if they move into upper-level courses or research. The time requirement is also a constraint. A complete phylogenetic POGIL cycle runs forty-five to sixty minutes in a well-run section. In a packed lab with twenty-five groups, expect closer to seventy. If your course schedule doesn't allow that window, you'll either have to compress the activity or accept that the later sections get rushed. I've tried splitting it across two meetings. That actually works better for retention, but it requires the second session to pick up exactly where the first left off, which means coordinating with the TAs or any substitute instructors. For advanced undergraduates or graduate students, this activity is too basic. The datasets are artificial, the questions lead to predetermined answers, and there's no exposure to real-world ambiguity. Those students benefit more from working with actual sequence data through tools like MEGA, IQ-TREE, or RAxMP. The POGIL framework can be adapted for that purpose, but the standard published modules aren't built for that level.
Getting the Material
Phylogenetic trees POGIL materials circulate through several channels. The POGIL Consortium maintains a repository of validated activities. Many institutions host them on their learning management systems for enrolled students. You'll also find versions posted on academic blogs, departmental websites, and course-sharing platforms. The most reliable source is usually the publisher's accompanying resource site if the activity appears in a textbook like Campbell Biology or Freeman's Biological Science, since those editions include the handouts as supplemental materials. If you're an instructor looking to adopt one, check the facilitator guide first. The quality of the guiding questions varies between versions. Some are well-sequenced. Others skip from character coding directly to tree interpretation without the intermediate reasoning steps that make the activity work. The presence of answer explanations and anticipated misconceptions in the guide is a decent proxy for overall quality. If the guide is thin, the student handout probably is too. The activity I described using the cytochrome c alignment was shared openly by a biology education researcher a few years ago. It's widely copied with minor modifications. The core structure is stable across versions: data presentation, outgroup identification, character optimization, tree construction, and interpretation. Any competent version will hit those beats. The differences show up in how carefully the questions force students to confront their own assumptions about homology and how explicitly they address common errors before those errors propagate into the final tree.