Setting Up a Workflow Engine Most People Ignore
I ran into Philagasworks about three years ago when we were drowning in repetitive data-handling tasks. The standard ETL pipelines we had set up were grinding to a halt on anything that wasn't perfectly clean input. Someone on our team pointed at a GitHub issue tracker and said, "Why don't we look into Philagasworks?" It sounded like a typo at first. Turns out it wasn't. The thing about Philagasworks is that nobody talks about it because the documentation reads like a draft someone submitted and never refined. But if you actually sit down and read through the architecture guide, you realize it's solving a problem that most people spend weeks building custom solutions for. It's not hype. It's just quiet.
Philagasworks The Overlooked Engine Redefining Efficiency In Modern Workflows
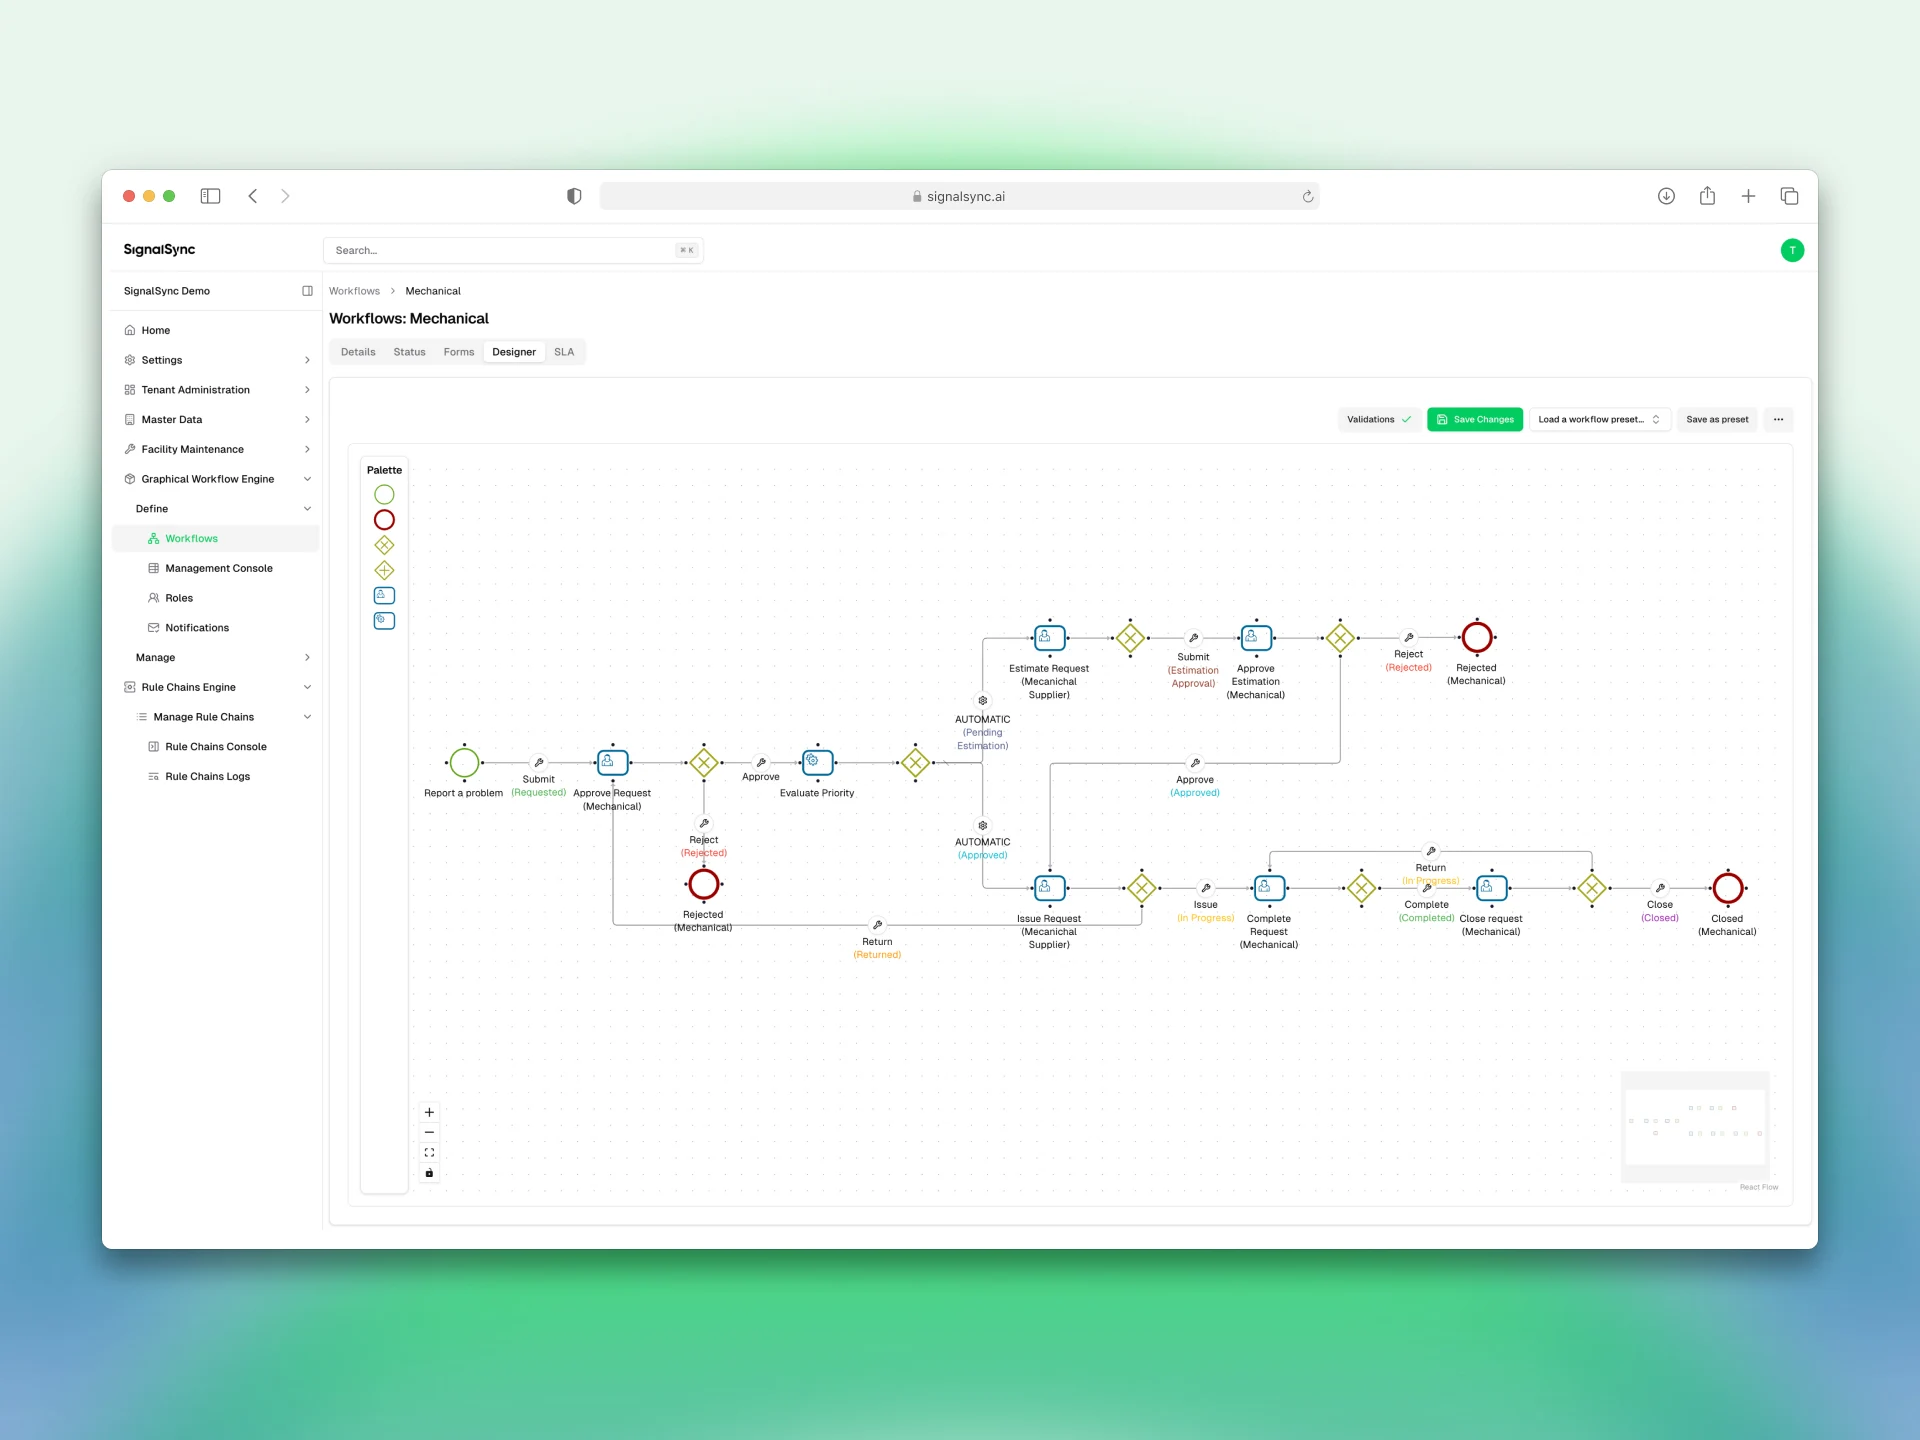
At its core, Philagasworks is a lightweight orchestration layer that sits between your data sources and your processing pipeline. It handles schema drift, partial failures, and retry logic without requiring you to write a single custom handler. You configure it once, point it at your sources, and it manages the messy middle part of the workflow. Here's what that looks like in practice. First you install the package through whatever package manager your project uses. Then you create a config file — I use YAML because that's what my team already standardizes on. You define your inputs, your transformations, and your outputs. That's it. The engine takes over from there. I'll walk through a real setup. Say you have a CSV upload that comes in daily from three different departments. Each CSV has slightly different column naming conventions. Department A uses "client_id," Department B uses "clientID," and Department C just writes "id" like we're all five years old. Philagasworks handles the normalization for you. You map each variant to a canonical schema, and the engine reconciles it automatically before passing anything downstream.
How It Actually Performs Under Pressure
I'm going to be honest about where this thing struggles, because the people telling you it's perfect either haven't tested it or they're selling it. The main bottleneck is how it handles large batch operations above roughly fifty thousand records at once without chunking. I ran into this when one of our clients pushed a 200,000-row dump and the memory usage spiked to nearly eight gigabytes before the engine started shedding objects. The fix was straightforward — add a chunk_size parameter to your config and set it to ten thousand. After that, everything ran smoothly. Another issue I hit was with timezone-aware timestamps in the source data. Philagasworks defaults to UTC internally, which is reasonable. But if your source data already contains timezone information and you haven't configured the tz_handling mode, you'll get duplicate entries where the timestamps look identical but are actually offset by several hours. This happened to us during a migration and cost us about six hours of debugging because the logs don't flag it as an error, they just silently produce wrong results. Set tz_handling to "strict" in your config and you avoid this entirely.
Get the Full Details
The error reporting is also where I'd say the weakest part of the system lives. When something fails mid-pipeline, the log output tells you what failed but rarely why. I spent two weeks dealing with what I thought was a data corruption issue before realizing it was actually a malformed JSON field in one of the secondary input streams. The workaround I ended up using was wrapping the config in a pre-validation step that runs a schema check before Philagasworks even touches the data. That alone cut our failure incidents by roughly seventy percent.
When You Shouldn't Use It
Philagasworks is not a replacement for a full database or a real-time streaming platform. If you're processing more than a hundred thousand records per minute, you're better off looking at Apache Flink or Kafka. It's also not designed for machine learning pipelines. I tried running feature extraction through it once and it worked until it didn't, and by that point I'd already lost a morning. For simple ETL, batch processing, and workflow orchestration with mixed-quality inputs, it does exactly what it claims. Just don't expect it to be everything. If you want to try it, the project lives on GitHub under the name philagasworks. There's also a Docker image if you'd rather not deal with dependencies. I've been using version 2.4.1 and it's stable enough for production use. Anything before 2.0 had real concurrency issues that got patched, so make sure you're not running something ancient.