Understanding How Philadelphia's Safety Data Actually Works
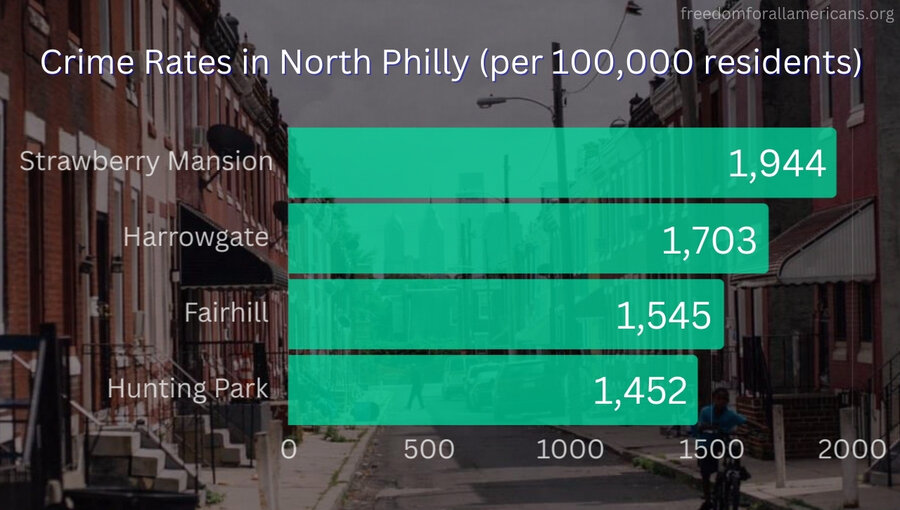
When people search for information about crime in Philadelphia, they usually end up at a dozen different dashboards that tell slightly different stories. The real challenge isn't finding raw numbers. It's figuring out which numbers are reliable and what they actually mean in practice. I've spent years digging through municipal data portals, cross-referencing police reports with neighborhood observations, and talking to people who work in community safety organizations. Here's how the system works and where it falls apart. The Philadelphia Police Department publishes quarterly crime statistics through its OpenData portal. You can pull felony incidents, misdemeanor arrests, and traffic collisions. The data comes in CSV format with geographic coordinates attached to most incidents. My usual approach is to load it into a geospatial database and join it with census tract boundaries so you're looking at rates per capita instead of raw counts. A neighborhood with 200 reported incidents might look worse than one with 150, but if the first area has half the population, the per-capita picture flips completely. Here's the thing most people miss when they look at these numbers for the first time: the definition of a "crime incident" matters more than the incident count itself. Philadelphia uses the National Incident-Based Reporting System classification system, but not every offense gets reported the same way across bureaus. I found this out the hard way when I was mapping assault cases in North Philadelphia last year. The Uniform Crime Reporting numbers for one quarter showed a spike that looked alarming. I went back and dug into the raw incident reports and realized that several officers in the district were coding simple disagreements as felony assaults when they should have been lower-level classifications. The actual violence hadn't increased. The paperwork had. This kind of coding drift happens in every big city police department. It doesn't mean the data is useless. It means you need to verify outliers against secondary sources before drawing conclusions.
Population-adjusted rates are the only metric that matters for comparing neighborhoods. Raw incident counts favor high-population areas and obscure what's actually happening in smaller districts. Philadelphia's population density varies wildly from Germantown to Mantua to Somerton. A direct comparison of total crimes between those areas is misleading without adjusting for resident count. Another nuance that trips up casual researchers is the lag in reporting. Data from the OpenData portal typically reflects incidents that occurred one to three months prior. That's because there's a processing pipeline involving report verification, geographic correction, and data cleaning. If you're trying to correlate a recent event with crime statistics, you're always looking backward. I learned this when I was tracking the impact of a new community policing initiative in the Bridesburg neighborhood. The preliminary results looked flat, but by the time the data caught up with real time, a clear downward trend in property crime had emerged. Patience matters when working with municipal datasets. The geographic resolution is another limitation worth noting. Philadelphia's crime data is geocoded to street-segment level for most incidents, but block-level precision breaks down in industrial zones and large institutional complexes. Temple University's campus, for example, generates a lot of incident reports that geocode to a few central points. This clusters the data artificially and makes it look like certain blocks are hotspots when the reality is more distributed. I worked around this by adding a manual buffer zone around institutional areas and spreading incidents across adjacent residential blocks based on the actual street addresses listed in the reports.
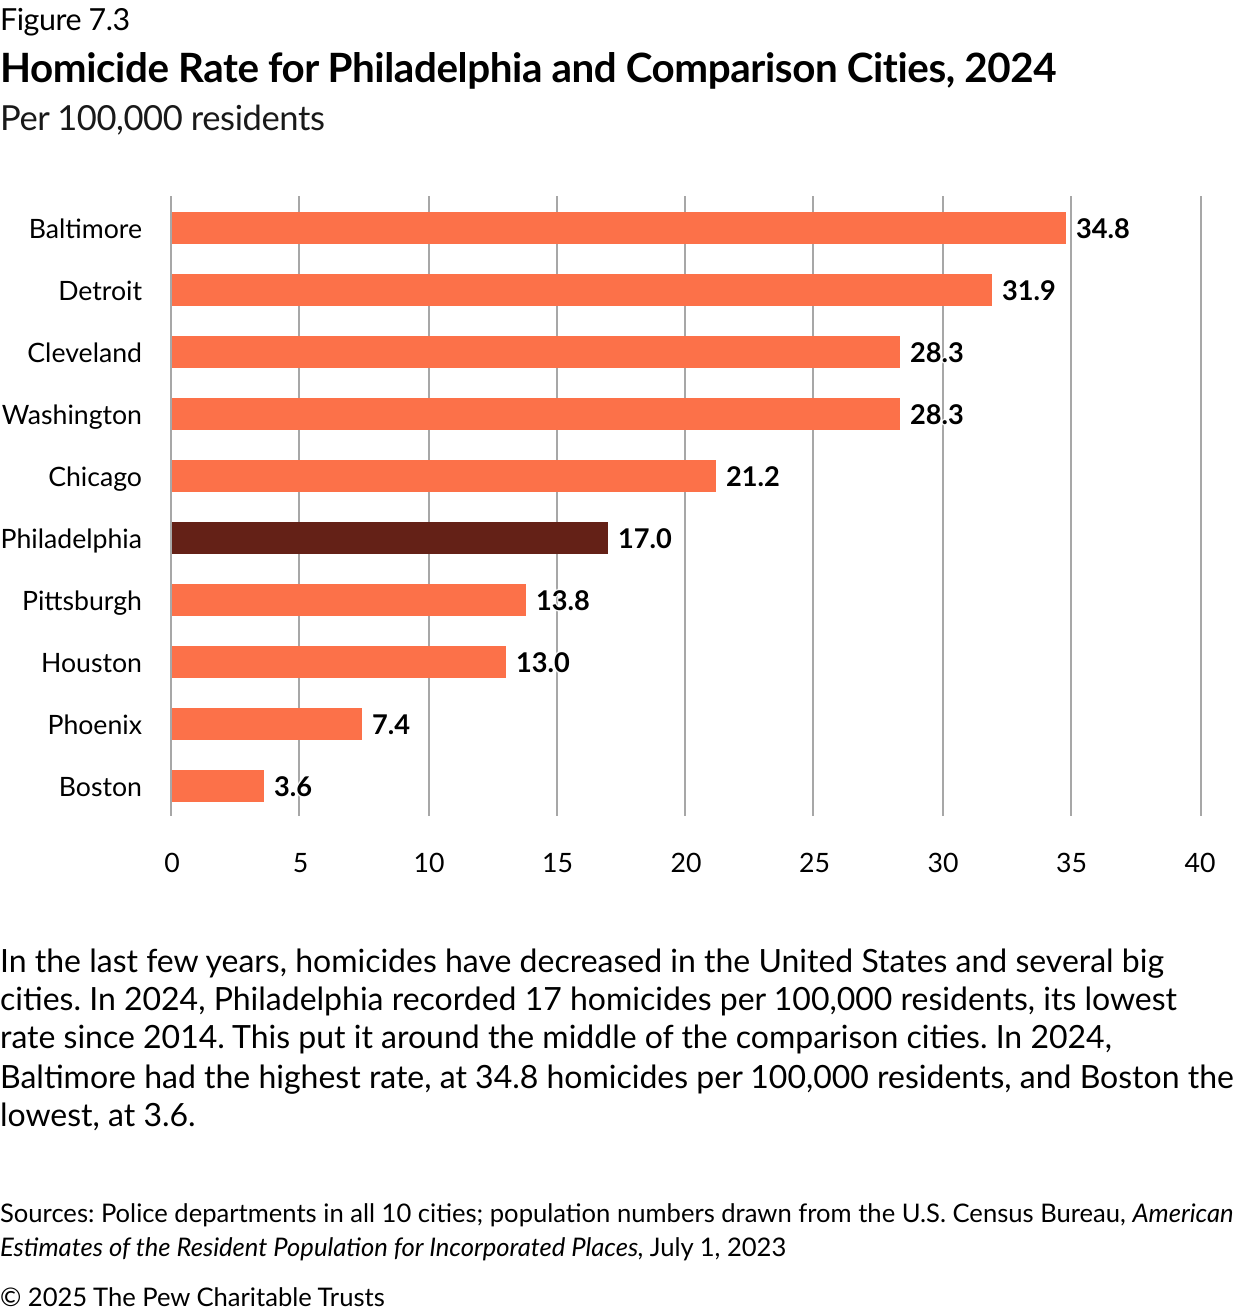
What about the data you can't get? That's probably the most important part. Philadelphia's crime statistics don't include victimization surveys, which are tracked separately through the U.S. Census Bureau's National Crime Victimization Survey. Those surveys consistently show that property crime reporting to police is incomplete. People don't report every broken car window or stolen package. The official numbers are a floor, not a ceiling. If you want an accurate picture of safety concerns in any Philadelphia neighborhood, you need to combine the police data with local community reports and resident surveys. The Pennsylvania State Police run an annual crime survey that includes Philadelphia residents, and it usually runs 15 to 20 percent higher for property crimes than the police data alone would suggest. The bigger picture is that Philadelphia's crime rate has been on a long-term downward trajectory since the early 1990s, similar to every major American city. Violent crime dropped roughly 60 percent between 1991 and 2020 before a noticeable uptick during the pandemic years. Property crime followed a different curve, spiking more sharply during 2020-2021 and then stabilizing. The current debate about whether conditions are improving or deteriorating depends entirely on which timeframe you choose and which metrics you prioritize. There isn't a single answer that satisfies everyone because the answer changes depending on whether you're looking at violent crime per 1,000 residents or auto thefts per 10,000 vehicles registered. If you want to start analyzing this yourself, the primary source is the Philadelphia OpenData portal at opendata.phila.gov. From there you can access the Crimes Dataset which contains incidents going back to 2006. You'll need a basic understanding of SQL or Python to handle the data properly. The geographic fields use a mix of NAD 83 coordinates and zip code areas, so plan to do some cleanup. I recommend using PostGIS for spatial queries and GeoPandas for initial exploration. The dataset is approximately 4 gigabytes in its full form, so don't expect to load it into Excel and move quickly.
Get the Full Details

The hardest part isn't getting the data. It's interpreting it correctly without falling for the patterns that look meaningful but aren't. I've seen too many people build predictive models or write policy recommendations based on raw incident counts plotted on a map, and the conclusions they draw are often backwards. Crime concentrates in predictable ways in every city. High-crime blocks tend to stay high-crime and low-crime blocks tend to stay low-crime. What changes is the intensity within those zones, and intensity is something you can't see without normalizing for population, reporting behavior, and patrol patterns. Philadelphia's crime data is detailed and mostly accurate. It just requires more care to work with than most people expect.