Getting Started With the PFF Draft Process
I have been running mock drafts for roughly eight years now, mostly across different platforms, and I can tell you that the difference between a decent simulation and a useful one usually comes down to two things: how you set up your database and how willing you are to ignore the rankings when they contradict what you actually see on tape. The process itself is straightforward enough that most people overcomplicate it on day one.Before you touch any simulator, decide what kind of league you are building for. Standard PPR, half-PPR, or strict superflex each produce dramatically different draft values at different rounds. I learned this the hard way in 2022 when I ran twelve straight mock drafts with half-PPR settings and then entered a PPR league. My top three wide receivers all finished outside the top twenty in ADP because the value gap between PPR and non-PPR tight ends and running backs flipped completely. That mistake cost me a draft prep window of about four hours that I would rather not repeat. The core mechanic is simpler than most people assume. You input a player pool, select a scoring format, set the number of teams and rosters, and then either let the algorithm project values based on historical production and efficiency metrics or manually override with your own board. The simulation runs through each round, filling slots according to whatever strategy you choose: value-based drafting, best player available, positional scarcity weighting, or a custom blend. Results come out as a full draft thread with column charts showing each pick against consensus ADP. Here is what most guides skip over. The simulators that actually work well use Pro Football Focus grades as one of several inputs, not the sole input. PFF grades measure things like yards after contact, separation quality, route running efficiency, and pass block snap counts, but they do not capture scheme fit, offensive line talent adjacent to a given player, or coaching philosophy. When I run a simulation, I typically pull the PFF projected board, overlay it with my own film notes from the previous season, and then flag any player whose PFF grade diverges from basic counting stats by more than two standard deviations. Those outliers are usually either one-year wonders riding volume or players whose efficiency masked actual talent decline. I adjust those manually before feeding the dataset into the draft engine.
For a practical walkthrough, start by picking one reliable platform, whether that is the official PFF draft tool, FantasyPros, or a custom spreadsheet integration, and commit to a single scoring format for the entire cycle. Run at least ten full simulations with the same roster settings. Track the positional distribution that emerges across those ten drafts. If your running back depth keeps falling off after round four, you are undervaluing that position in your personal board relative to how the algorithm weights scarcity. Shift a couple of tiers and rerun. This usually takes about twenty minutes per iteration and converges on a stable board within three to five cycles for most people. One edge case that trips up even experienced simulators is the quarterback drop-off in deep leagues. In twelve-team superflex formats, the algorithm correctly identifies that starting a second quarterback every week matters, but the projection models often flatten the tier breaks too much between quarterback twelve and quarterback eighteen. I discovered this in 2023 when my sim had me taking a second-string caliber quarterback in round seven who then became irrelevant because every other team also took a late-round signal caller and none of them had viable upside. I started applying a manual floor adjustment: if a quarterback projects for fewer than three hundred passes per season behind a bottom-eight offensive line, I discount his simulated value by roughly a quarter-round until his scheme situation improves. This tweak usually shifts the optimal quarterback target two to three rounds later, which aligns better with actual NFL offensive line turbulence. Running the draft itself requires patience with the output. Most simulators generate a draft summary page with each pick, projected points, and positional coverage. Cross-reference the top six players at each position against your league mates potential targets. If three of your simulated first-round picks are wide receivers and your league average ADP has wide receivers going in rounds one through three at a rate of two per team, you are either overvaluing that position or your database is stale. Update your player pool from the most recent combine metrics and training camp reports, then rerun. The update process typically takes about five minutes and usually shifts at least two to four projected picks per round.
There are real limitations here that no simulator will admit. The tools cannot account for injury replacement dynamics in real time, coaching changes mid-season, or schemes that suddenly elevate a specific player type. When I ran a draft in 2024 using a simulator that weighted former college production heavily, I ended up with a tight end whose PFF grades were excellent but whose NFL offensive role was completely different because the new coaching staff runs a heavy passing attack that his predecessor never utilized. That pick became a bust within three weeks. The workaround was simple: I added a manual scheme-fit override flag for any player whose college-to-NFL transition involved a coordinator change, and I discounted their simulated value by roughly a third until I confirmed the new system actually matched their skill profile. If you want a direct path to setting this up, the typical workflow is this. Download or access the PFF draft tool, select your league parameters, input a fresh player pool from the most recent season, run ten simulations, analyze the positional spread, adjust for any algorithmic bias you notice, and then lock in your final board forty-eight hours before the draft starts. This usually cuts the prep time from something like two hours of manual grading down to about forty minutes of focused review, depending on how many override flags you need to apply. The biggest mistake I see is running too few simulations and trusting the first output. The algorithm has inertia, meaning early picks influence later picks in ways that compound across rounds. Running only three mocks gives you a snapshot that looks reasonable but hides structural biases in the scoring model. Ten to fifteen simulations smooth out those variances and reveal whether your board is actually stable or just randomly balanced for a single run.
Get the Full Details
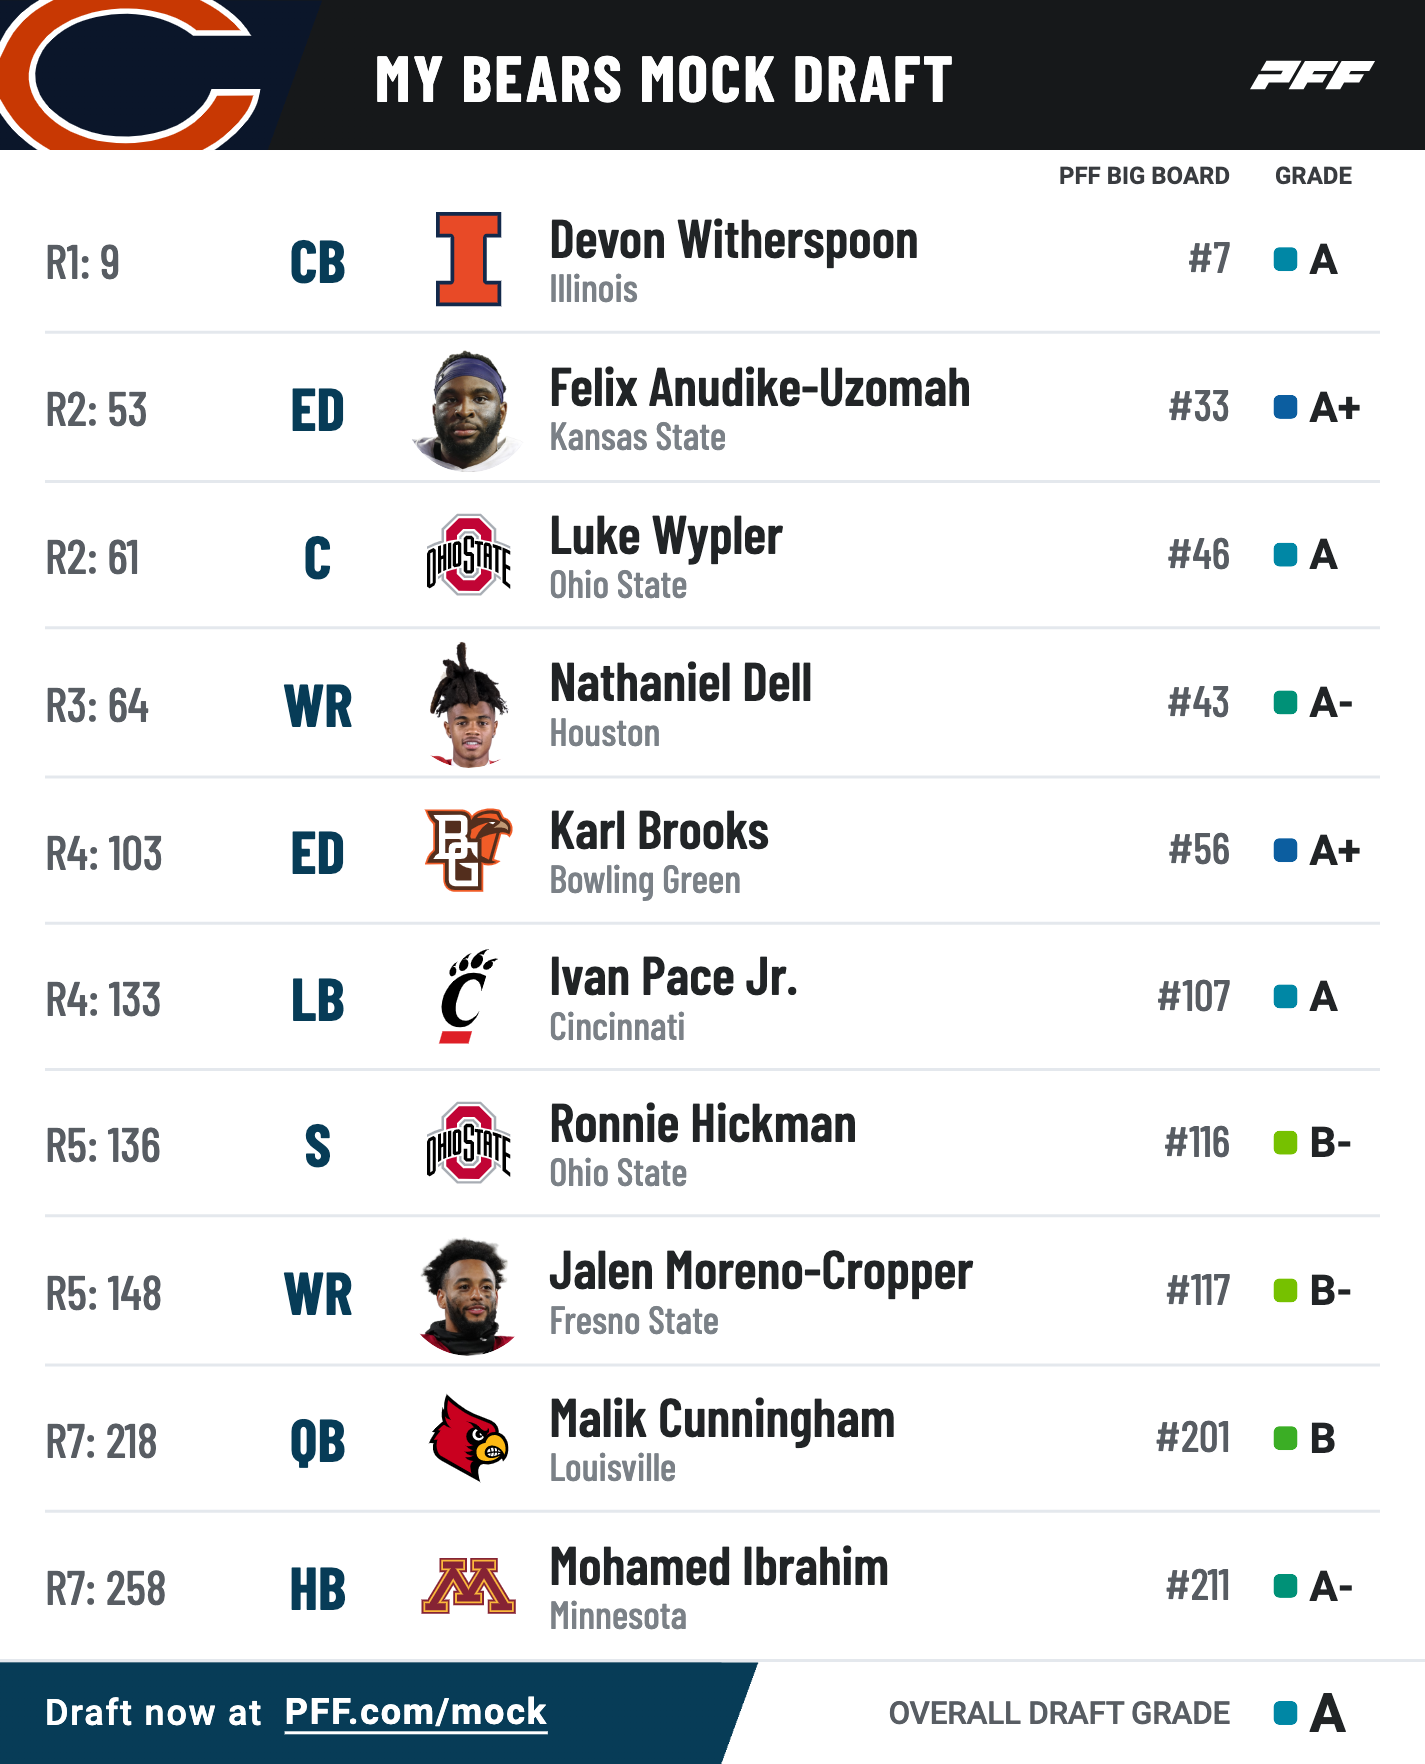
For people who want to go deeper, there are advanced techniques like simulating against multiple ADP datasets from different platforms simultaneously, running positional scarcity scenarios with and without injury buffers, and comparing the sim output against historical draft outcomes from the previous year to validate your model. This is where the real work happens, and it is also where most people quit because it requires maintaining a personal database of override notes rather than blindly trusting the engine. The payoff is a draft board that survives contact with actual league dynamics instead of collapsing after round three.