What ImageMate Actually Is
Oswego County Imagemate Transforming County Records And Public Access In The Digital Age — I've seen people get confused about this because the terminology changes depending on which office you're talking to. The county clerk's office runs a document imaging system built on ImageWare Systems' platform. That platform is what most counties call their "records management system." It scans paper documents, assigns them metadata, and makes them searchable online. The result is what the public sees as the ImageMate portal. Before this system, if you wanted to pull a deed from 1987, you drove to the clerk's office, asked for it, and waited. Sometimes minutes. Sometimes hours, sometimes days if the document was offsite. Now everything lives in a searchable database with scanned images behind each record. That's the basic transformation. The reality underneath is more complicated.
Oswego County Imagemate Transforming County Records And Public Access In The Digital Age
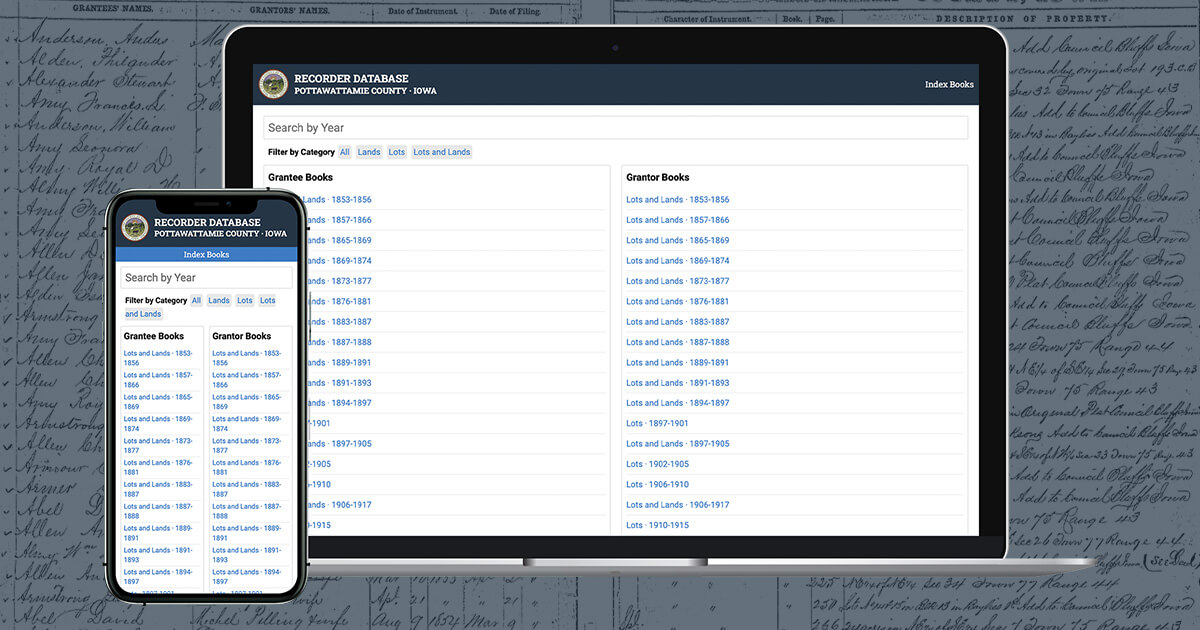
The official system handles several types of records. Deeds, mortgages, liens, satisfactions, plats, and a few other instrument types that get filed with the county clerk. Each one gets a document number, a scan, and associated metadata fields. Users access it through the county's public portal. Go to the Oswego County clerk's official website. Look for the document retrieval or image system link. It typically routes you to the ImageWare portal hosted by the county or a contracted service provider. You may need to create a free account before you can run searches. Some features require no login at all, while advanced searches and bulk requests need credentials. The exact login flow changes occasionally as the county migrates between vendors or updates the platform version. Once inside, you'll see a search interface. Standard searches let you look up by name, document number, book and page, or recording date range. The default search often prioritizes name-based queries, which works fine until it doesn't.
Search Tactics That Actually Work
Name searches are the first thing everyone tries. Type in a last name and hit search. The problem is that name searches are unreliable above a certain volume. If your target person has a common last name, you will get hundreds of results and no way to filter quickly without additional parameters. Here's what helps: add a first name initial, include a document type, and narrow the date range to something reasonable. A five-year window instead of "all time" cuts down result sets dramatically. Document number searches are cleaner. If you have a book and page reference from a prior document or a title report, enter it directly. The system resolves it immediately and takes you to the document image. This is the method I use most of the time when I'm pulling records for research or legal work. It's faster and more accurate than name searches every single time. Parcel-based searches through the GIS-linked module are useful if you're looking for all documents associated with a specific property. The county's parcel data ties into the imaging system, so you can pull up a tax map parcel and see every recorded instrument attached to it. This is genuinely helpful for due diligence. The interface for this varies depending on which module is currently active, and the county occasionally rotates between different front-end implementations.
Get the Full Details
A Problem I Ran Into and How I Got Around It
I was researching a property boundary dispute a few years back and needed to pull a deed from the early 1990s. The document number was in the system, but when I opened the image, it was blank. Not corrupted. Just blank. The OCR text was there, the metadata was correct, but the actual scanned image file was empty. I checked three times. Same result. The workaround was straightforward once I figured it out. I contacted the clerk's office directly and asked them to verify the source image on the backend. They located the actual scan on a separate storage layer and manually attached it to the record. That process took about two business days. Going forward, whenever I encounter a document with missing imagery in the system, I note the document number, file a quick inquiry through the clerk's contact form, and wait for a callback or email response. It's not elegant, but it works consistently. The county staff are responsive to these kinds of requests.
Counter-Intuitive Things Beginners Miss
First, just because a document exists in the digital system doesn't mean it's complete or accurate. The scanning process is batch-driven, and older records sometimes have indexing errors. A document might be filed under the wrong grantor name, or the book and page might be misaligned with the actual recorded sequence. Always cross-reference with the physical index if accuracy matters. I learned this the hard way when a title search came back clean digitally but the physical record showed a completely different instrument number. Second, the image quality varies enormously depending on when the document was scanned. Records digitized in the early phases of the project tend to have lower resolution and more artifacts than newer scans. Documents from before 2000 often look fuzzy. Some have handwritten annotations that OCR cannot read. This isn't a flaw in the system itself, it's a limitation of the source material and the scanning equipment available at the time. If you're relying on OCR text extracted from these images, expect errors and verify against the visual image.
What the System Doesn't Handle Well
Not everything has been digitized. Certain record types and historical periods remain on film or physical paper only. If you're looking for records prior to a certain cutoff date, the system may simply not have them. The county has been incrementally scanning older records, but it's a slow process constrained by budget and staffing. Don't assume that absence from ImageMate means the document doesn't exist. It likely means it hasn't been scanned yet. Search performance degrades during peak usage times. The county's IT infrastructure handles traffic reasonably well, but Monday mornings and the first week of the month tend to be slower. I've seen search queries take 15 to 30 seconds longer than usual during those windows. If you're doing research that requires many searches in succession, plan accordingly or spread it out across different times of day. There's also a limit to how many pages you can view or download in a single session. The system imposes session timeouts and per-request caps to manage server load. If you need a large set of documents, you'll need to break your requests into smaller batches. Bulk download capabilities exist but require special access or a formal request through the clerk's office.

Practical Tips for Getting What You Need
Keep your search parameters tight from the start. Use document numbers whenever possible. Filter by date and document type before running broad name searches. Save your search results as PDFs rather than printing individual pages. The system offers a print function, but exporting to PDF preserves the image quality better and is easier to organize later. If you're pulling multiple related documents, do it in a single session to avoid timeout resets. For legal or title work, always request a certified copy if you need something for official purposes. The online images are for reference only and are not certified. Certified copies require a separate request, usually with a fee, and may take additional processing time. I've seen people try to submit unverified printouts from the portal and get turned away at closing. Don't make that mistake. If the online system is giving you trouble or you need records that aren't showing up, call the clerk's office. The staff can look up records that the public portal can't surface, often because those records require internal index lookups or have restricted access for privacy reasons. A phone call saves what would otherwise be an hour of wasted searching.