Automated Passenger Processing at Japanese Airports: What Actually Works
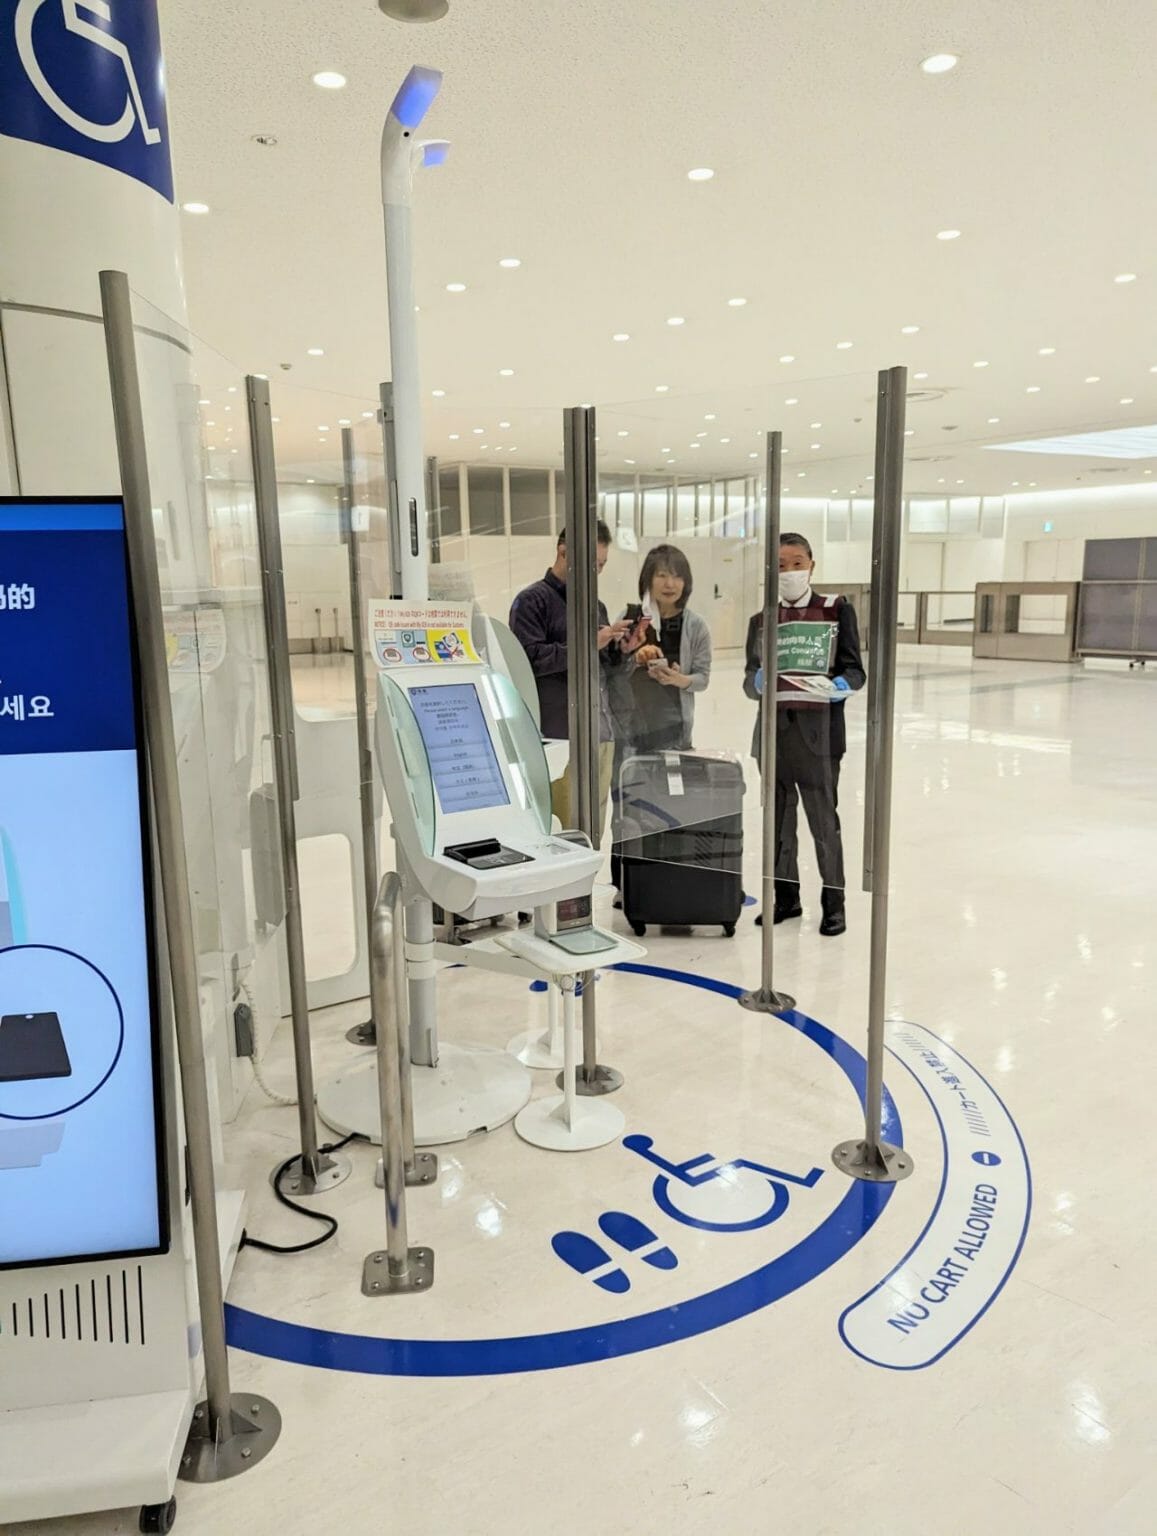
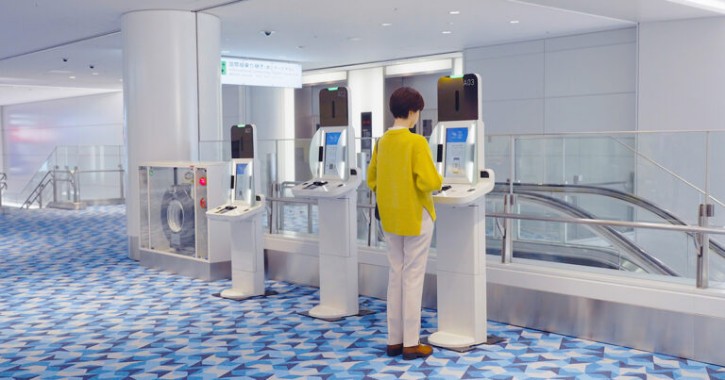
When the Japanese Ministry of Land, Infrastructure, Transport and Tourism rolled out their automated gate systems across major airports, most travelers noticed the hardware but rarely understood what was happening behind the scenes. The optical character image recognition layer that reads your passport, cross-references it with immigration databases, and clears you for boarding is a complicated stack. I've spent the last few years dealing with the integration side of these systems at Narita and Kansai, and honestly, it's less magical than the marketing makes it look. The core technology here combines OCR pipelines with biometric matching and real-time API calls to immigration servers. The workflow runs like this: your passport goes into the reader, the image gets pre-processed through a series of contrast and alignment steps, the MRZ zone gets decoded, and then the system either flags the document for manual review or auto-approves it within roughly three seconds. Most people breeze through without thinking about it. That's the goal anyway. I ran into a real problem last winter when we were stress-testing the OCR module at an older Narita terminal. The lighting in Booth 14 was inconsistent because a nearby window let in direct afternoon sun that washed out the passport photos during certain hours. The system would reject about 18% of documents during the 1pm to 4pm window. We tried adjusting exposure settings in the software, but that just made the MRZ zone harder to read. The actual fix was putting up a matte black shade over the document reader tray and recalibrating the white balance specifically for that booth's ambient light profile. It sounds obvious now, but it took us six weeks and two firmware updates to land on that solution.
How the Processing Pipeline Actually Works
Below is what happens when you place your passport on the reader. The system captures multiple image layers simultaneously: the document photo, the MRZ code, and the machine-readable barcode if one exists. Each layer goes through its own validation path. The MRZ check uses checksum validation on the nine-digit identifier. The photo match runs a facial recognition against the embedded chip data. If both pass, you get a green light. If either one hesitates, the system escalates to a human operator. The part nobody talks about is the confidence scoring. Each validation step returns a numerical score between zero and one. The threshold for auto-approval isn't fixed — it shifts based on risk parameters set by immigration authorities. During heightened security periods, that threshold moves up and more legitimate passengers get flagged for secondary screening. I've seen it happen. You'll notice the wait times double even though nothing visually changed about the process.
What Beginners Get Wrong About These Systems
Most people setting up or troubleshooting these OCR systems focus on the image quality and miss the network latency component. The passport reader itself is fast. What slows things down is the round-trip time to the immigration database. If your API endpoint is pinging a server in Tokyo from a regional airport with a congested uplink, you're looking at eight to twelve second delays per passenger. That adds up fast during peak hours. The fix isn't better cameras. It's local caching of common reference data and pre-emptive session keep-alives to the backend service. Another thing that catches teams off guard: the MRZ font standard isn't universal across all countries. Some passports use a variant that the default OCR engine misreads as similar characters. I've seen T confused with seven, G confused with C. The workaround is feeding country-specific font profiles into the recognition engine and maintaining an updated lookup table. Japan's own e-passports are fine. It's the older paper passports from certain Southeast Asian and African nations where the errors cluster.
Get the Full Details

Limitations You Need to Know About
These systems are not foolproof. Damaged passports cause the biggest failure rate. Water damage, torn pages, faded ink — the OCR can't recover what isn't there. I'd estimate roughly five to seven percent of documents presented at these gates end up in manual review, and about half of those are simply because the passport is in bad shape. There's no software fix for that. You need a trained operator with a magnifier and patience. The second limitation is environmental. These readers are designed for controlled lighting and stable mounting. Portable setups, outdoor events, or check-in counters tend to underperform. The calibration drifts when temperature fluctuates. I've seen reading accuracy drop by twelve percentage points when ambient temperature shifted more than fifteen degrees Celsius in a single day. If you're evaluating this technology for a deployment, the honest assessment is that it works well for standard travel documents in controlled environments. It struggles with non-standard documents and degraded hardware conditions. For that use case, a hybrid approach where the automated gate handles clean documents and staffed counters manage the edge cases is the only reliable model. Pure automation claims you'll see in vendor brochures are optimistic at best.
The next generation of these systems is moving toward multimodal input — combining document reading with gait analysis and queue behavior monitoring. That's still experimental. The current generation does its job adequately if you understand where the bottlenecks are and plan around them. Nothing gamechanging yet, but the infrastructure is solid enough to build on.