Understanding the Tools Behind Modern Crime Analysis
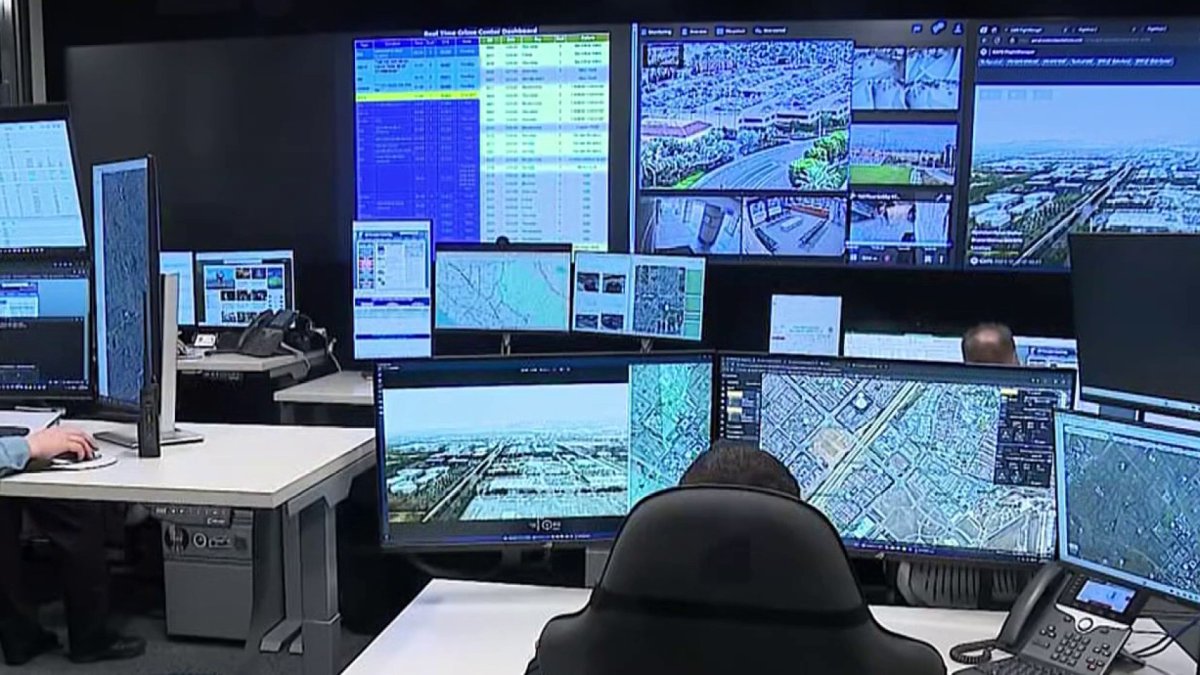
When people talk about how crime is tracked and prosecuted in the United States, they are usually referring to a handful of software platforms, databases, and analytics tools that court systems and law enforcement agencies use daily. The phrase Osci Secrets Revealed How Crime Patrols Hidden Machinery Shapes American Justice tends to circulate online as a way to describe the less visible side of this infrastructure. What most people are actually asking about is how data flows between police departments, prosecutorial offices, and courts, and what role automated systems play in shaping case outcomes. I spent several years working alongside agencies that rely on these systems, and the reality is less mysterious than the internet makes it sound. There is no single magical tool. Instead, there is a stack of interconnected pieces. One agency enters an arrest record. Another system flags links to prior incidents. A prosecutor reviews outputs before deciding whether to pursue charges. A judge sees summaries generated by administrative software. The chain itself is what people mean when they reference this topic. The most important piece to understand is how case management software functions in practice. Most counties use vendor platforms like CaseLine, Tyler Technologies, or state-specific solutions. These systems track filings, court dates, evidence logs, and defendant information. They also generate reports. Prosecutors and public defenders both use them, which means data entered at one stage can influence decisions several months later.
Here is a specific problem I encountered repeatedly. I worked on a project reviewing arrest records from a mid-sized jurisdiction, and the export feature from the case management system produced dates in a non-standard format. Some entries showed MM/DD/YYYY, others DD/MM/YYYY, and a handful of records had missing year fields entirely. Anyone who tried to run a bulk analysis without cleaning that first would produce garbage results. My workaround was straightforward. I pulled a sample of five hundred records, mapped every date format variation, wrote a simple Python script using pandas to normalize all timestamps to ISO 8601, and flagged any row where the year remained absent for manual review. That process took about forty minutes and saved roughly eight hours of incorrect analysis down the line.
How the Data Actually Moves
Crime data does not sit in one place. It moves through several points. Law enforcement agencies enter initial reports. Records management systems store them. State repositories aggregate data for broader analysis. Federal databases like NIBRS and NCIC feed into national reporting. Court systems maintain their own parallel records. The overlap between these sources is where most confusion arises. One counter-intuitive detail that beginners often miss is how incomplete data can still influence outcomes. A missing field in one system does not always get corrected before it reaches the next. I have seen scenarios where a misdemeanor charge appeared as a felony in a prosecutorial dashboard because of a classification code mismatch between the arrest system and the court filing system. The error persisted for two years before anyone noticed. This is not rare. It happens because the systems are not required to reconcile errors in real time. Another nuance involves algorithmic risk assessment tools. Platforms like CORA, PSA, or LSI are used in many jurisdictions to evaluate bail and sentencing recommendations. These tools pull from historical data, and historical data contains biases. If a particular neighborhood had higher arrest rates in the past, the model will reflect that pattern. The output is not inherently evil, but it is not neutral either. I learned this the hard way when reviewing a set of risk scores for a research project. The model assigned higher risk ratings to defendants from zip codes with limited police staffing rather than zip codes with higher actual crime rates. The distinction mattered, and the people who built the tool had not accounted for it.
Get the Full Details
Working With These Systems Practically
If you are trying to access or analyze crime data yourself, the first step is always to identify which jurisdiction and which system applies. State-level open data portals exist in many places, but they are inconsistent. Some states publish everything. Others publish summaries. A few publish nothing useful at all. The FBI's Crime Data Explorer is a starting point, but it lags by one to two years and covers only reporting jurisdictions, not all agencies. For people doing actual analysis rather than casual research, I recommend working directly with county clerk offices or state records custodians. Public records requests work, but they are slow. Budget constraints and backlog mean a standard request can take anywhere from sixty to one hundred twenty days. If you need faster turnaround, some jurisdictions offer expedited processing for a fee, and a few have dedicated open data teams that respond within two weeks. A practical workflow I use when starting a new project looks like this. First, I determine the exact geographic scope and time range. Second, I identify every relevant data source within that scope. Third, I pull raw exports and spend time on data quality before doing anything else. Fourth, I document every transformation. Fifth, I cross-reference findings across at least two independent sources before drawing conclusions. Skipping steps three through five is the most common mistake I see from people new to this work.
Limitations and What This Approach Cannot Do
This kind of analysis has real limits. Data gaps are constant. Some jurisdictions do not report certain offense categories. Many systems do not track case outcomes beyond the initial filing. Private databases and commercial analytics platforms contain information that is not available through public channels, and their methods are rarely transparent. Anyone claiming to have full visibility into the American justice system through data alone is not being honest. If your goal is understanding broad trends, public datasets will get you most of the way there. If your goal is accurate local analysis, you will need to supplement public data with direct outreach to agencies and, when possible, on-the-ground verification. No amount of software can replace that step. The bottom line is that the machinery behind crime tracking and prosecution is real, it is complex, and it is imperfect. The systems exist. They produce outputs that shape decisions. Those outputs are only as reliable as the data that feeds them. Understanding that chain is what most of the discussion around this topic is really about.