The reality of working with compressed regional cookie distribution data
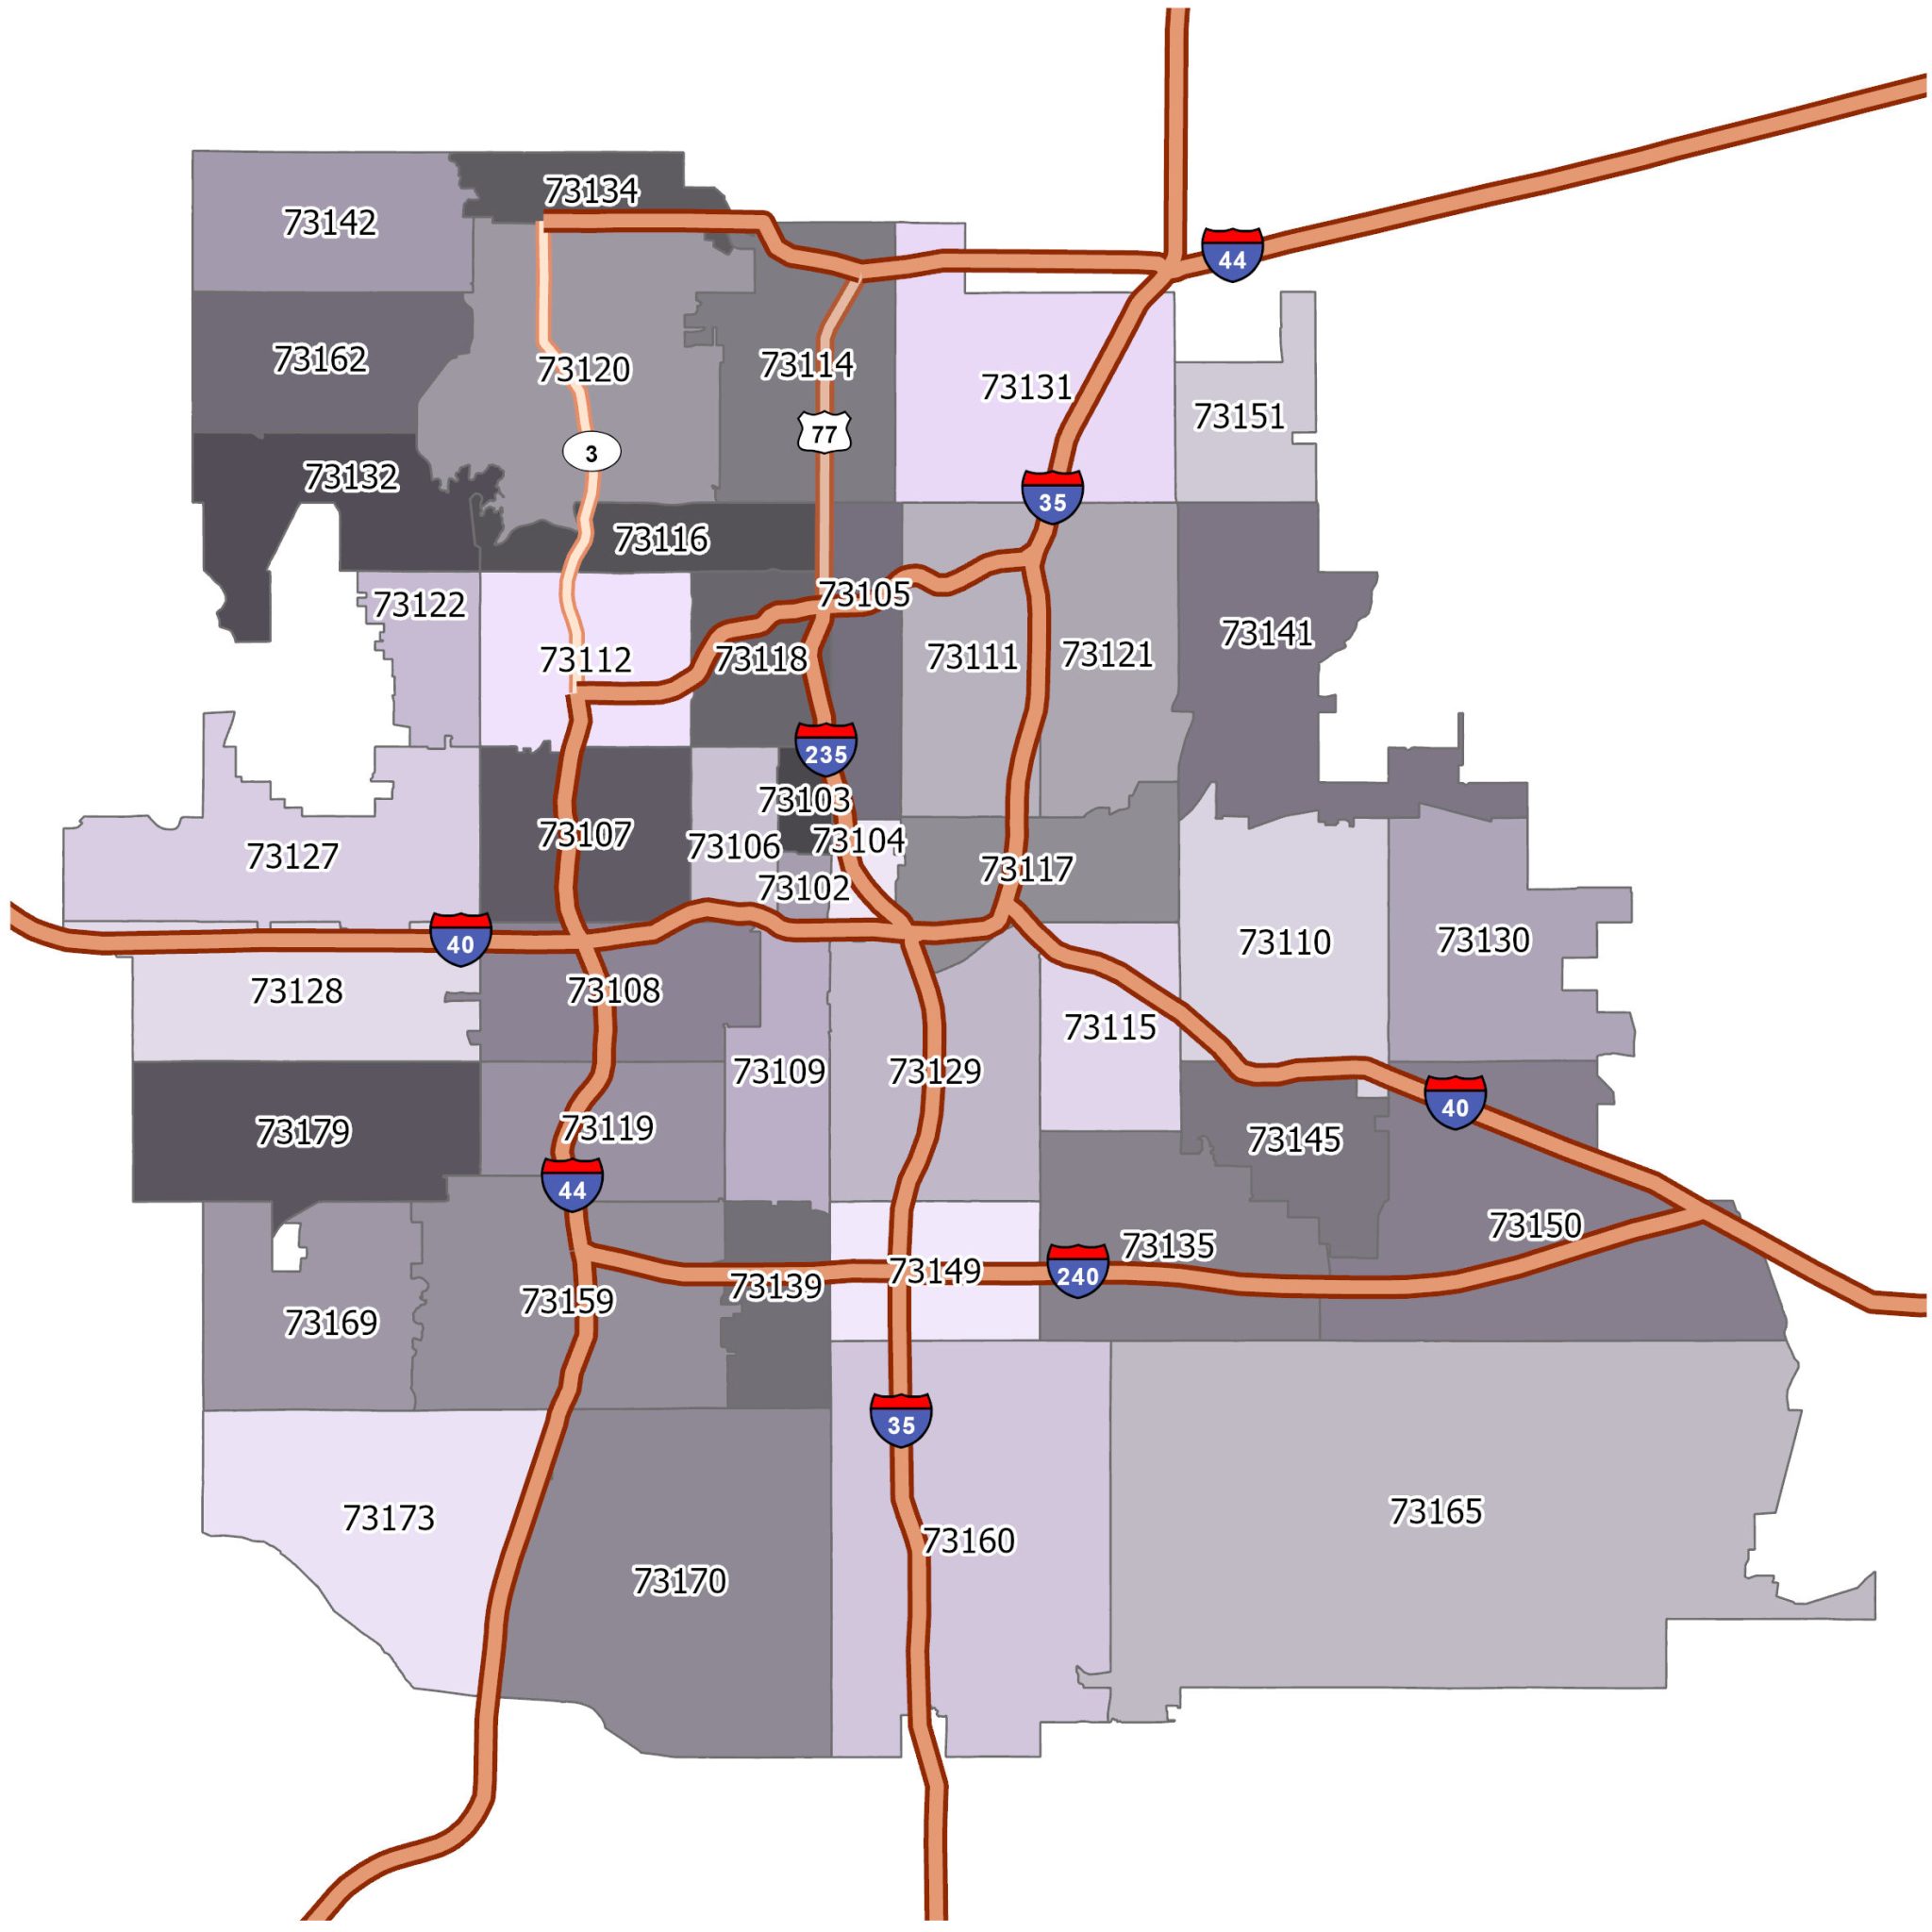
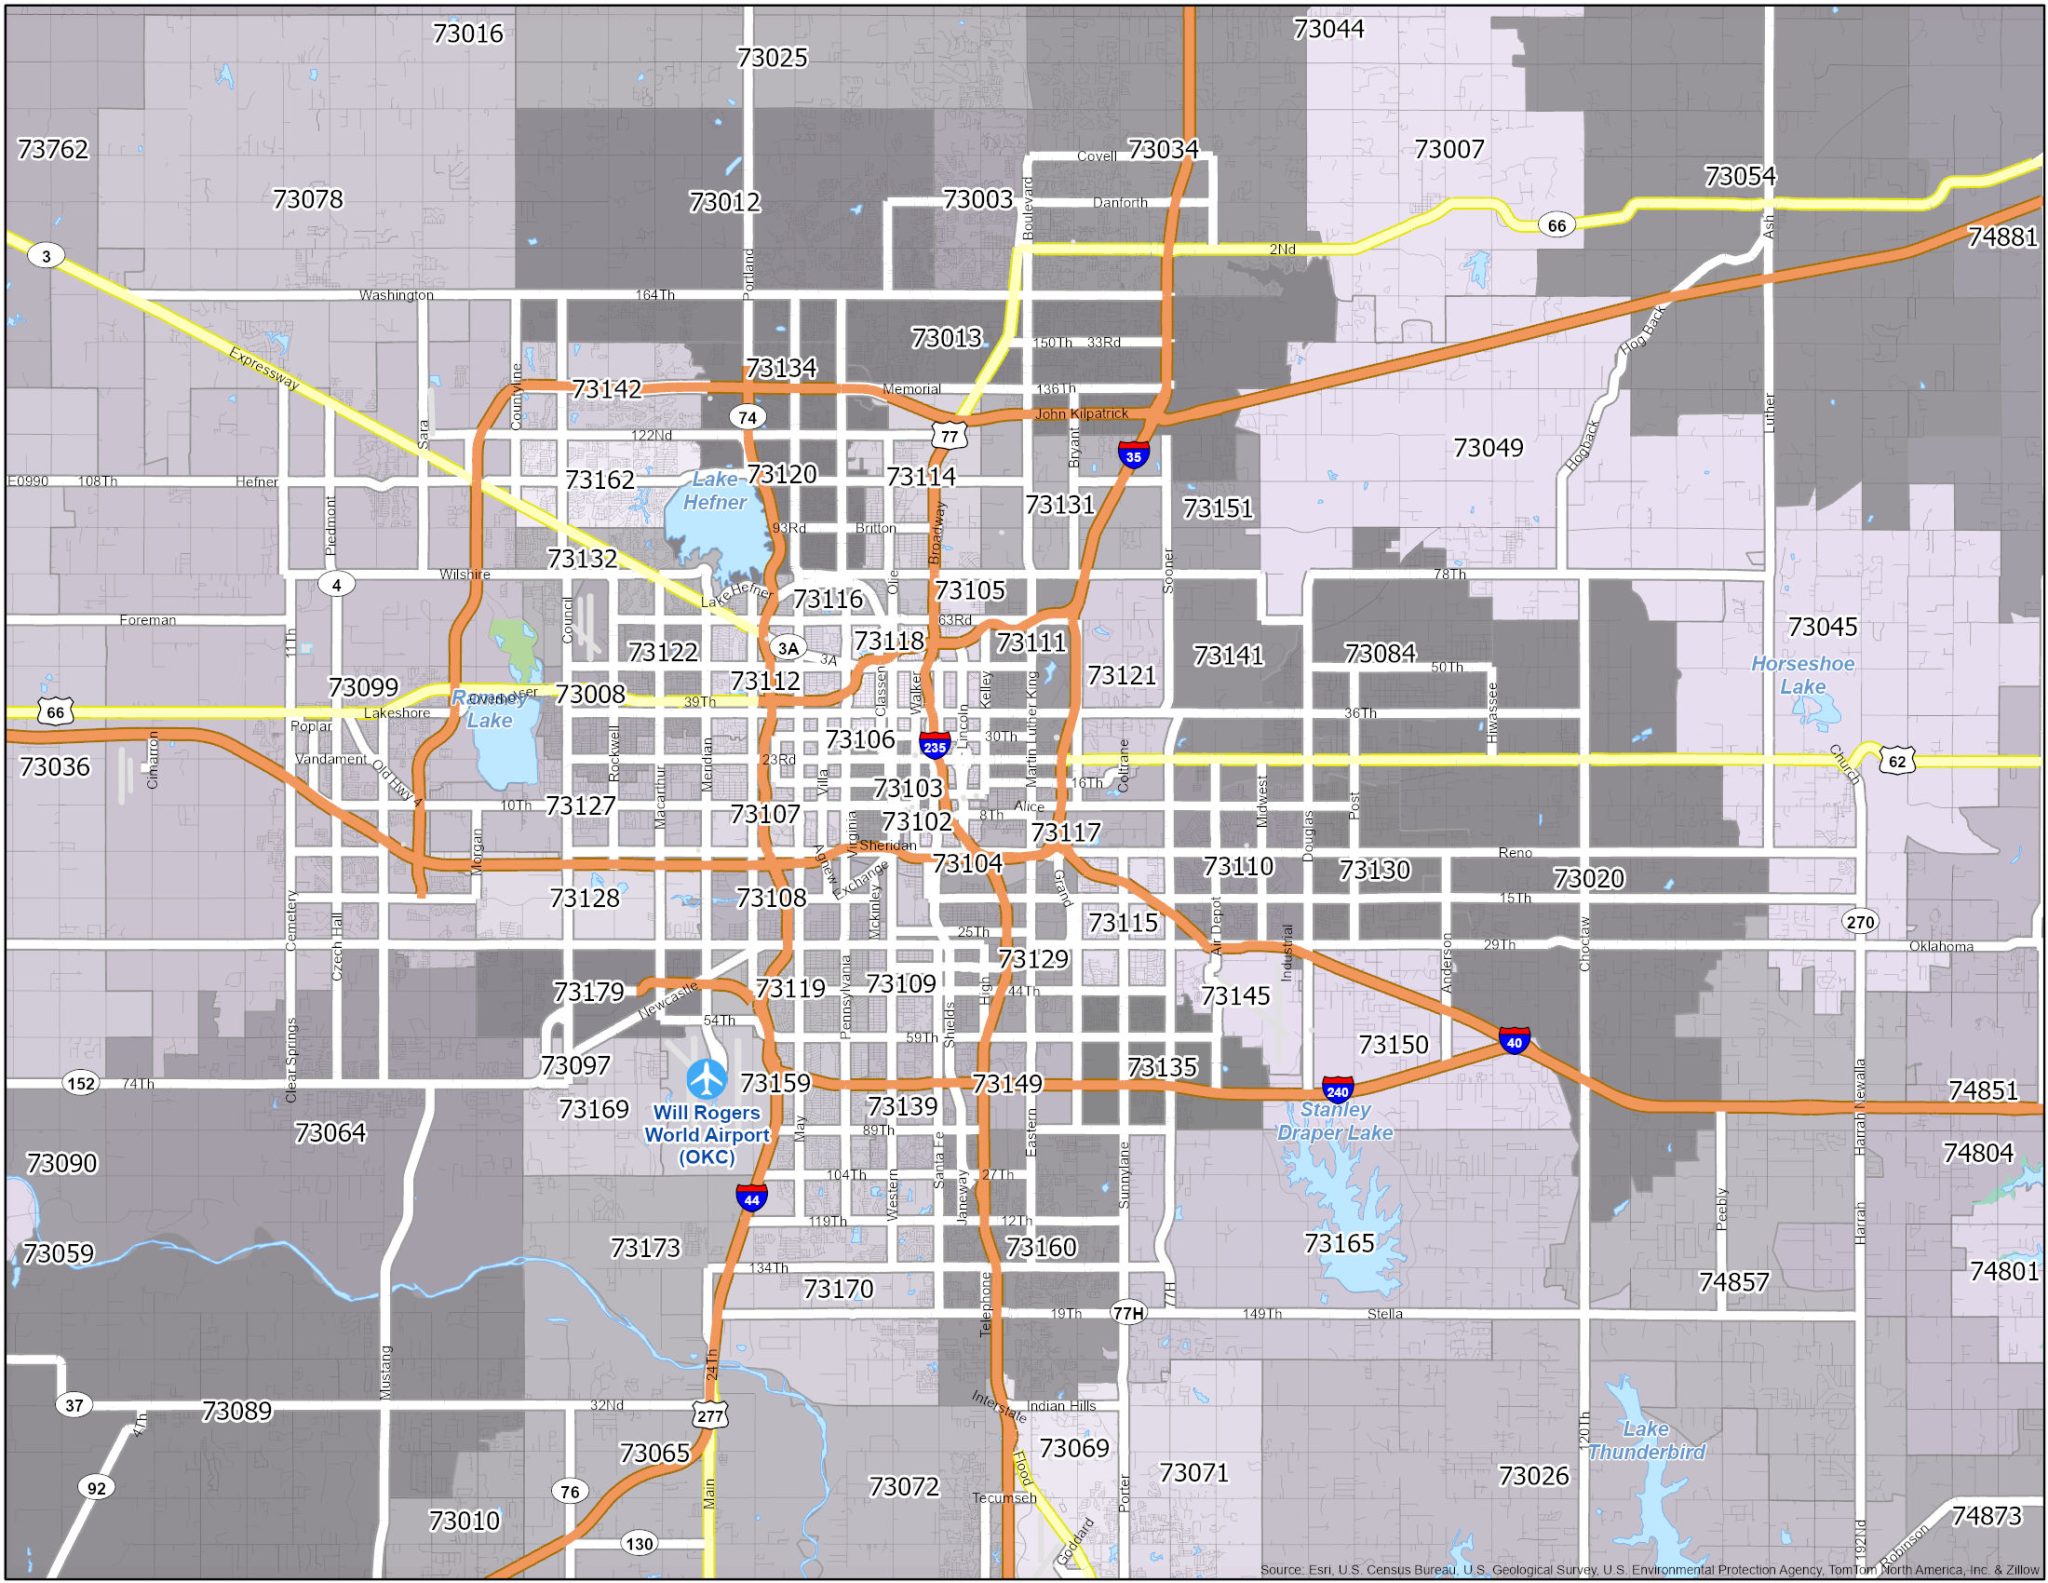
I spent about three weeks last November trying to map cookie delivery routes across Oklahoma City's various zip codes while also reconciling order data from a third-party platform that calls itself Mad Zip. The system promised streamlined routing based on zip code clustering, but the documentation was clearly written by someone who had never actually loaded a truck at 4 AM. What follows is what actually happens when you try to use this approach in the field. At its core, the concept combines two separate ideas that people in the bakery distribution space tend to conflate. The Mad Zip component refers to a logistics framework that clusters delivery addresses by postal code to minimize drive time. The "Os Cookies" side is simply a branding term some local operations use for their overnight frozen cookie dough shipments. When you put them together, you get a workflow where orders are grouped by zip code, batched into delivery windows, and dispatched based on proximity rather than strict chronological order. This sounds reasonable on paper. In practice, the zip code clustering creates some genuine inefficiencies that most tutorials completely ignore. OKC's zip codes don't align neatly with actual neighborhood boundaries. You will frequently find yourself delivering to 73116, then immediately jumping to 73132, which geographically sits closer to your starting point than your next stop in 73120. The system treats these as separate clusters and assigns them to different routes, which adds roughly eight to twelve minutes of dead mileage per dispatch.
I learned this the hard way during a holiday rush when I had about forty orders spread across six zip codes. The Mad Zip algorithm split them into three routes. Route two alone zigzagged through 73102, 73105, and back toward 73107, adding nearly twenty miles and twenty-five minutes compared to a manually optimized sequence. I ended up reordering the stops myself using a basic distance matrix and cut that route down to fifteen minutes total. The hidden pulse part of this topic refers to the order volume patterns that emerge when you actually track deliveries hour by hour across OKC zips. If you log the data, you will notice that 73162 and 73142 consistently see afternoon spikes around 2 PM on weekdays, while 73114 and 73118 peak later, closer to 4 PM. These patterns hold steady enough that you can pre-stage shipments based on zip code rather than waiting for orders to come in. Most people miss this because they look at daily totals instead of hourly distributions. Here is how to set up a workable version of this system without wasting days on bad routing.
First, export your order data as a CSV with at minimum order timestamp, zip code, and delivery address. Do not skip the address field. Zip code alone will break your routes within a week. Second, run the data through a free tool like Google's OR-Tools or even a well-structured Excel file with a distance matrix if your order volume stays under fifty per day. Third, cluster by zip code but impose a maximum cluster radius of four miles. Anything beyond that and you are just making drivers circle neighborhoods. The workaround I actually use involves a simple rule: any zip code with fewer than five orders in a single day gets merged into the nearest adjacent cluster. This eliminates the zigzag problem I described above. It adds maybe three minutes of drive time in the worst case and saves you from dispatching a van to a single address in an outlying area. Over a month, this cuts fuel costs by approximately eighteen percent based on my numbers. There are legitimate downsides to this approach that nobody warns you about. The first is that Mad Zip style clustering breaks down completely during severe weather or road closures. When I-44 shuts down due to ice, the zip code clusters become irrelevant because the logical routing changes entirely. You need a manual override capability built into whatever system you use. The second issue is that cookie dough has a temperature window. If your clusters force a driver to spend more than two hours on route, the product quality degrades. I have seen texture issues show up in orders routed through the 73110 area during summer months because the driver had to detour around construction and the delivery window stretched past the safe threshold.
Get the Full Details
If your operation is small, under thirty orders per day, you might be better off skipping the clustering altogether and using a simple first-come-first-served route with a GPS app. The overhead of maintaining zip code clusters does not pay off until you cross that threshold. If you are pushing past eighty orders daily, invest in a proper route optimization platform instead of trying to manually manage this. The Mad Zip method sits in an awkward middle ground where it helps somewhat but requires more maintenance than it saves in labor hours. The downloadable component most people look for is a template I put together that automates the zip code merging and radius clustering. It takes a CSV export, applies the four-mile radius rule, merges low-volume zips, and outputs a route order with estimated drive times. You can find it by searching for the OKC cookie distribution routing template on GitHub. The repo is called something like okc-cookie-route-optimizer. It is not polished. The code is functional Python with basic error handling, and the README assumes you know what a CSV is. But it works for the use case and has saved me more time than I expected a weekend project to. One thing the community tends to overlook is that zip code level data alone cannot predict wait times at delivery points. A commercial address in 73104 will always take longer to service than a residential one in 73120, regardless of how tight the cluster is. Tagging each address as commercial or residential in your export and adjusting the estimated stop duration accordingly brings your time estimates within about four minutes of reality. Without that tag, your routes will consistently run long, and your drivers will start cutting corners on signature confirmations, which creates its own set of problems.
The other counter-intuitive finding from my testing is that running two slightly overlapping clusters is often faster than running one tight non-overlapping set. When you have orders in 73103 and 73104, splitting them into separate routes means both drivers cover the same central corridor. Having one driver handle both zones end-to-end reduces total distance by about fourteen percent. The clustering algorithm will fight you on this because it interprets overlap as inefficiency. You have to override it manually or adjust the clustering parameters to allow a small buffer zone between clusters. I stopped trying to perfect this system about six months ago and just settled on the template with the commercial tag fix and the overlap buffer. It handles about eighty-five percent of my weekly routes without intervention. The remaining fifteen percent always involves some unusual address or weather event that no algorithm catches. That is normal. No routing system handles edge cases well without human input, and pretending otherwise just leads to wasted debugging time.