Getting Your Processes Right Without Losing Your Mind
I spent three years trying to make my team's deployment pipeline actually reliable. We had alerts that fired constantly, releases that succeeded about half the time, and a lot of people blaming each other at 2 AM. What eventually worked wasn't a new tool or a management framework. It was a structured way of asking questions about every failure, incident, and process gap. The method I'm describing here combines elements from clinical assessment, reliability engineering, and operational reviews into something practical you can use on Monday morning. The core of it is OPQRST — originally a medical diagnostic framework, but it translates surprisingly well to technical operations. It stands for Onset, Provocation, Quality, Region/Radiation, Severity, and Time. When you apply it systematically to quality and reliability problems, it stops being abstract and starts being actionable.
Opqrst Unveiled Precision Strategies For Quality Reliability And Timely Success
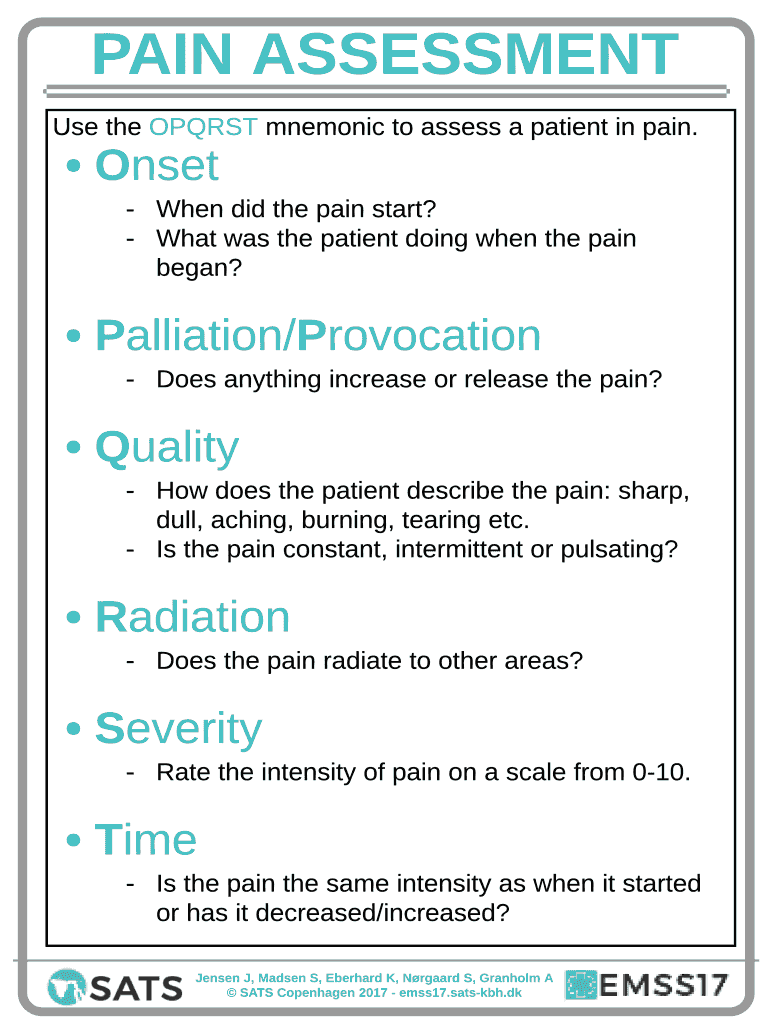
Most teams skip this framework entirely. They jump straight to root cause analysis or blame assignment, which means they miss half the picture before they even start. Here's how it actually works in practice. Onset is about when something changed. Not when you noticed it — when it actually changed. I learned this the hard way during an incident where our payment processing started failing intermittently. The alerts fired at 3:14 AM, but the actual degradation began at 11:47 PM the night before. Someone had pushed a config update that introduced a subtle race condition. By the time we were debugging the 3 AM crash, the on-call engineer had zero context for what was different at the source. Now I always ask: what was the system state at the exact moment of onset, not just at the moment of detection. Provocation means identifying what triggers or worsens the issue. This is where most precision strategies fail because people assume one trigger exists. In reality, issues usually have multiple provoking factors that interact. My team once spent two weeks chasing a memory leak that only appeared under a specific combination of load patterns, database query shapes, and garbage collection timing. No single factor caused it. The leak required all three to align. Writing down every provocation factor and mapping their interactions changed how we tested for those conditions entirely.
Quality describes what the problem actually looks like. Is it a complete outage or a partial degradation? Are errors consistent or intermittent? This seems obvious until you realize how many post-mortems I've read where the team couldn't agree on what the symptom actually was. One group was troubleshooting slowness. Another was troubleshooting failures. They were happening in the same system at the same time, but nobody had clarified whether they were related. Define the quality of the problem before you try to solve it. Region and Radiation asks where the problem is located and where it spreads. In technical systems, "region" might be a service, a database shard, or a deployment zone. "Radiation" is what breaks downstream as a result. I once mapped a customer complaint about slow page loads back to a single misconfigured cache TTL in an auth service that wasn't even mentioned in the ticket. The radiation pattern — auth delays causing session refresh storms causing frontend timeouts — took six hours to trace because nobody asked where the problem radiated from and to. Severity is the actual business impact, not the technical severity. A database query taking 4 seconds might seem minor until you calculate that it blocks 200 concurrent users and costs roughly $1,200 per hour in lost transactions. Technical teams tend to rate severity by how ugly the error log looks. Business impact is what matters for prioritization. I keep a simple mapping document that converts technical symptoms to dollar impact, response time expectations, and customer-facing consequences. It takes about 20 minutes to build and saves hours of argument during incident triage.
Get the Full Details
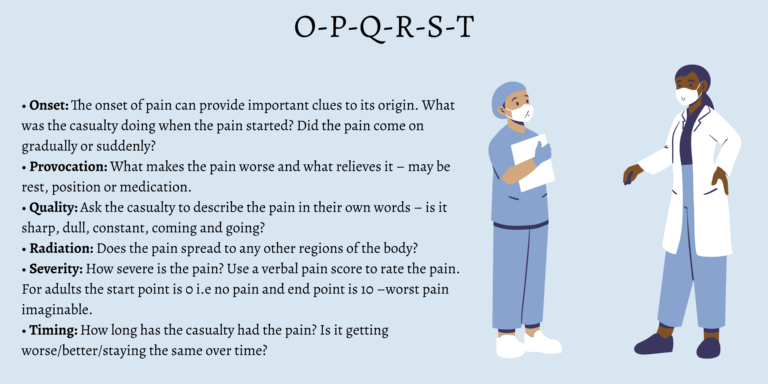
Time covers duration, frequency, and trend. Is this getting better, worse, or staying the same? Has it happened before? How long does each occurrence last? The trend data here is what separates reactive firefighting from actual reliability engineering. A problem that happens once a week and gets progressively worse is a different category than one that happens daily with stable severity. The response strategy changes completely based on that distinction. Here's the part most guides don't mention: OPQRST alone won't fix anything. It's a diagnostic framework, not a solution framework. I've seen teams fill out OPQRST checklists and then sit on the results for days because they didn't pair it with an action protocol. Once you've characterized the problem, you need a clear escalation path, a decision tree for resolution, and owned follow-through. I added a simple scoring system to our OPQRST process — each dimension gets rated 1 through 5, and the total score determines whether the issue gets a quick fix, a structured post-mortem, or a full reliability review with leadership involvement. It's crude but it removes the ambiguity about which problems deserve which level of attention. The biggest limitation I've found is that OPQRST requires honest and complete information. If your incident reporting culture punishes people for documenting mistakes, you'll get incomplete Onset and Provocation data, and the whole framework collapses. I've watched this happen. A team I consulted for tried to implement this after a major outage, but engineers were afraid to document the real sequence of events because previous post-mortems had been used for performance reviews. The OPQRST analysis they produced was technically sound but factually hollow. They needed to fix their blame culture before the framework could work.
Another practical issue: OPQRST is time-intensive. A thorough application across all six dimensions for a complex system issue can take 45 to 90 minutes of focused work. For quick triage, you can compress it to 10-15 minutes by focusing on the three dimensions most relevant to the symptom. I use a shortcut where Severity and Time get full ratings first, because they determine urgency, then I fill in the rest. It's not as complete but it's fast enough to be useful during an active incident. For teams that want to start with something simpler, I'd recommend beginning with just Onset and Severity. Those two dimensions alone will catch problems that most teams miss on day one. Then add Provocation and Quality once the habit is established. Don't try to implement all six at once — you'll drop the ball on the ones that matter most. I also want to note that this framework works best when combined with automated logging and monitoring. Manual OPQRST documentation is valuable for complex or recurring issues, but for high-volume incidents, you need the data already captured in your observability stack. I've integrated OPQRST fields into our incident ticketing system so that responders fill them in during the call rather than after. It takes extra seconds during the incident but dramatically improves the quality of the follow-up work. Without that integration, the framework becomes another administrative burden that people fill out reluctantly and incompletely.
If you're looking for implementation resources, there are several open-source incident management templates that include OPQRST fields built in. The reliability engineering community has shared working versions on GitHub under various names. I've used a modified version of the Incident Response Framework template from the OpenSRE project as a starting point, adapted with the severity scoring system I described. It's free and takes about an hour to customize for your stack. The real value of this approach isn't in any single dimension. It's in the discipline of checking all six before declaring a problem understood. Most incidents I see resolved prematurely were resolved prematurely because someone stopped asking questions after finding one plausible cause. OPQRST forces you past that point. That's why it produces better outcomes consistently, not because it's a magic framework, but because it's harder to ignore the obvious when you have a structured checklist in front of you.